
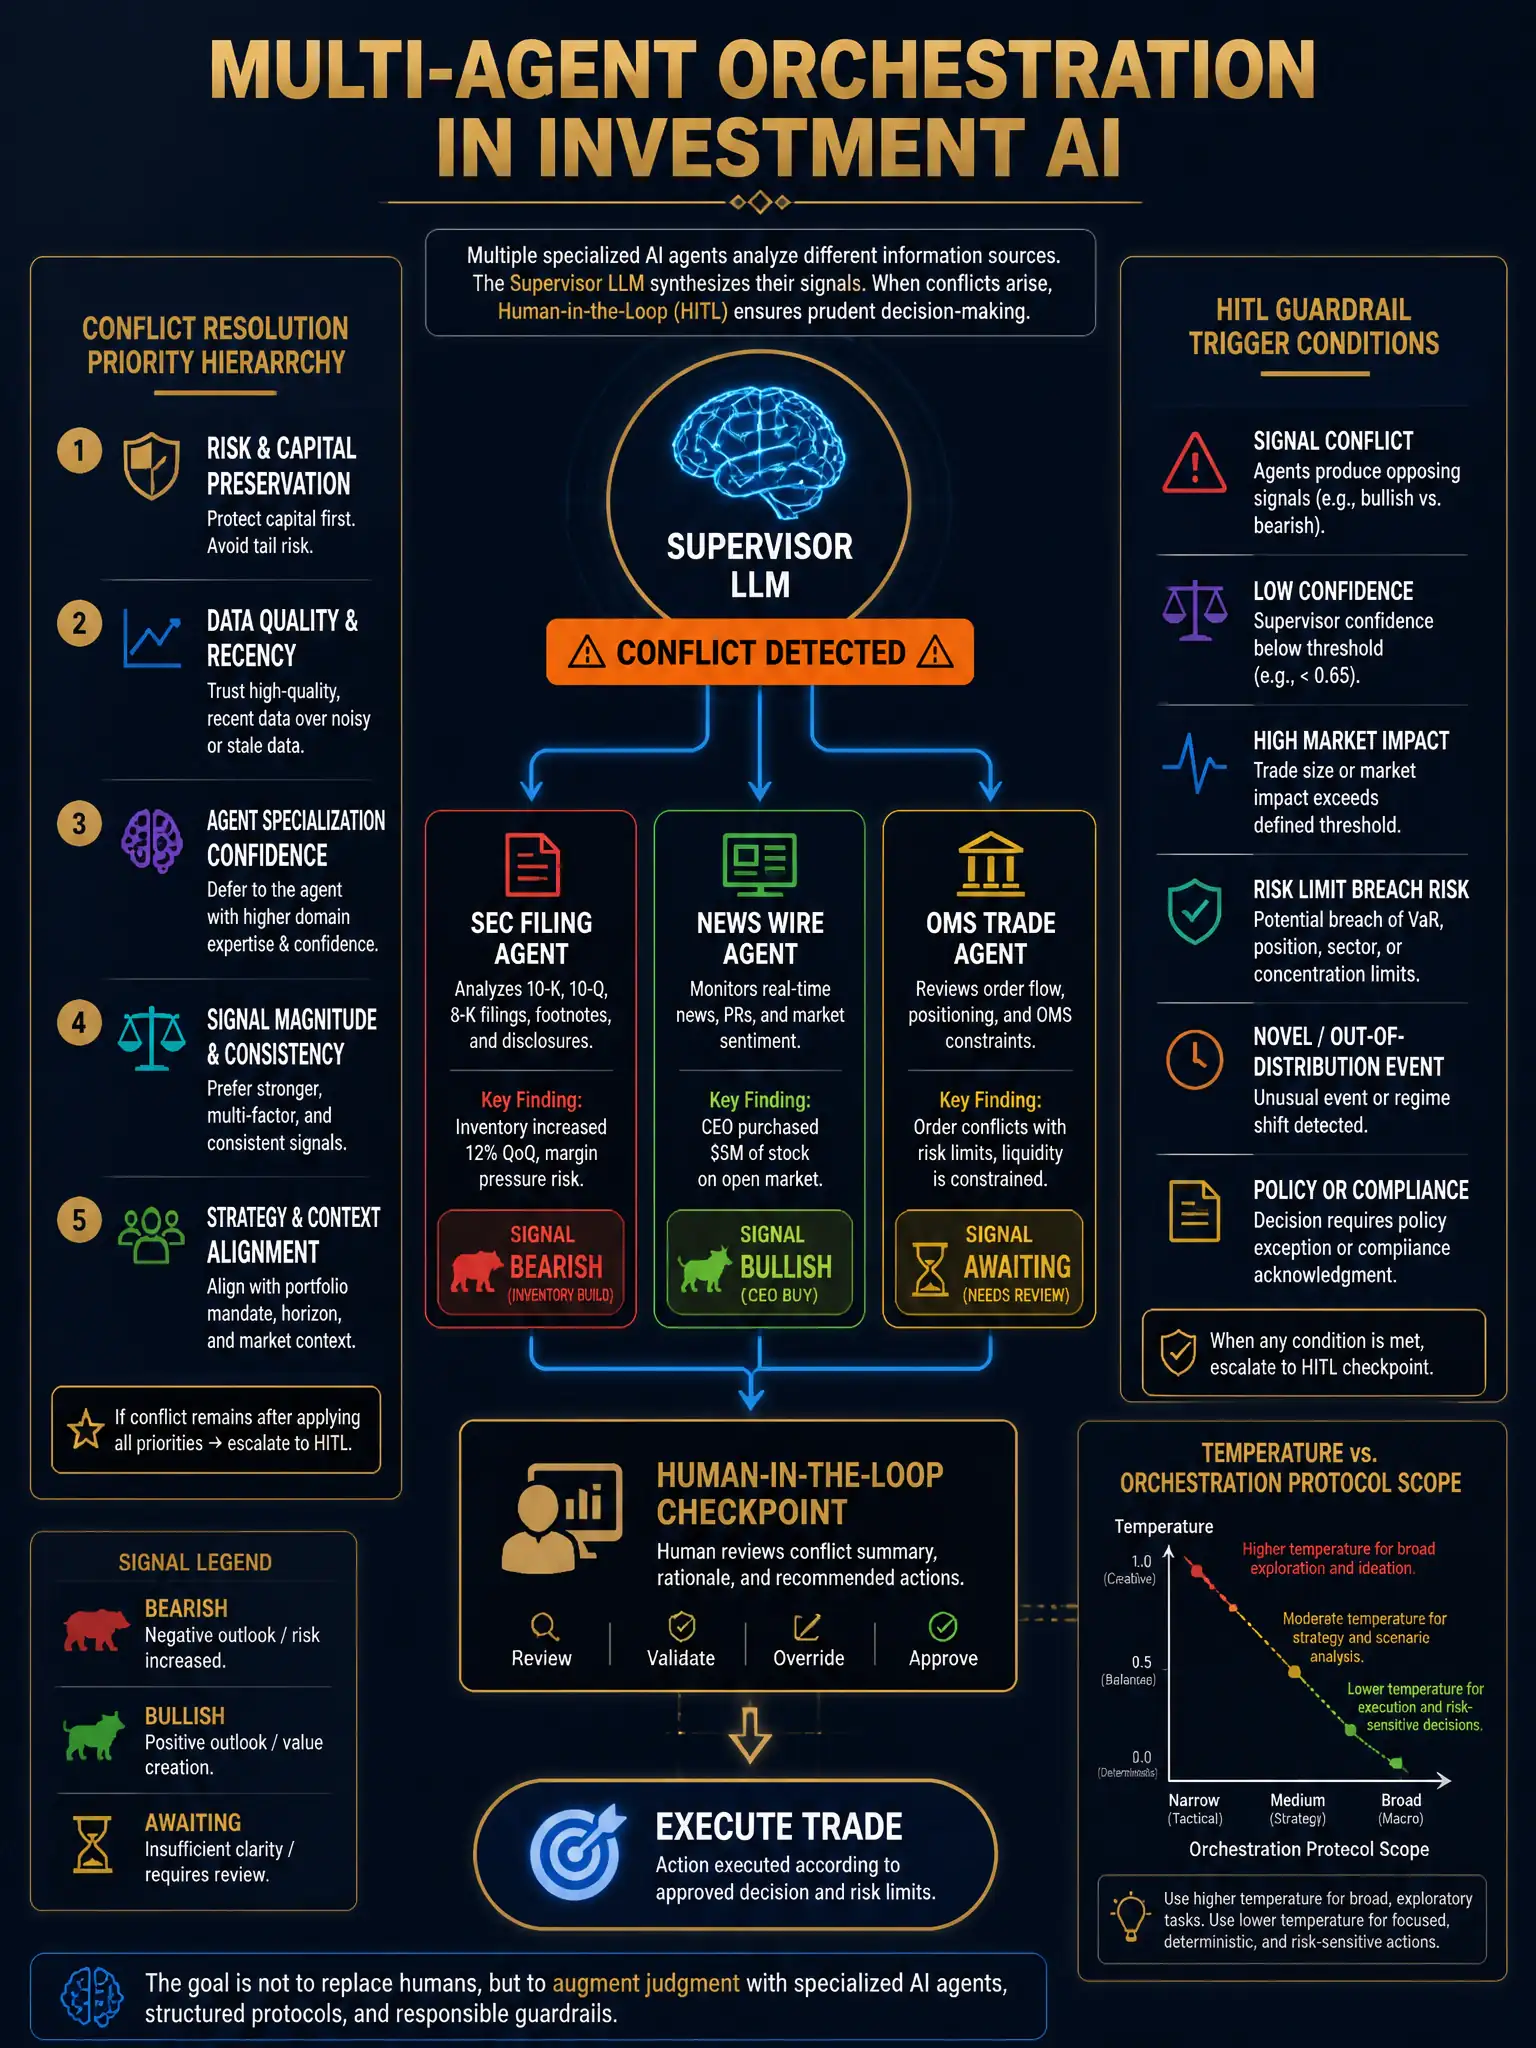
A systematic hedge fund deploys an agentic AI framework in which a supervisor LLM coordinates three specialized sub-agents: one ingests SEC filings in real time, one monitors financial news wires, and one interfaces with the order management system to execute pre-approved trade workflows. During an earnings miss event, the supervisor receives conflicting signals — the filing agent reports a significant inventory build, the news agent detects an insider purchase by the CEO, and the trade agent signals readiness to execute a short position. Which architectural concern MOST directly determines whether this multi-agent system behaves safely and coherently under conflicting inputs?
Select an answer to reveal the explanation.
Short Explanation
Think of the supervisor LLM as a trading floor manager getting three traders shouting different things at once. Without a clear rulebook for who wins when signals conflict — and a compliance officer who must sign off before anything is executed — you've got a recipe for a rogue trade. The orchestration protocol's conflict-resolution logic, priority hierarchy between agents, and human-in-the-loop guardrails before trade execution are the safety net.
Full Explanation
In multi-agent AI frameworks for investment applications, the orchestration layer — not individual model parameters — is the primary determinant of system-level safety. When sub-agents return conflicting signals (bearish fundamentals versus bullish insider activity), the supervisor must apply a deterministic conflict-resolution protocol: for example, a priority hierarchy that routes to a human decision-maker when fundamental and sentiment signals diverge beyond a defined threshold. Without this, the supervisor may act on whichever signal arrived last or scored highest by an arbitrary heuristic, leading to incorrect trade execution.
Human-in-the-loop guardrails are particularly critical for irreversible actions. Trade execution is an action with real profit and loss consequences; best-practice agentic design requires that any agent capable of triggering an external side-effect (order placement, capital commitment) sit behind an approval gate rather than being reachable in a fully autonomous chain.
Why the other options fail: The temperature setting of the supervisor LLM, which controls output randomness and must be set below 0.3 for financial applications, controls stochasticity in text generation but does nothing to resolve semantic conflicts between structured signals from specialized agents — this is an inference parameter, not an orchestration control. The total token count allocated to each sub-agent's system prompt, which constrains how much context each agent can process, affects what each agent can read and reason over, but it doesn't define how contradictions are reconciled at the supervisor level. Whether the shared embedding model uses cosine similarity or dot-product similarity when routing signals to sub-agents governs retrieval quality in retrieval-augmented generation pipelines; it is irrelevant to the conflict-resolution semantics of an agentic orchestration protocol.
The relevant frameworks here include LangGraph's conditional edge logic for agent routing, AutoGen's termination and human-proxy patterns, and the broader principle from NIST AI RMF that high-stakes automated systems require explicit human oversight checkpoints before consequential actions are taken.