
An asset management firm builds a Retrieval-Augmented Generation (RAG) system to answer portfolio manager questions using 10 years of internal analyst reports stored in a vector database. During user acceptance testing, the system consistently surfaces semantically similar but temporally outdated documents — for example, returning a 2015 sector analysis for a company that has since divested its core business and pivoted to a new industry. The embedding model scores these stale documents highly because topic vocabulary has not meaningfully changed. Which combination of techniques BEST addresses this temporal drift problem in a production financial RAG system?
Select an answer to reveal the explanation.
Short Explanation
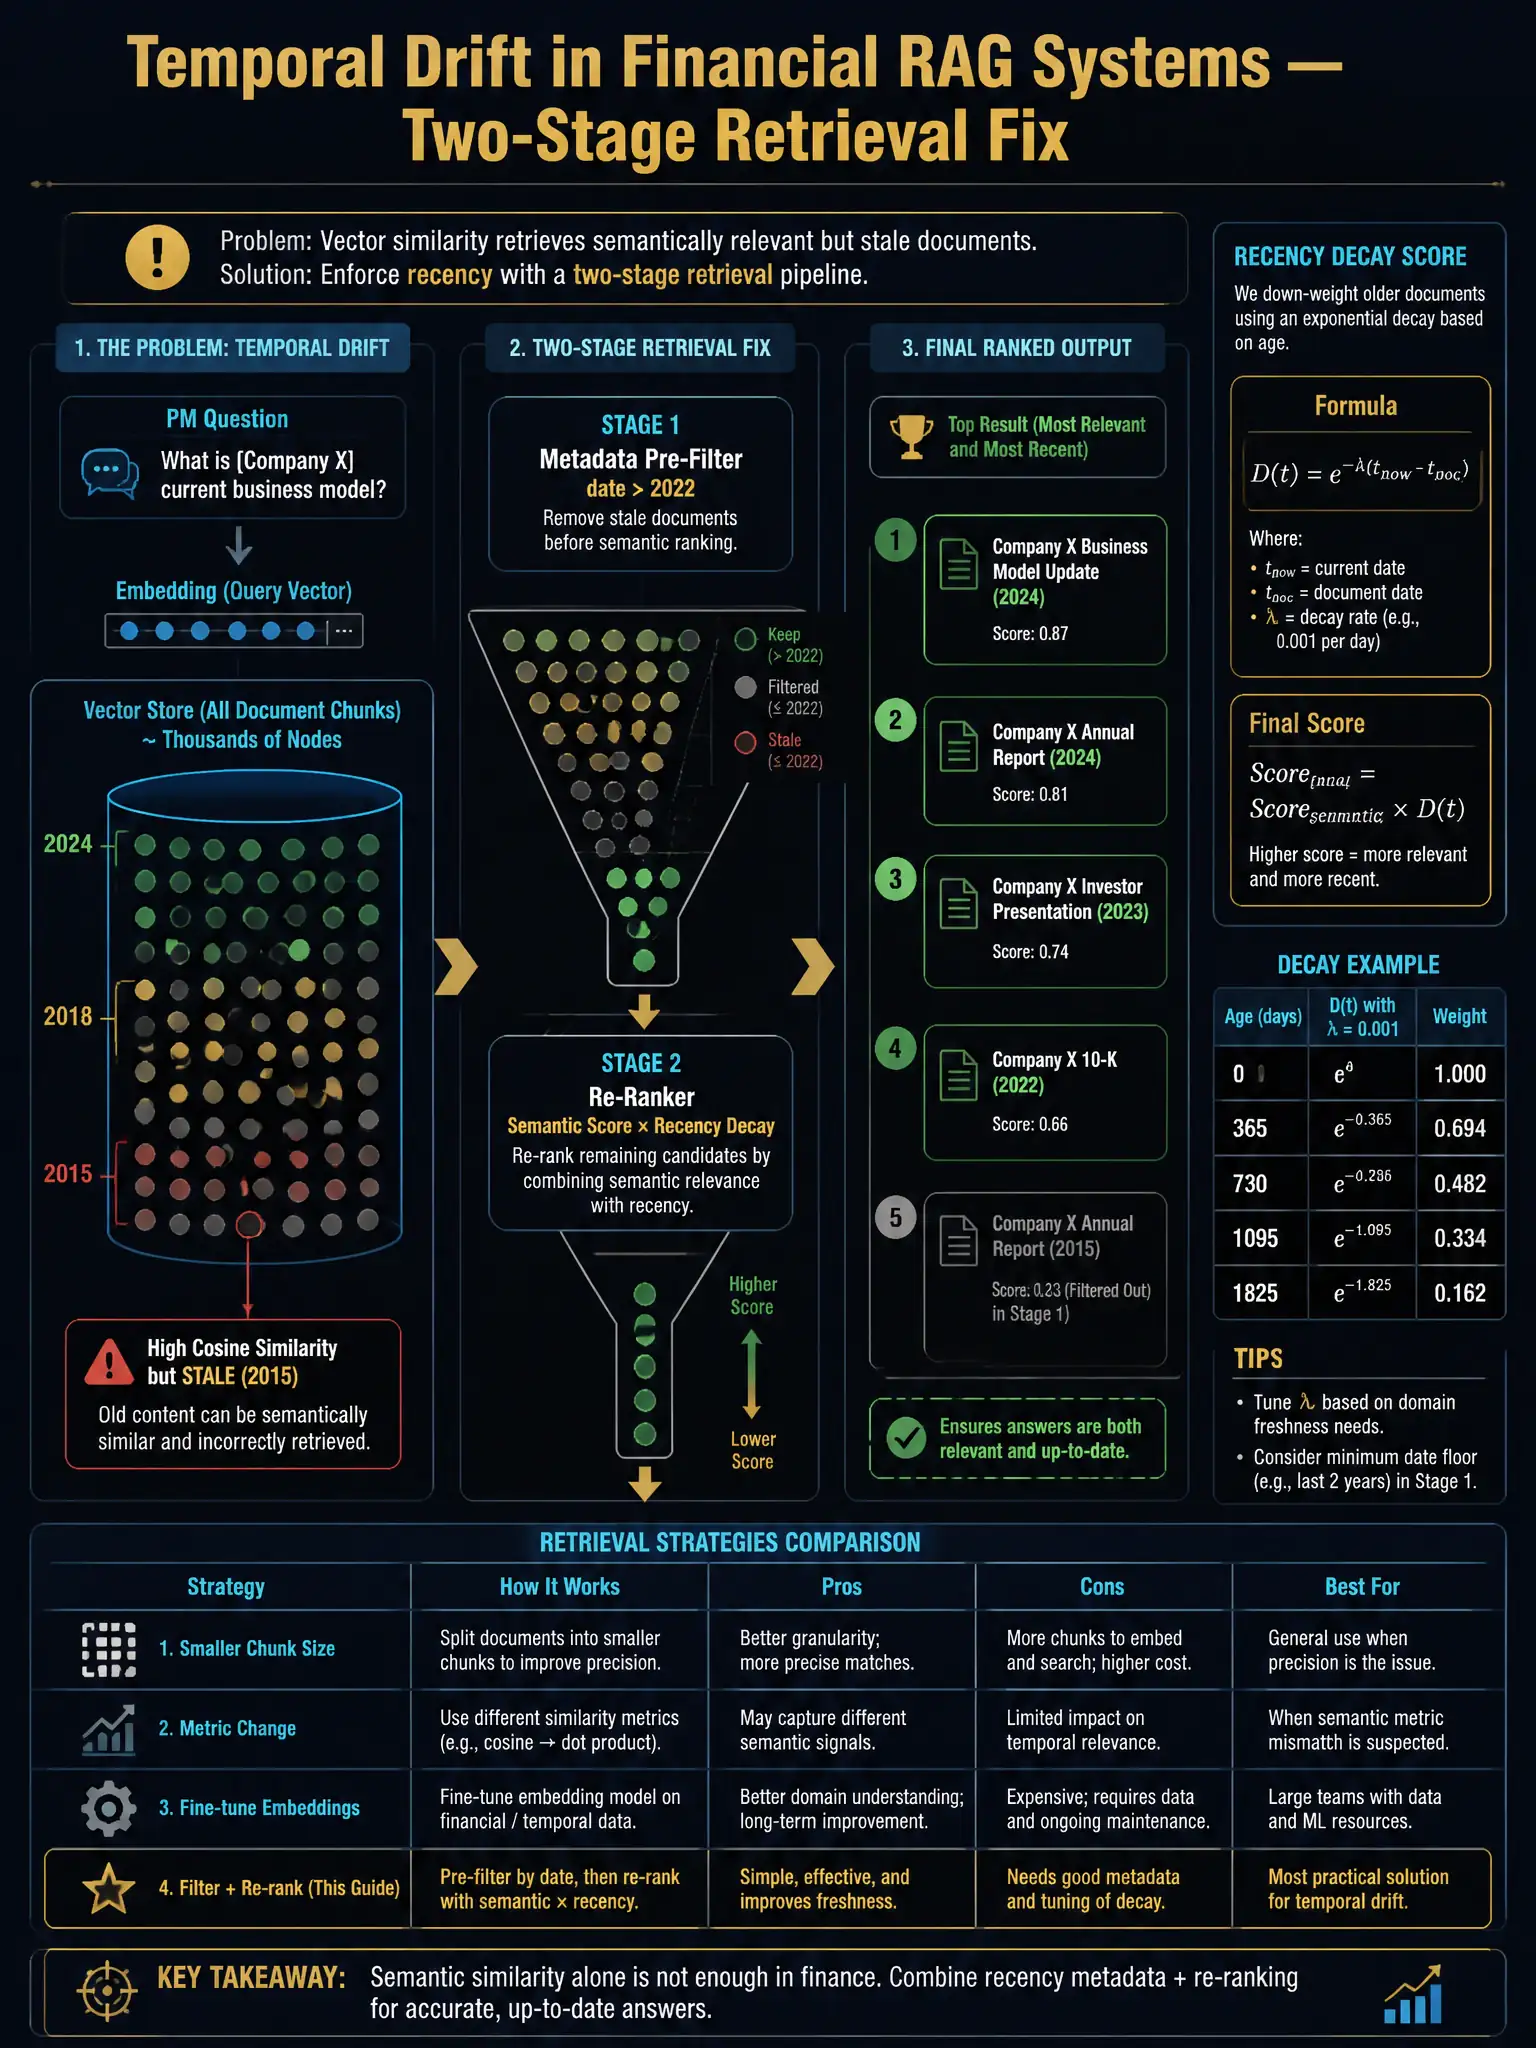
Embedding models are great at semantic similarity but completely blind to 'this report is 10 years old.' You fix it by filtering on document date before vector search, then re-ranking with semantic relevance and recency decay. Think of it as putting a freshness gate on the retrieval conveyor before the LLM gets to read anything.
Full Explanation
Vector embeddings encode semantic content but carry no intrinsic temporal ordering — a 2015 analyst report and a 2024 update on the same company may produce nearly identical embedding vectors if they use the same industry vocabulary. This is the core of temporal drift in financial RAG: the retrieval step cannot distinguish freshness without auxiliary signals.
The best answer is applying metadata pre-filtering by document date to restrict the candidate set, then adding a re-ranking step that scores retrieved chunks by both semantic relevance and recency. The pre-filter stage restricts the candidate pool using structured metadata — document date, author, publication type — stored alongside the embedding vectors. Most production vector stores (Pinecone, Weaviate, Qdrant, Chroma) support metadata filters that execute before approximate nearest neighbor search, dramatically reducing the risk of stale content entering the result set. The re-rank stage applies a cross-encoder or custom scoring function that weights both semantic relevance and a recency decay signal, such as an exponential decay over document age. This is the standard retrieve-then-re-rank architecture recommended in production RAG systems.
Why the other approaches fail: Increasing the document chunk size to 4,096 tokens improves context capture but does nothing to surface recency information — the embedding model still cannot distinguish publication dates from content alone. Switching the vector store's similarity metric from cosine similarity to Euclidean distance is a mathematical preference for high-dimensional spaces; neither metric encodes temporal information, and switching between them does not address the staleness problem. Fine-tuning the embedding model annually on the full document corpus might gradually shift the model's latent space, but it is expensive, risks catastrophic forgetting of important historical patterns, and still does not give the model an explicit mechanism to prioritize recency — metadata filtering is far more deterministic and auditable, which matters for fiduciary applications.
In production financial RAG systems, the metadata layer also supports compliance use cases: audit trails can show which documents were retrieved and why they were included or excluded, providing explainability for research-backed investment decisions.