
What is the architectural benefit of supporting multiple query engines over one shared set of governed data?
Select an answer to reveal the explanation.
Short Explanation
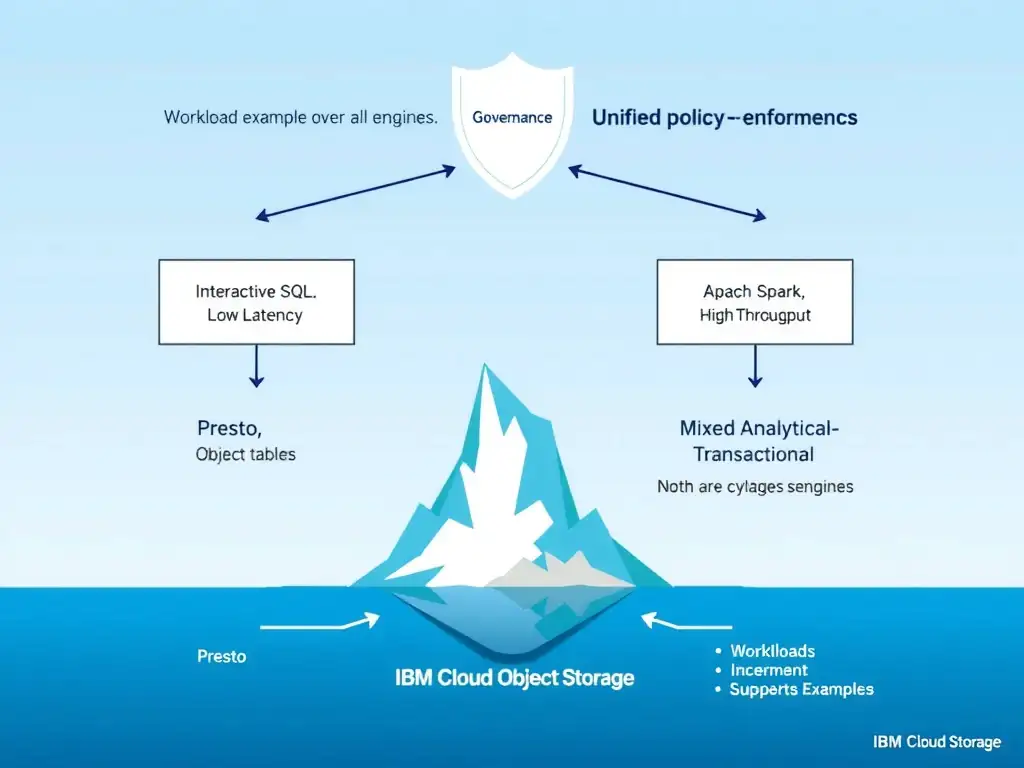
You get the right compute for each workload without splitting the data into copies. The shared governed copy and shared catalog are what make it work, not things you skip.
Full Explanation
The workload-suited engine over one governed copy is correct because multi-engine support decouples workload-appropriate compute from data storage. Teams gain the right tool for each job without the estate splitting into copies. The per-engine access policies answer is incorrect and inverts the model: per-engine policies would be inconsistent and would make engine choice a way around governance. Policy is applied once to the data. The no-catalog answer is incorrect because a shared catalog is what makes multiple engines see the same tables; removing it would fragment the estate. The per-engine storage format answer is incorrect because a shared open format is the mechanism enabling this; per-engine formats would mean per-engine copies. For the exam, the value is workload-appropriate compute over one governed copy.