
A program manager builds a Copilot prompt to triage feedback from three sources: Zendesk exports, App Store reviews, and beta surveys, using placeholders for each file. Which approach best defines the data to be acted on and input variables for reliable results?
Select an answer to reveal the explanation.
Short Explanation
You keep Zendesk exports, App Store reviews, and beta surveys clear by giving each source its own named variable. Add the format, scope, and date range, and you can guide Copilot to handle every file reliably.
Full Explanation
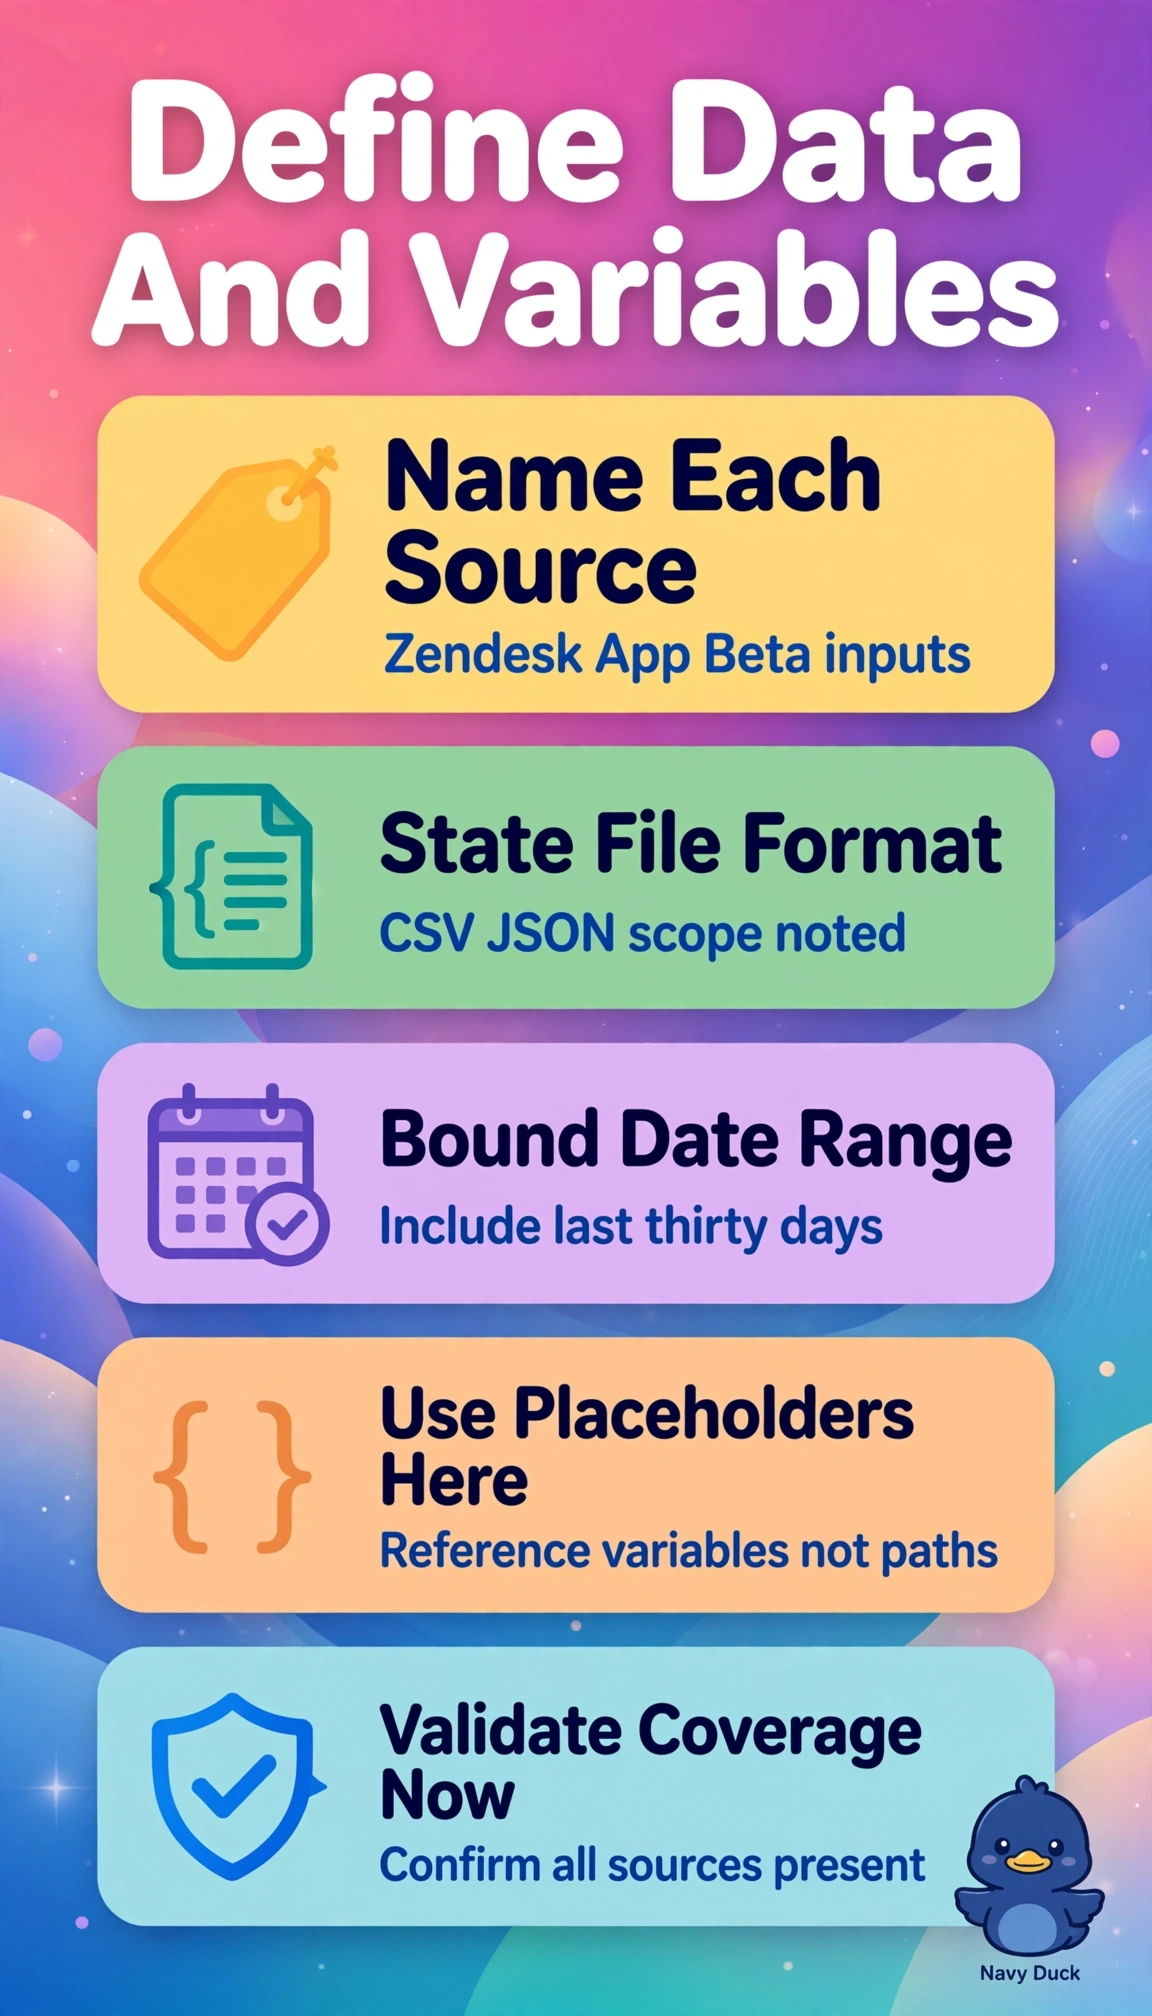
Reliable triage requires declaring Zendesk exports, App Store reviews, and beta surveys as separate named input variables and specifying each source’s format, scope, and date range. Together, these details establish data lineage, prevent source confusion, and constrain Copilot to the intended files and time window. Putting all feedback into one consolidated variable, even with format, scope, and dates, sacrifices provenance: source attribution is needed to weight, deduplicate, and compare channels, and blending them can make themes difficult to trace. Naming each source and specifying format and date range but omitting scope leaves inclusion criteria undefined, so Copilot may treat unrelated tickets or versions as relevant and generalize beyond the intended feedback. Naming each source with scope and date range but omitting format weakens ingestion reliability: Zendesk CSV exports, store review feeds, and survey JSON can parse differently, risking truncation, misaligned fields, or misinterpreted ratings. Exam caveat: when a prompt emphasizes placeholders for each file and reliable results, favor precise, separate definitions over the apparent efficiency of consolidation. Practical check: before execution, verify that the prompt shows three named variables, each followed by its expected file type, population definition, and coverage dates.