
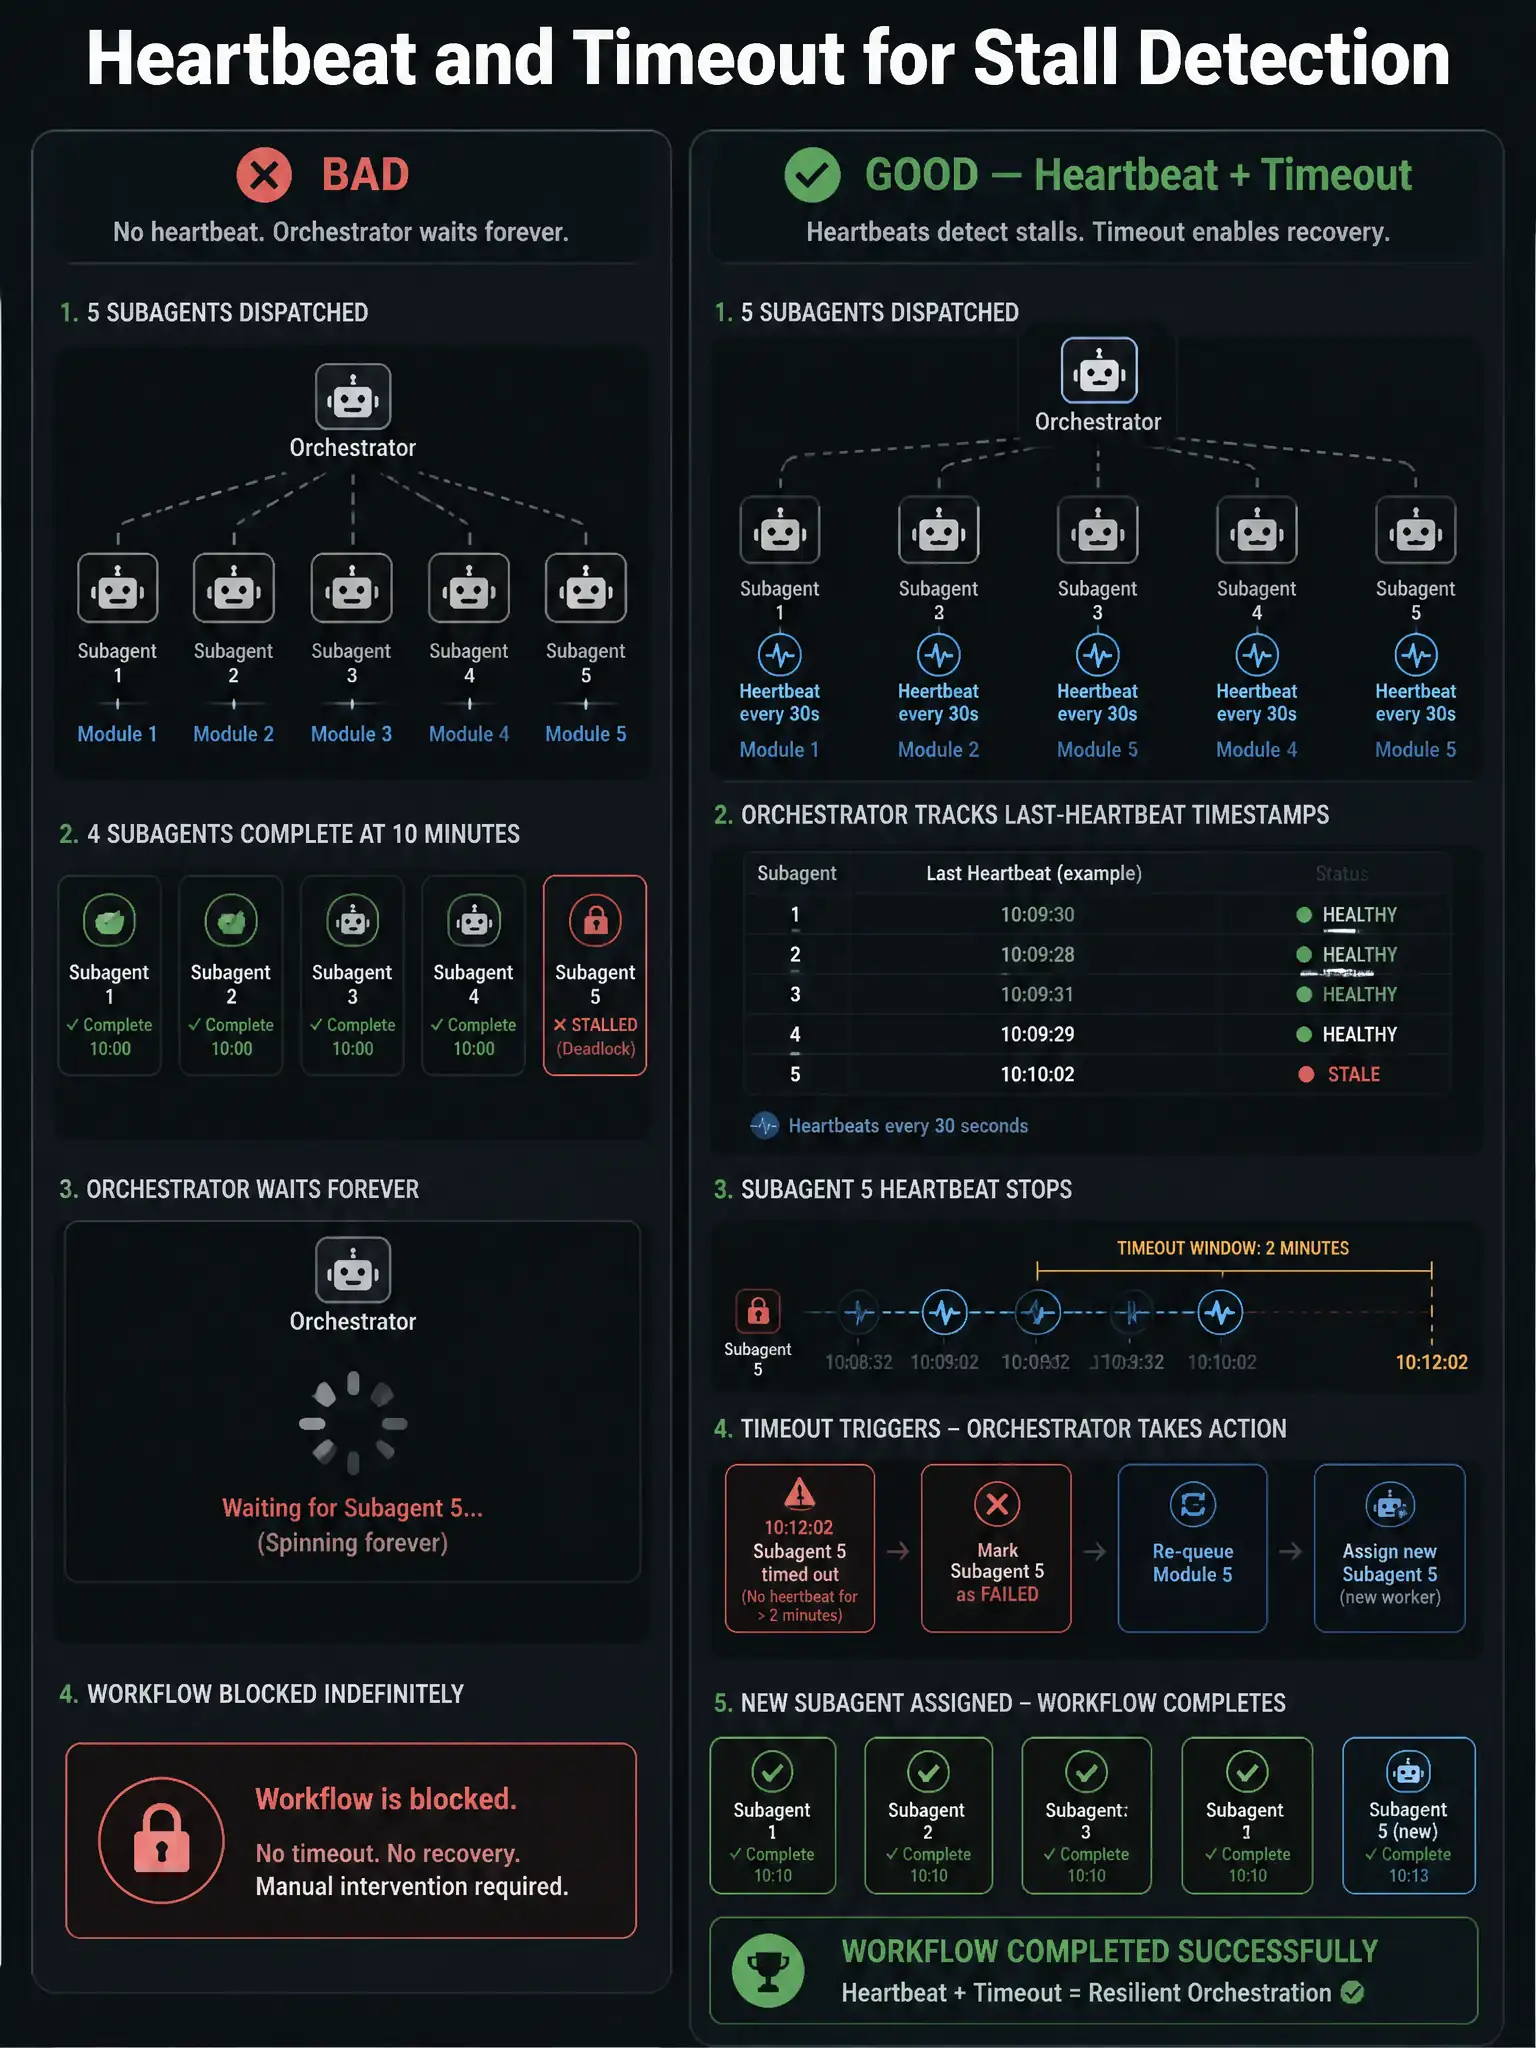
An orchestrator dispatches five subagents to process five independent modules of a codebase in parallel. Four subagents complete within 10 minutes and report results. The fifth subagent stalls due to an internal deadlock but never reports failure — it remains running indefinitely. The orchestrator waits indefinitely for the fifth result, blocking the entire workflow from completing. What mechanism was missing?
Select an answer to reveal the explanation.
Short Explanation
If a subagent goes silent, you can't just wait forever. You need heartbeats and a timeout so the orchestrator can declare it failed and kick off recovery. That keeps one stalled worker from blocking the whole workflow.
Full Explanation
The missing mechanism is a heartbeat and timeout mechanism: subagents should emit periodic heartbeat signals, and the orchestrator should declare a subagent failed and invoke recovery if no heartbeat is received within a defined window. Stall detection via heartbeat and timeout is the standard pattern for making orchestrated multi-agent workflows resilient to subagent failures that don't surface as explicit errors. Deadlocked or indefinitely-blocked processes do not raise an exception — they simply stop making progress while remaining alive. Without a detection mechanism, the orchestrator cannot distinguish a slow subagent from a stalled one. The heartbeat pattern works as follows: each subagent emits a 'still-alive' signal at regular intervals, such as every 30 seconds; the orchestrator tracks the last heartbeat timestamp for each subagent; if a subagent's heartbeat is not received within a timeout window, such as 2 minutes, the orchestrator declares it stalled; and the orchestrator invokes a recovery action, such as killing the stalled subagent, re-queuing the task, assigning it to a new subagent, or escalating to a human. This ensures that a stalled subagent causes a bounded delay, not an infinite block. The larger compute allocation idea addresses resource contention, not logical deadlocks. Deadlock caused by two processes waiting on each other's locks will not resolve with more CPU or memory. The sequential processing idea eliminates the stall-blocking problem by removing parallelism, but at the cost of all efficiency gains from parallel execution. Sacrificing throughput to avoid a resolvable coordination problem is the wrong trade-off. The different-task idea is not a generalizable solution — any subagent could deadlock, and pre-emptively avoiding specific tasks based on suspected deadlock likelihood is not feasible at scale.