
After deploying a multi-agent pipeline on GitHub Actions, you notice that Agent B consistently stalls indefinitely after Agent A completes its step. Agent B is waiting for a signal that never arrives. Logs show Agent B entered a waiting state but there are no timeout or error entries. What is the MOST LIKELY root cause of this stalled execution?
Select an answer to reveal the explanation.
Short Explanation
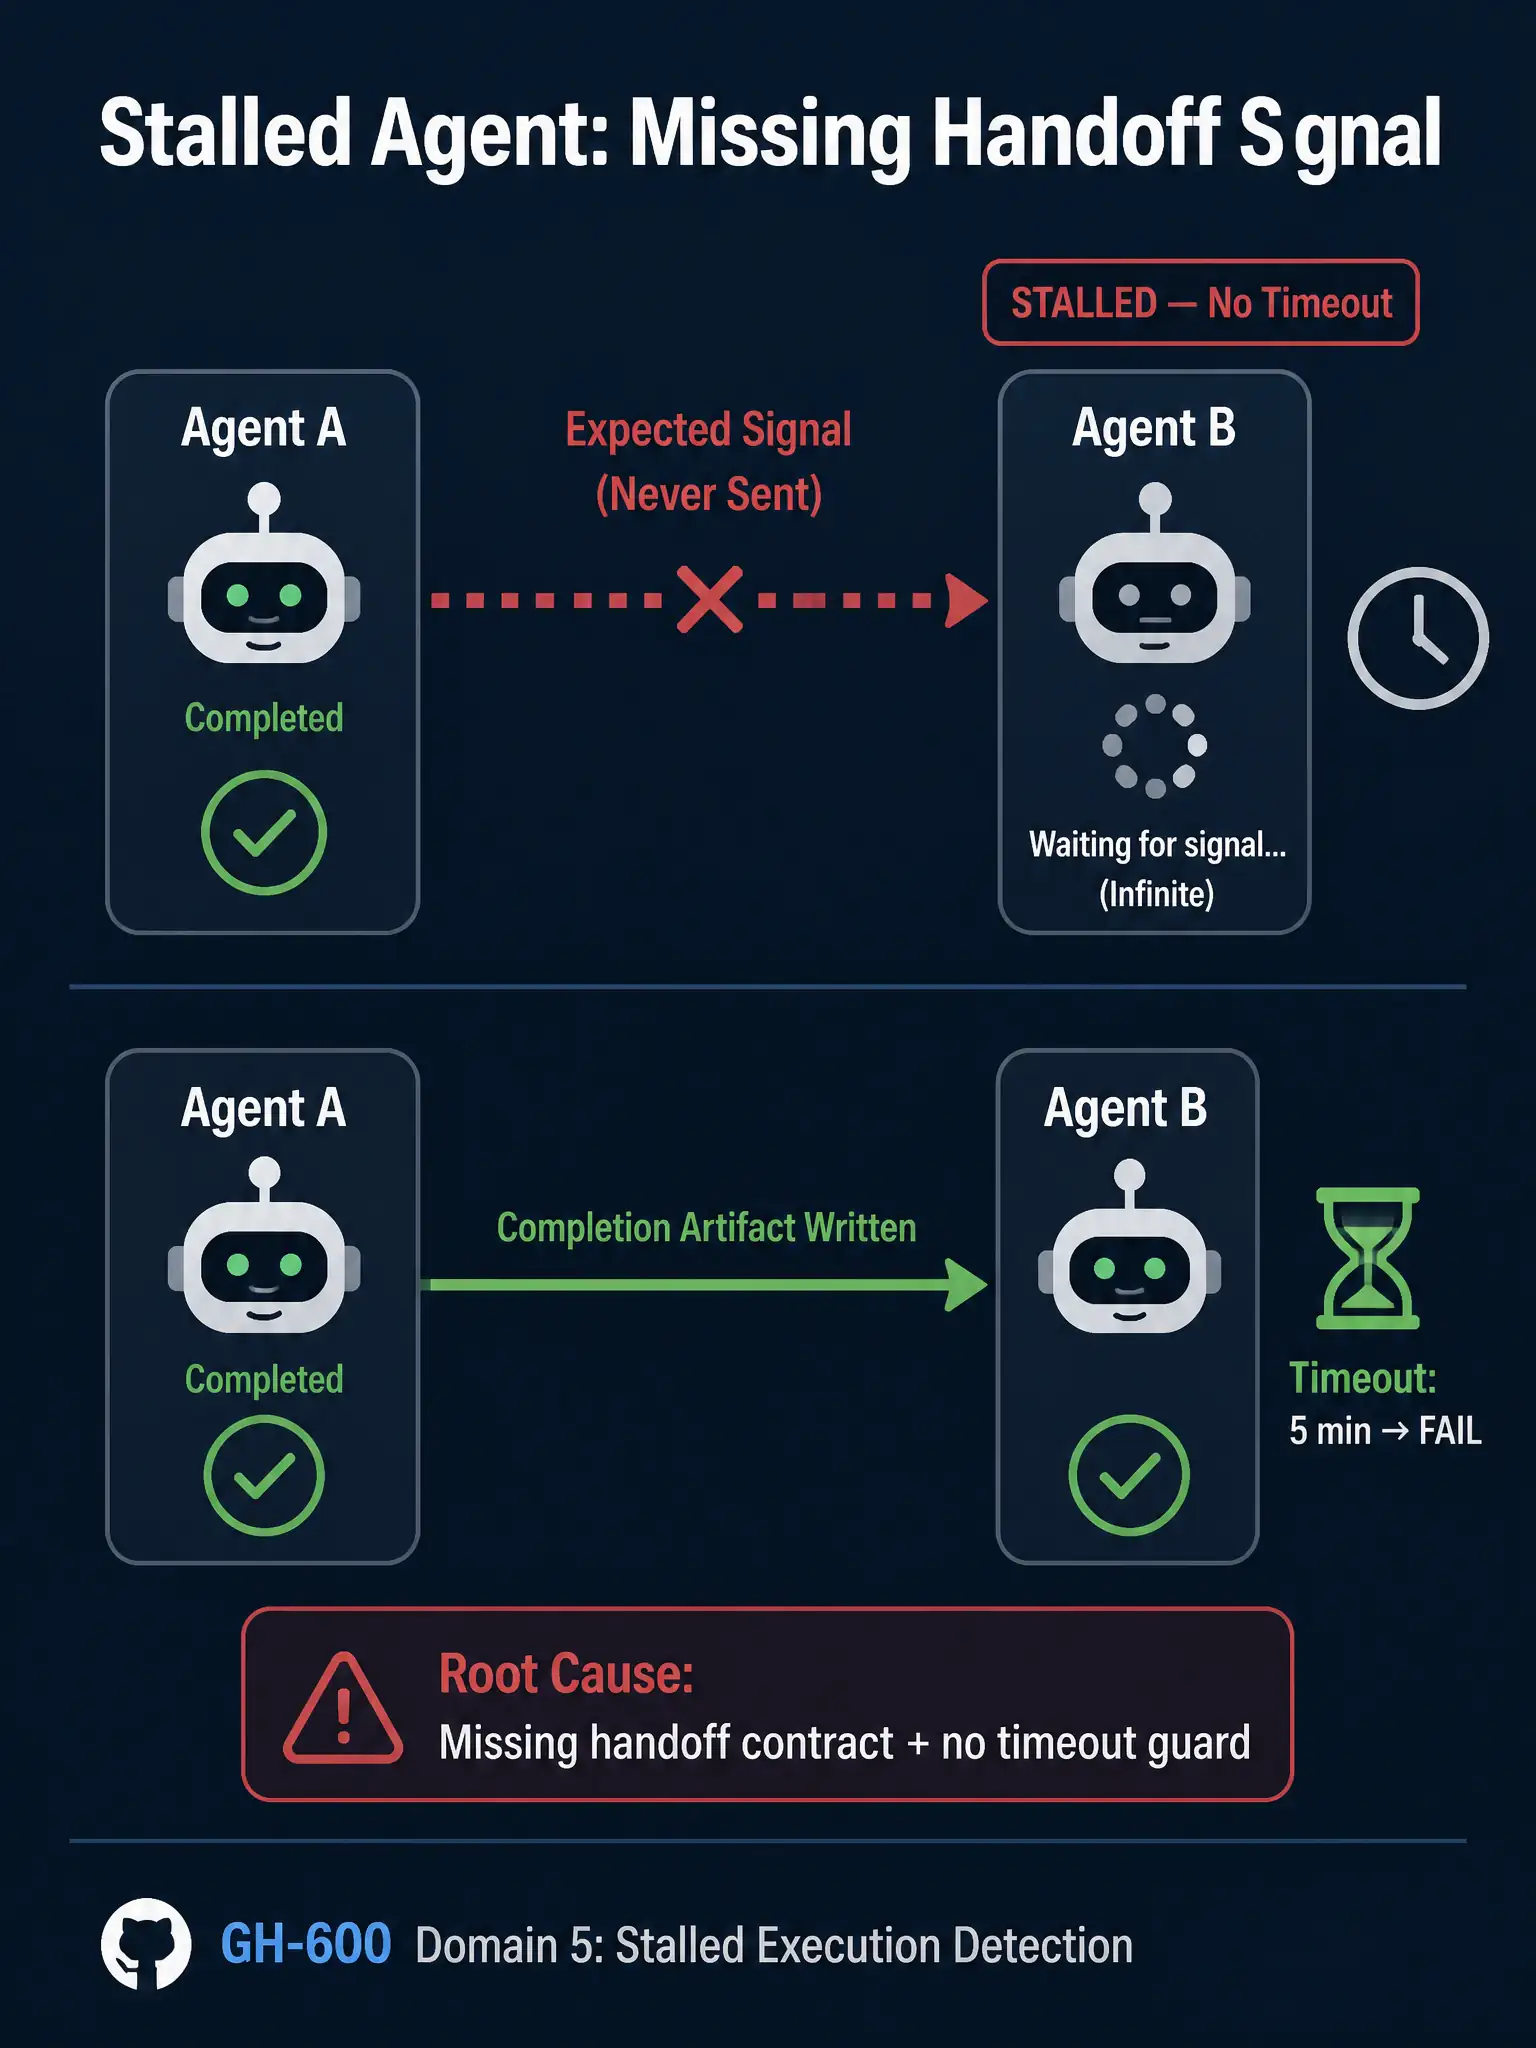
You're stuck because the upstream agent never sends the completion signal or artifact the downstream agent is polling for, and the downstream agent has no timeout guard. That leaves it waiting forever with no errors.
Full Explanation
A stalled agent with no error logs is a classic symptom of a broken handoff contract: the upstream agent finished its work but did not emit the artifact, event, or status flag that the downstream agent is waiting for. Since the downstream agent's polling loop never receives the trigger, it waits indefinitely — and because no error occurred (the wait is working as designed, just waiting for something that won't come), no error is logged.
The correct explanation is that the upstream agent completes without emitting the expected completion signal or output artifact that the downstream agent polls for, causing the downstream agent to wait indefinitely with no timeout guard. The most common causes of this pattern are: (1) the upstream agent's completion step failed silently or was short-circuited before writing the handoff artifact; (2) the artifact was written to a different path or key than the downstream agent expects; (3) the upstream agent's output schema changed and the handoff contract was not updated. The fix has two parts — correct the handoff so the upstream agent reliably emits the signal, and add a timeout with failure handling to the downstream agent's wait so it fails fast rather than stalling forever.
The insufficient-memory option is wrong because memory pressure would show up as slow execution or out-of-memory errors, not a clean waiting state with no further log output. The symptom description is inconsistent with resource exhaustion.
The runner-throttling option is wrong because runner throttling due to concurrency limits produces a queue delay before the job starts, not an indefinite wait after the job has already started and the downstream agent is actively running.
The outdated-container-image option is wrong because a container image or format parsing issue would produce an error or exception when the downstream agent attempts to read the output, not a silent indefinite wait state before any output is received.
The exam takeaway: every agent that waits for a peer must have a timeout and explicit failure handling. Missing handoff signals should fail fast, not stall silently.