
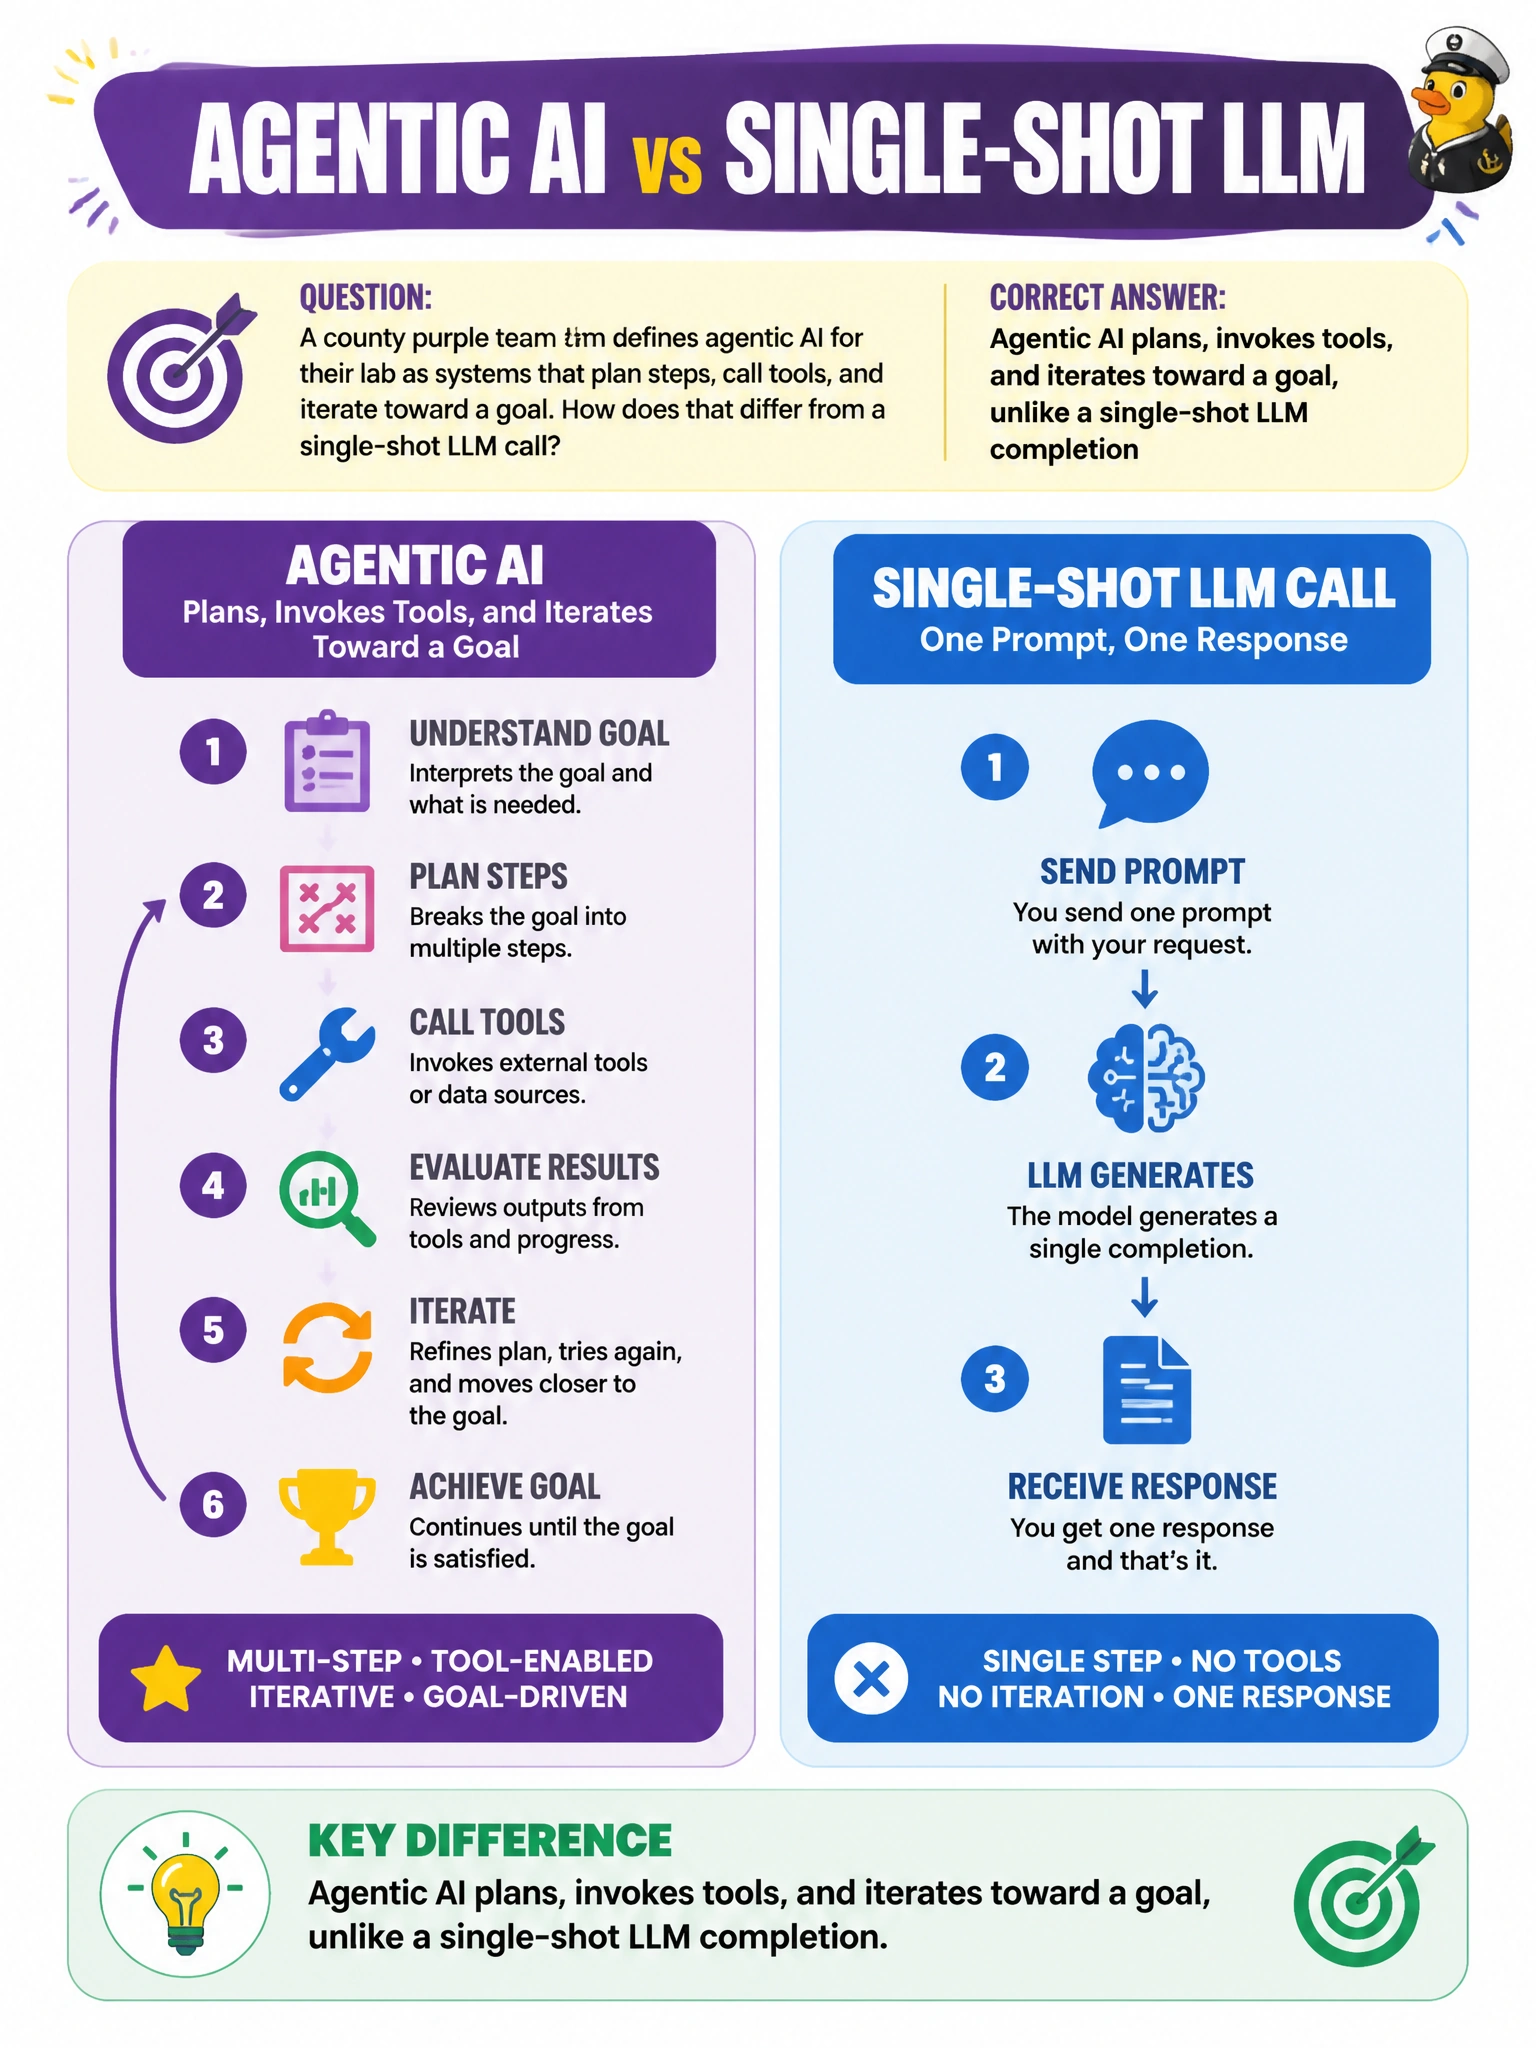
A county purple team defines agentic AI for their lab as systems that plan steps, call tools, and iterate toward a goal. How does that differ from a single-shot LLM call?
Select an answer to reveal the explanation.
Short Explanation
A single-shot LLM answer is one swing of the bat; an agent keeps planning, grabbing tools, and taking another swing until the goal is closer. Purple-team labs care about that loop—not a one-and-done chat bubble. Tools plus iteration is the tell.
Full Explanation
County purple-team labs define agentic AI as systems that plan steps, call tools, and iterate toward a goal. That definition contrasts with a single-shot LLM call, which returns one completion for one prompt without an autonomous multi-step tool-using loop. Agentic behavior is characterized by decomposition, tool/API invocation, observation of intermediate results, and continued planning until a stopping condition—exactly the loop useful in lab automation when carefully gated.
The correct contrast works because it separates architecture classes. A chat completion can still be useful for advice, but it is not the same control plane as an agent that repeatedly queries tools and updates its plan. Purple teams must know which they are authorizing.
Claiming agentic AI plans follow-ups and invokes tools to iterate memory context across chat turns fails because maintaining chat context across turns only enriches conversation; it does not plan steps, observe tool results, and iterate toward a goal distinct from single-shot assistance.
Claiming agentic AI plans queries and invokes retrieval tools and iterates citations to ground one answer fails because that workflow still produces a single grounded completion; retrieval for cited facts improves one answer but is not autonomous multi-step planning and iteration toward a goal.
Claiming agentic AI plans phrasing and invokes sampling tools while iterating temperature to diversify wording fails because temperature and top-p only diversify wording of completions; tuning sampling is not invoking tools to observe results and iterate toward a goal, so it remains single-shot completion behavior, not agentic automation.
Exam caveat: GASAE items often test “agentic = plan + tools + iterate” versus single-shot completion. Do not equate them.
Operational check: In the lab architecture diagram, identify whether the system can call tools, observe results, and loop; if it cannot, label it single-shot assistive LLM use—not agentic automation—and apply controls accordingly.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.