
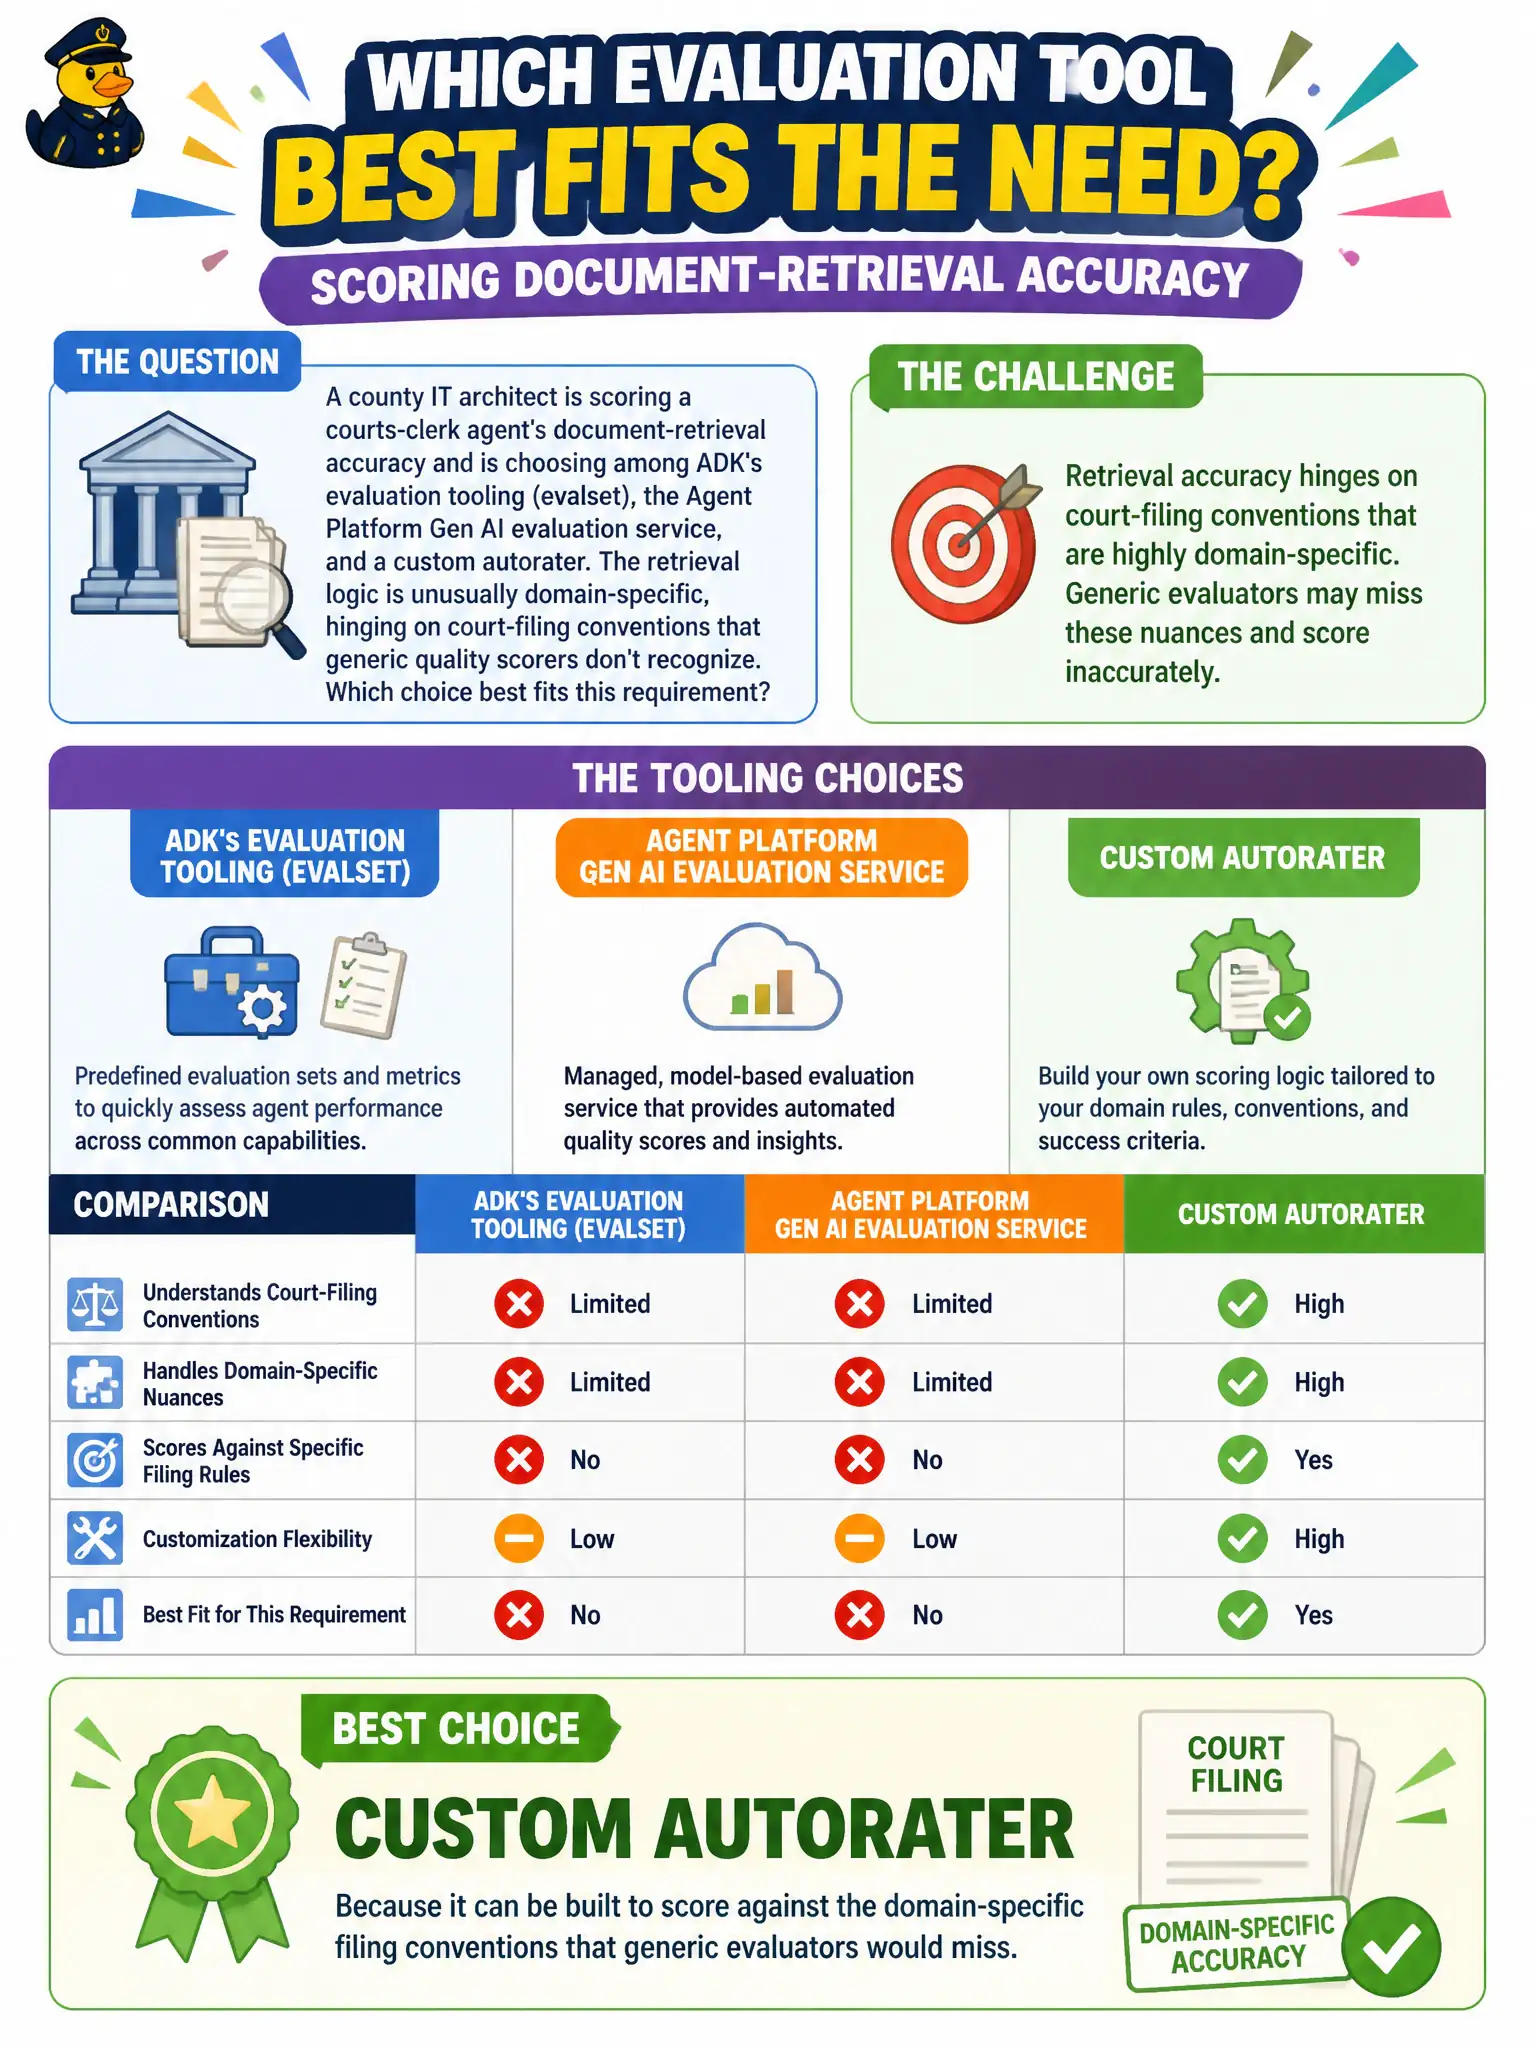
A county IT architect is scoring a courts-clerk agent's document-retrieval accuracy and is choosing among ADK's evaluation tooling (evalset), the Agent Platform Gen AI evaluation service, and a custom autorater. The retrieval logic is unusually domain-specific, hinging on court-filing conventions that generic quality scorers don't recognize. Which choice best fits this requirement?
Select an answer to reveal the explanation.
Short Explanation
A generic evaluator is like a substitute teacher grading an essay on a subject they've never studied — they can spot bad grammar but not a wrong legal citation. A custom autorater is the subject-matter expert you build once so it actually knows what a correct court filing looks like.
Full Explanation
A custom autorater is purpose-built to encode domain-specific correctness criteria — here, the court-filing conventions that determine whether a retrieved document is actually the right one — which a general-purpose scorer has no way to represent because it evaluates relevance or fluency in the abstract, not against a specialized rule set. That makes it the right tool when the evaluation need is narrow and domain-bound rather than general-purpose. A managed evaluation service is attractive for reducing setup effort, but low configuration overhead doesn't help if the service's built-in criteria can't express filing-convention correctness in the first place — convenience doesn't substitute for domain fit. Picking ADK's evalset tooling because it is newer conflates recency with suitability; evaluation tool choice should follow from what needs to be measured, not from release date. Reusing whatever tool already handles logging optimizes for toolchain familiarity at the expense of measurement validity, which is the actual goal of an evaluation framework decision. Scope caveat: a custom autorater still needs its own validation against human-labeled examples, or it just encodes the team's assumptions rather than ground truth. Operational check: run the autorater against a small hand-labeled sample of filings and confirm its scores agree with the human labels before trusting it at scale.