
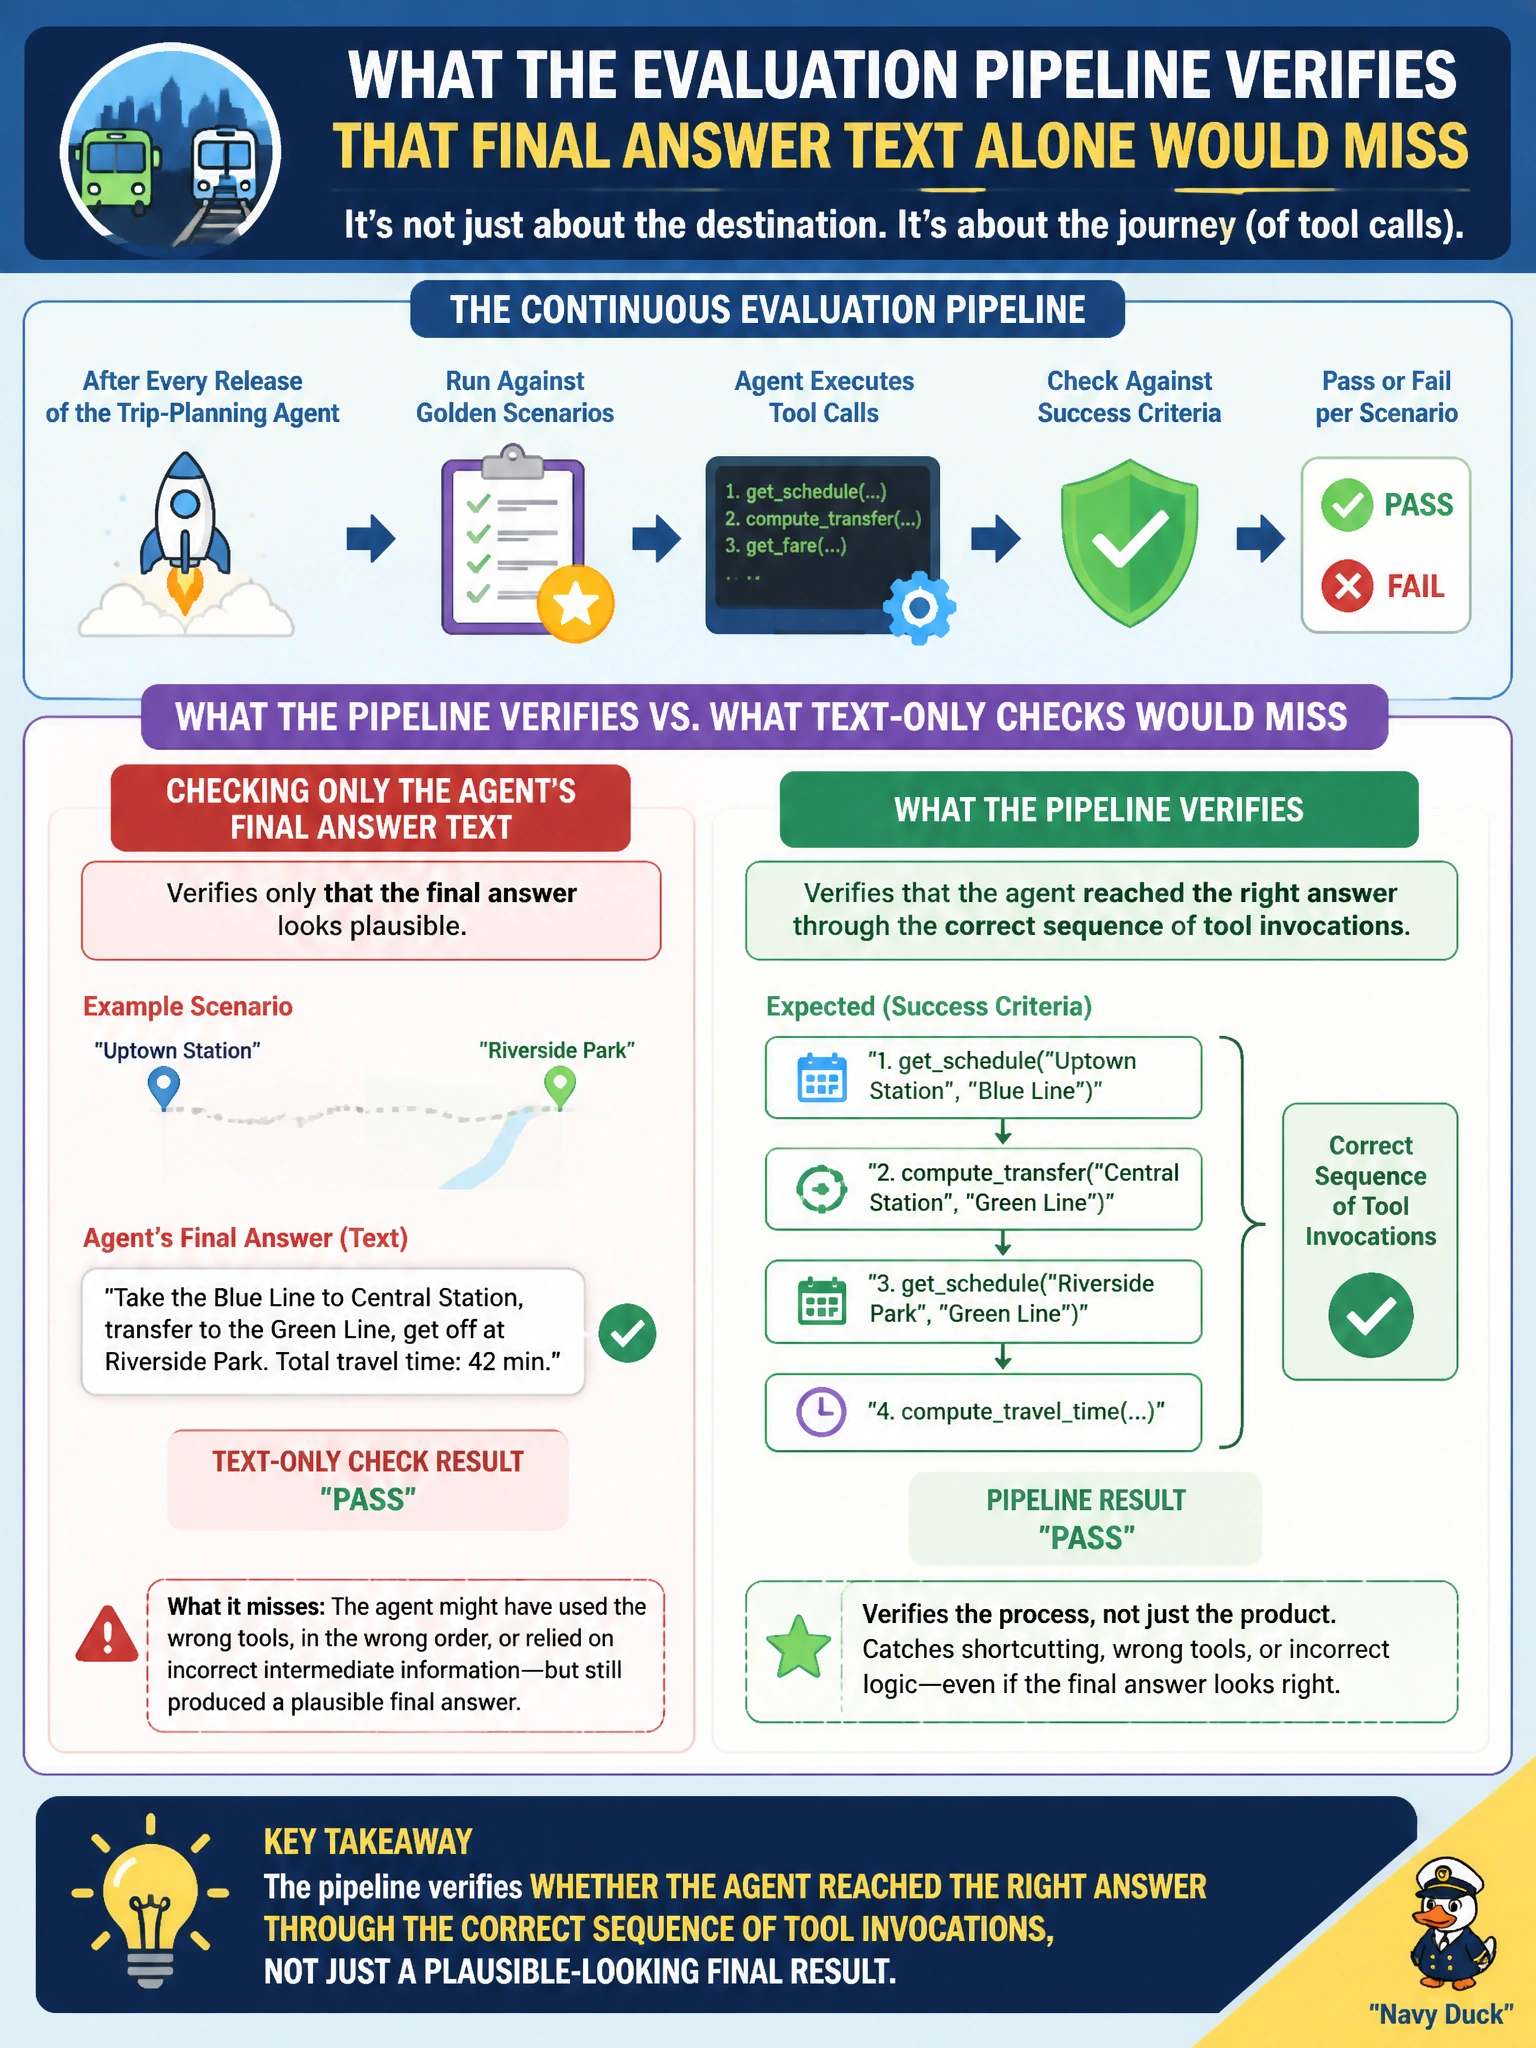
A transit authority runs a continuous evaluation pipeline after every release of its trip-planning agent. For each golden scenario, the pipeline checks whether the agent's tool calls, such as fetching the schedule and computing a transfer, match the success criteria defined for that scenario. What is this pipeline verifying that a check of only the agent's final answer text would miss?
Select an answer to reveal the explanation.
Short Explanation
Grading only the final answer is like accepting a student's answer to a word problem without checking their work — sometimes the number happens to be right for the wrong reason. Checking the tool calls themselves is checking the work: did the agent actually fetch the schedule and compute the transfer, or did it just guess something that sounded plausible?
Full Explanation
Tool-execution evaluation inspects the trajectory an agent takes to reach an answer — which tools it invoked, with what arguments, and in what order — and compares that trajectory against success criteria defined per golden scenario, catching cases where a correct-looking final answer was produced through a wrong or missing tool call, such as skipping the transfer computation and hallucinating a plausible number instead. A final-answer-only check has no visibility into that path, so it would pass a response that got lucky and miss a systematic tool-invocation bug that only shows up under different inputs. Response-time comparison measures performance, not correctness of execution, and can be identical whether or not the right tools ran. Exact-template phrasing checks presentation, not whether the underlying computation was sound, and agents legitimately vary their wording turn to turn. Detecting a model version change is a deployment-metadata concern, unrelated to whether tool calls matched success criteria. Scope caveat: trajectory checks require success criteria to specify the expected tools and arguments per scenario up front, or the pipeline has nothing concrete to compare against. Operational check: pull the tool-call trace for one golden scenario and confirm it lists the schedule fetch and transfer computation in the order the success criteria expect.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.