
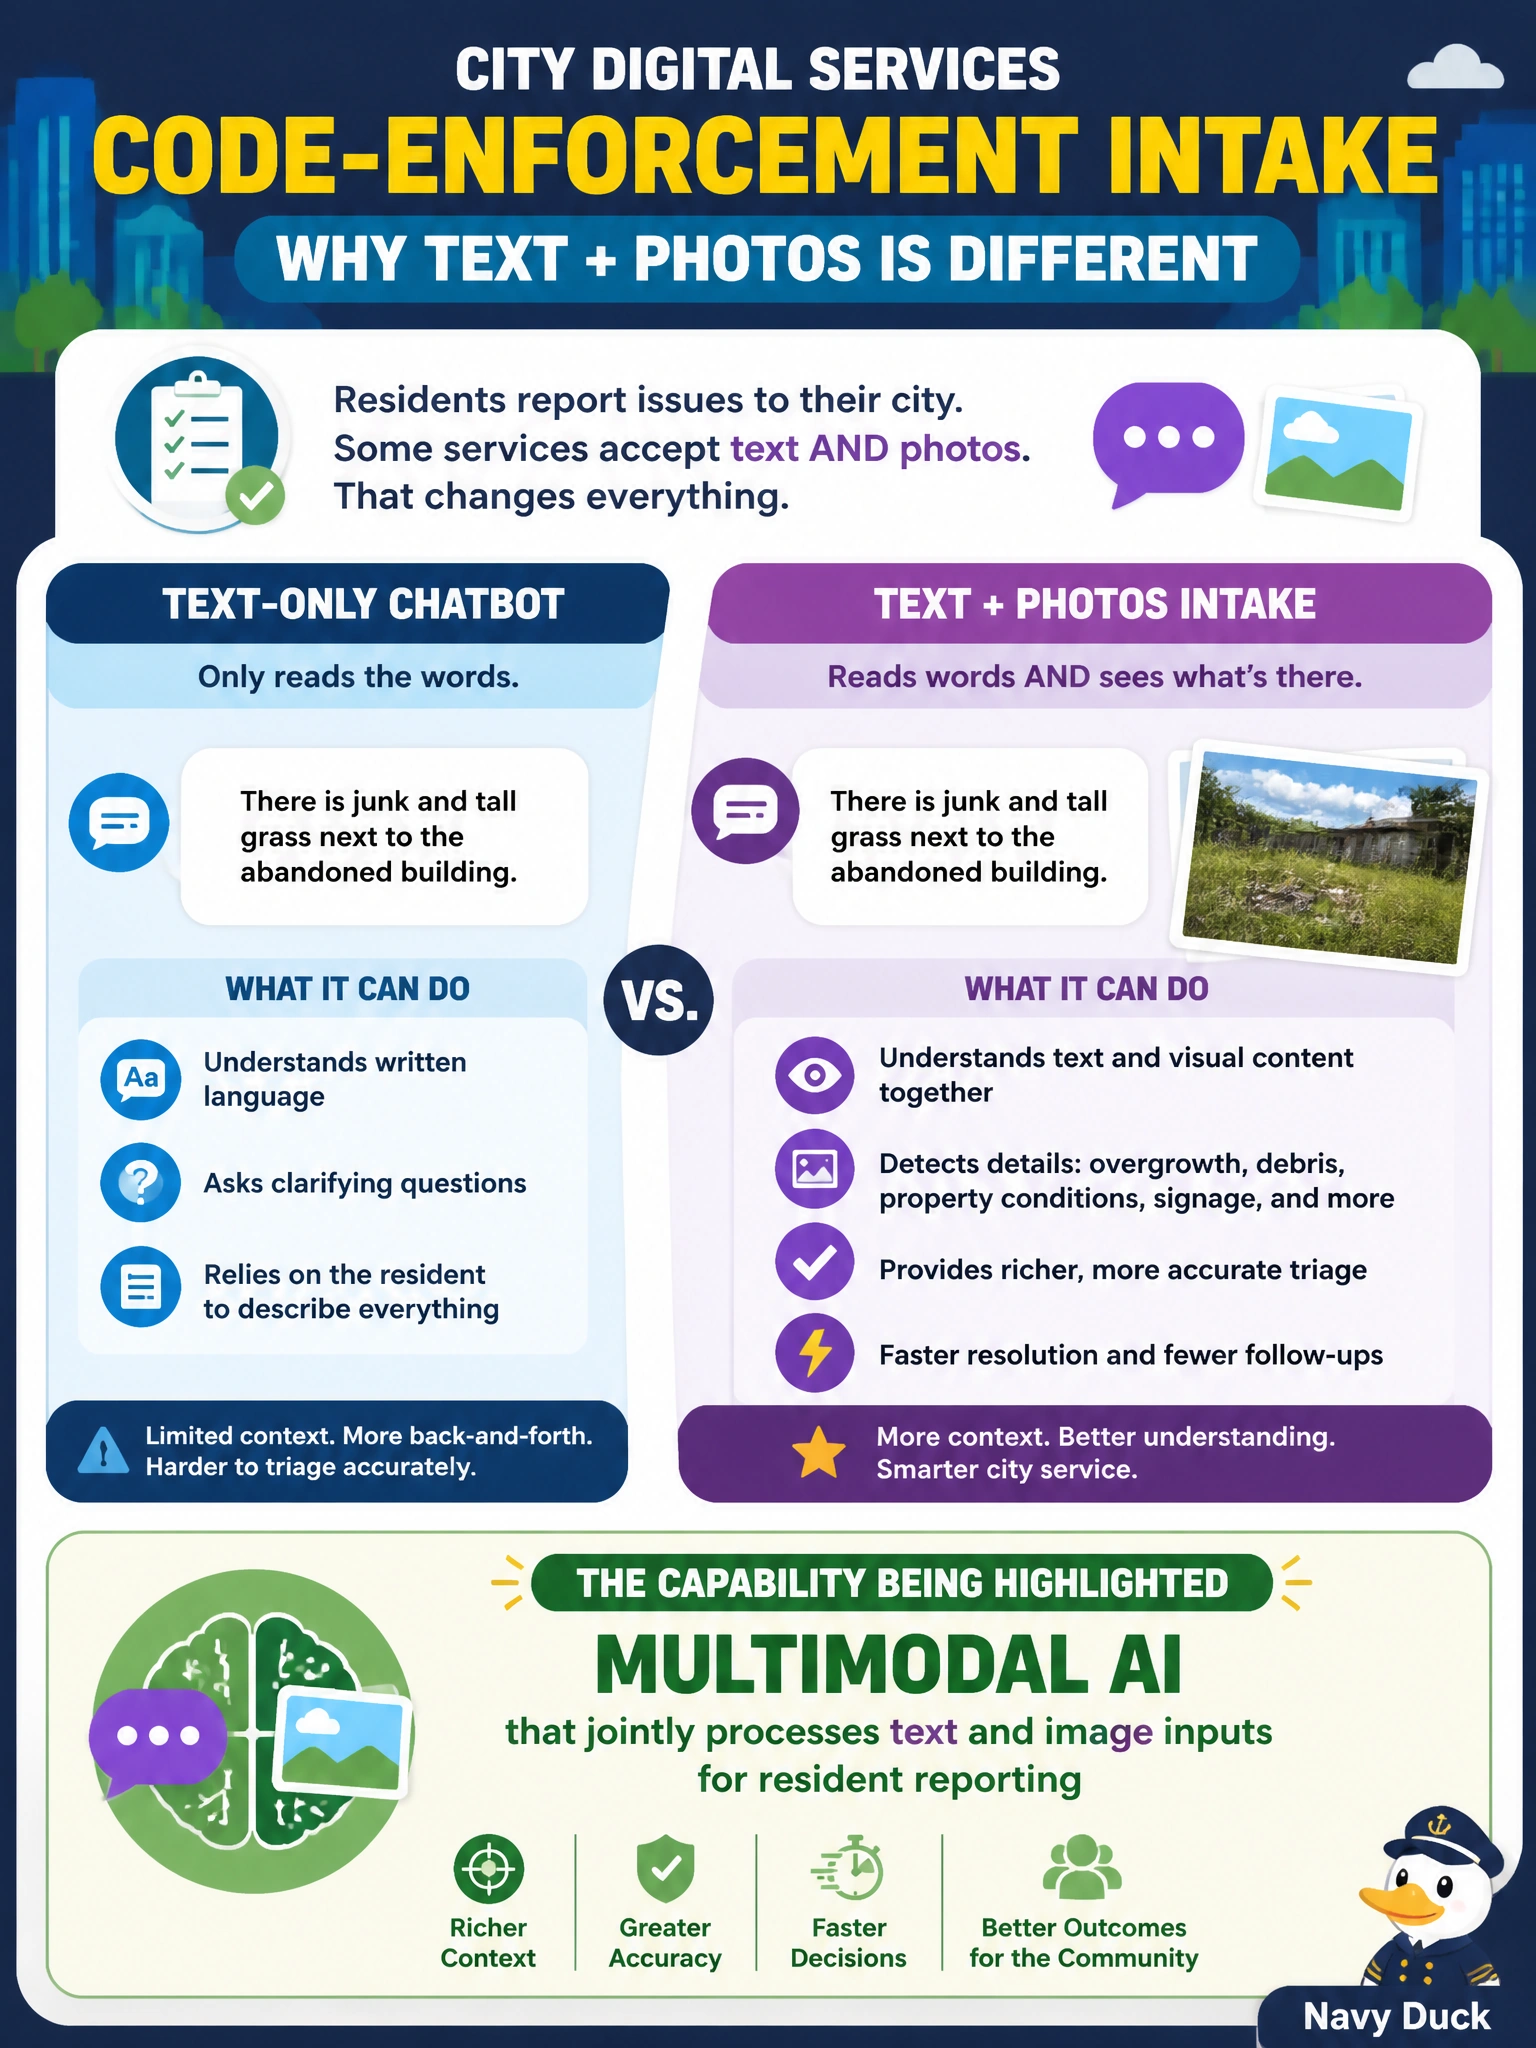
City digital services explains why a code-enforcement intake that accepts text plus photos differs from a text-only chatbot. What capability is being highlighted?
Select an answer to reveal the explanation.
Short Explanation
A text-only bot reads the complaint letter; a multimodal intake can read the letter and look at the photo of the broken porch. That extra sense—text plus image—is the multimodal capability digital services should name.
Full Explanation
City digital services explaining why a code-enforcement intake that accepts text plus photos differs from a text-only chatbot is highlighting multimodal AI that jointly processes text and image inputs for resident reporting. Multimodality is the capability to use more than one data type in the same decision or understanding pipeline.
Why the other options fail by concept: Calling text-only chatbots multimodal by definition empties the term of meaning. Claiming photos cannot be used in any municipal AI workflow is false and would block common inspection and 311 patterns. Asserting multimodal systems require abandoning all text channels confuses “supports images” with “text forbidden.”
Exam caveat: Multimodal systems raise combined privacy and retention issues (complaint narrative plus dwelling imagery) and need evaluation on both text and image failure modes. Accessibility and channel choice still matter—residents may use text-only paths even when multimodal intake exists.
Operational check: Document the intake as multimodal in the AI inventory, specify how text and images are stored and joined, set retention and access rules for photos, and test routing accuracy on text-only, image-only, and combined cases before widening code-enforcement use.