
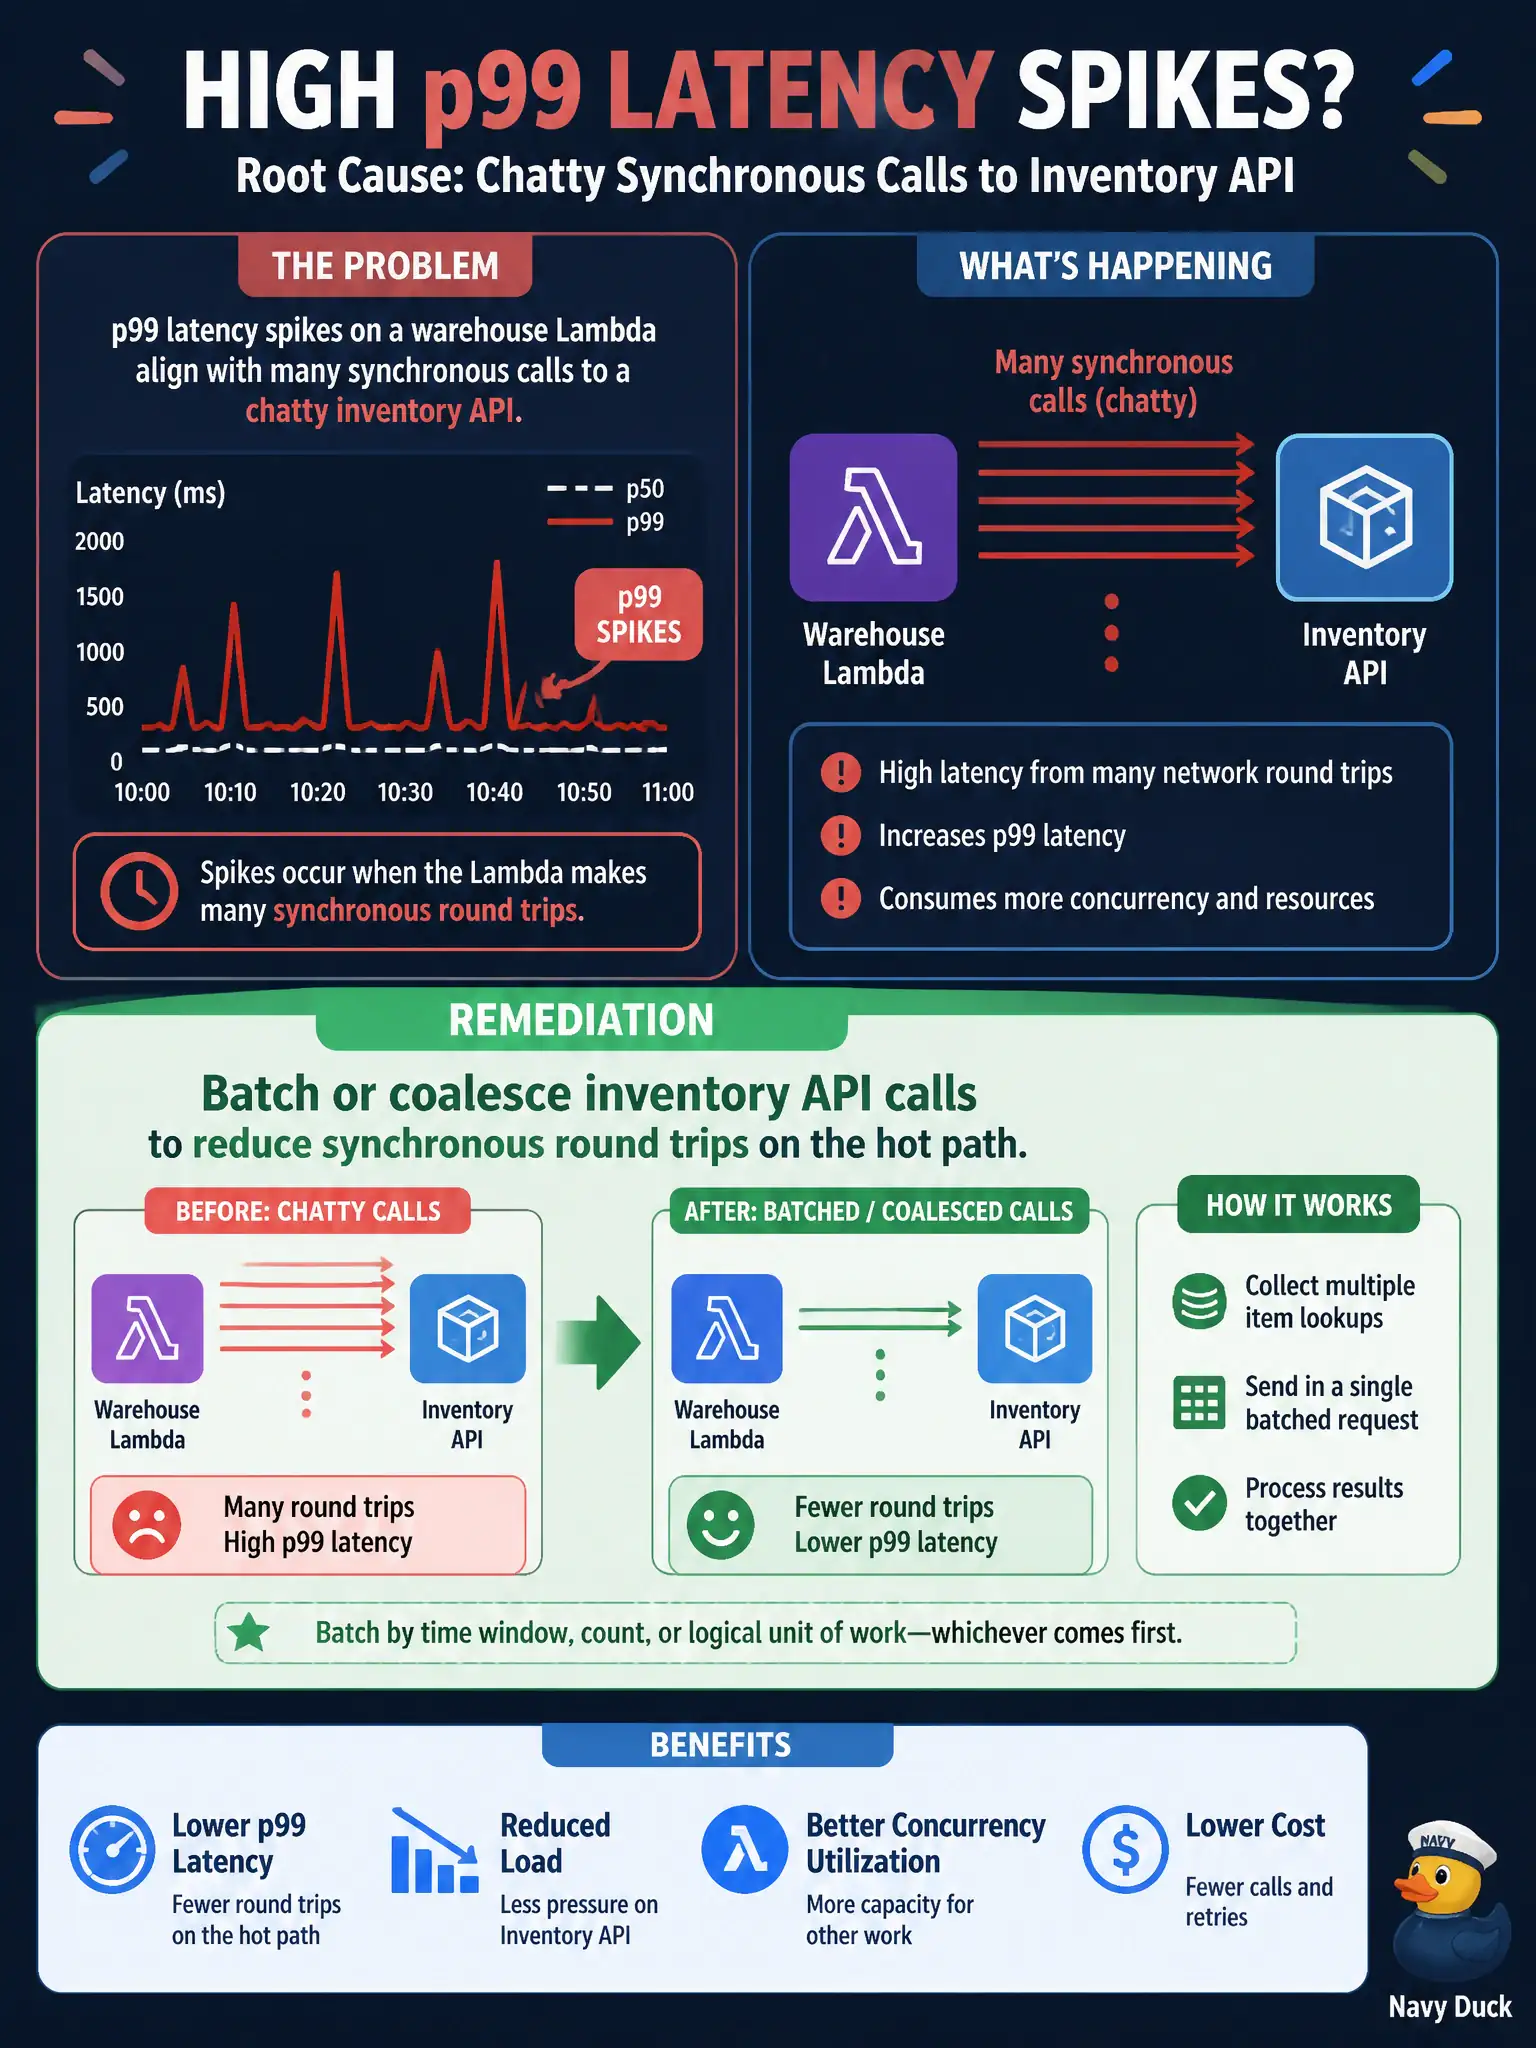
p99 latency spikes on a warehouse Lambda align with many synchronous calls to a chatty inventory API. What remediation should the developer propose?
Select an answer to reveal the explanation.
Short Explanation
A dozen tiny inventory chats per request is death by a thousand round trips. Bundle what you can into fewer calls—or batch—so p99 stops spike-dancing. Logging louder won't shrink the network hops.
Full Explanation
When p99 latency spikes on a warehouse Lambda align with many synchronous calls to a chatty inventory API, the developer should batch or coalesce inventory API calls to reduce synchronous round trips on the hot path. Chatty remote calls dominate tail latency; fewer round trips usually help more than adding logs or sampling. Municipal warehouse lookups for stock checks should minimize sequential chatter.
Adding more verbose DEBUG logs only increases work without changing the chatty call pattern.
Increasing X-Ray sampling to 100% while leaving chatty calls unchanged raises observability cost without fixing latency.
Removing timeouts so each chatty call can run indefinitely worsens tail latency and resource holds.
Exam caveat: Reduce remote round trips via batching/coalescing when traces show chatty synchronous dependencies.
Operational check: Refactor to batch inventory lookups, compare p99 before/after under load, keep sensible timeouts, and verify warehouse citizen/staff workflows still see correct stock data. Keep the civic/municipal context in mind: warehouse kiosks amplify chatty APIs into visible queues at loading docks. Document the finding in the municipal incident ticket so the next on-call engineer inherits evidence rather than folklore.