
For the safety-review summarizer, a data engineer is choosing between chunking each incident narrative as one large chunk per report (regardless of length) versus splitting long reports into multiple smaller, paragraph-based chunks. A two-page injury investigation report is the case in question. Which approach better supports precise retrieval for a query about one specific detail buried in that report, such as 'what corrective action was recommended'?
Select an answer to reveal the explanation.
Short Explanation
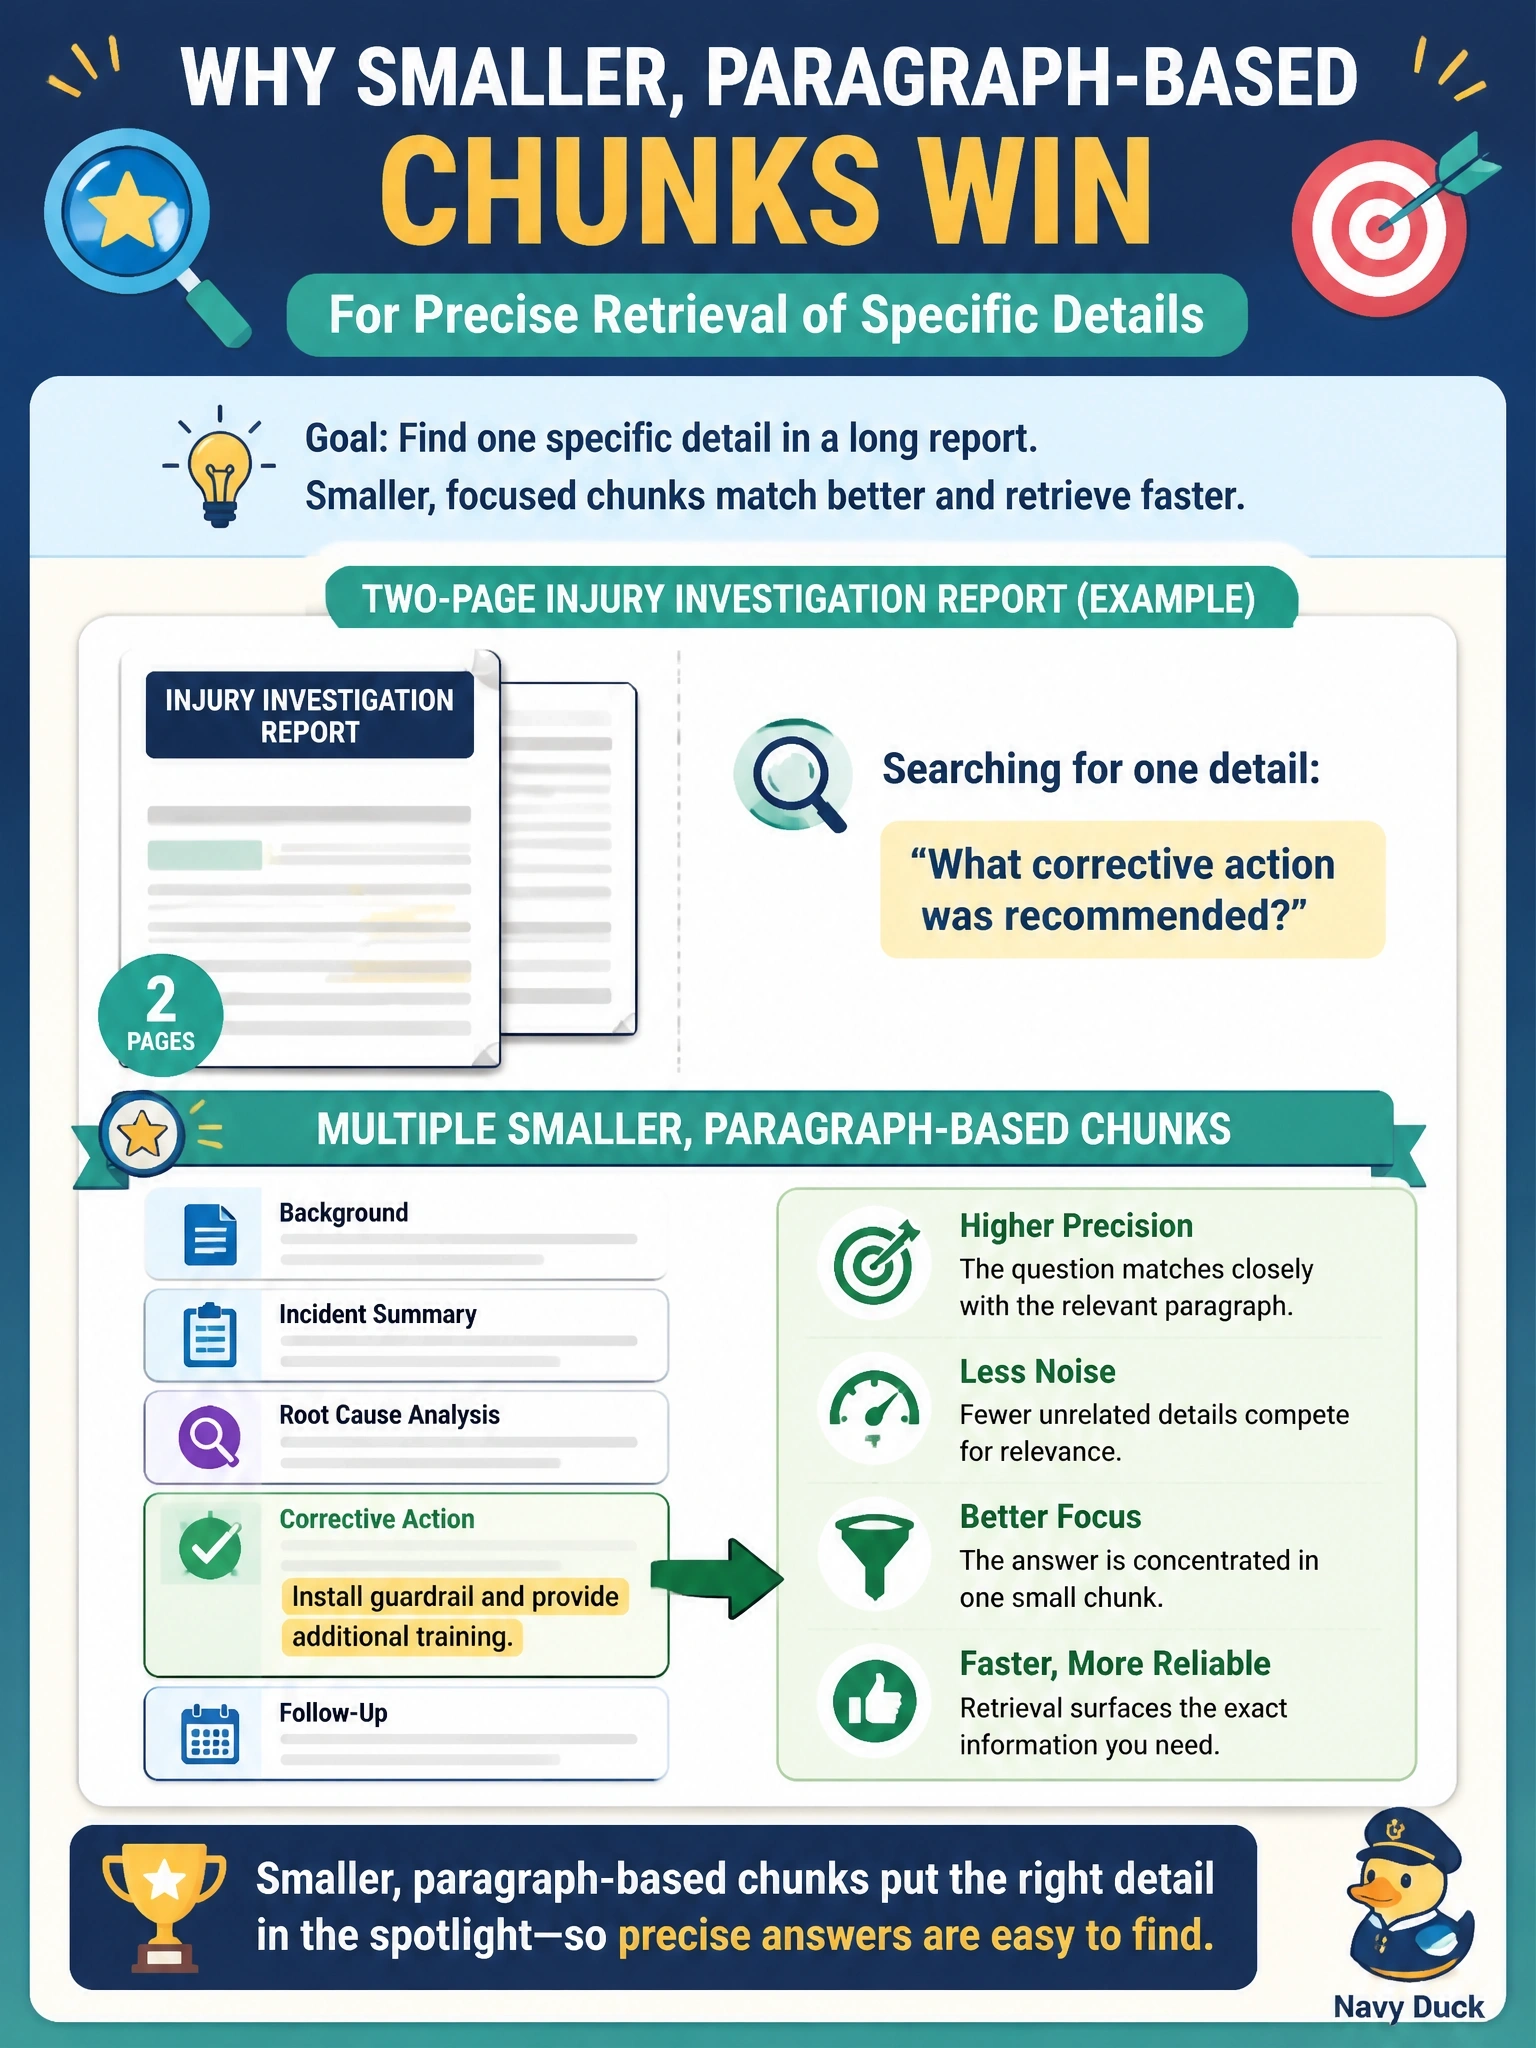
Ask a narrow question like 'what corrective action was recommended' and a big chunk covering the whole two-page report has to somehow rank as relevant on average across everything it contains - a smaller chunk that's just the corrective-action paragraph doesn't have that problem, it's already focused on exactly what was asked.
Full Explanation
Multiple smaller, paragraph-based chunks are correct because a query about one specific, narrow detail is better served by a chunk whose embedding is focused on that detail, rather than by a large chunk whose embedding represents an average of the entire two-page report's content - the larger chunk dilutes the semantic signal for any one sub-topic, echoing the general size-versus-precision trade-off established elsewhere in this domain. One large chunk per report is wrong for the specific query pattern described - while it does guarantee the full report's text is technically present somewhere in the index, having the text present does not mean the chunk's embedding will rank highly for a narrow query, since the query's meaning must compete against everything else in that same oversized chunk for relevance scoring; the recommended corrective action becomes just one part of a much less targeted vector. Claiming both approaches produce identical retrieval precision is wrong and denies the well-established relationship between chunk size and retrieval precision that this domain repeatedly tests - chunk granularity has a real, measurable effect on how well a narrow query matches the right passage. Claiming the safety-review summarizer does not use retrieval is wrong given the intake's framing, which describes it as a summarizer over incident narratives that, like the other Meridian applications, is built on Databricks retrieval and GenAI tooling - retrieval quality is directly relevant to how well it can locate and cite specific details. The exam-relevant point closes this domain's chunking theme: smaller, focused chunks generally serve precise, detail-level queries better than large, undifferentiated ones.