
Safety incident narratives at Meridian's terminal are free-text reports of varying length, from a two-sentence near-miss note to a two-page injury investigation, and they contain crew members' names and other PII. Which chunking approach is most appropriate for this source?
Select an answer to reveal the explanation.
Short Explanation
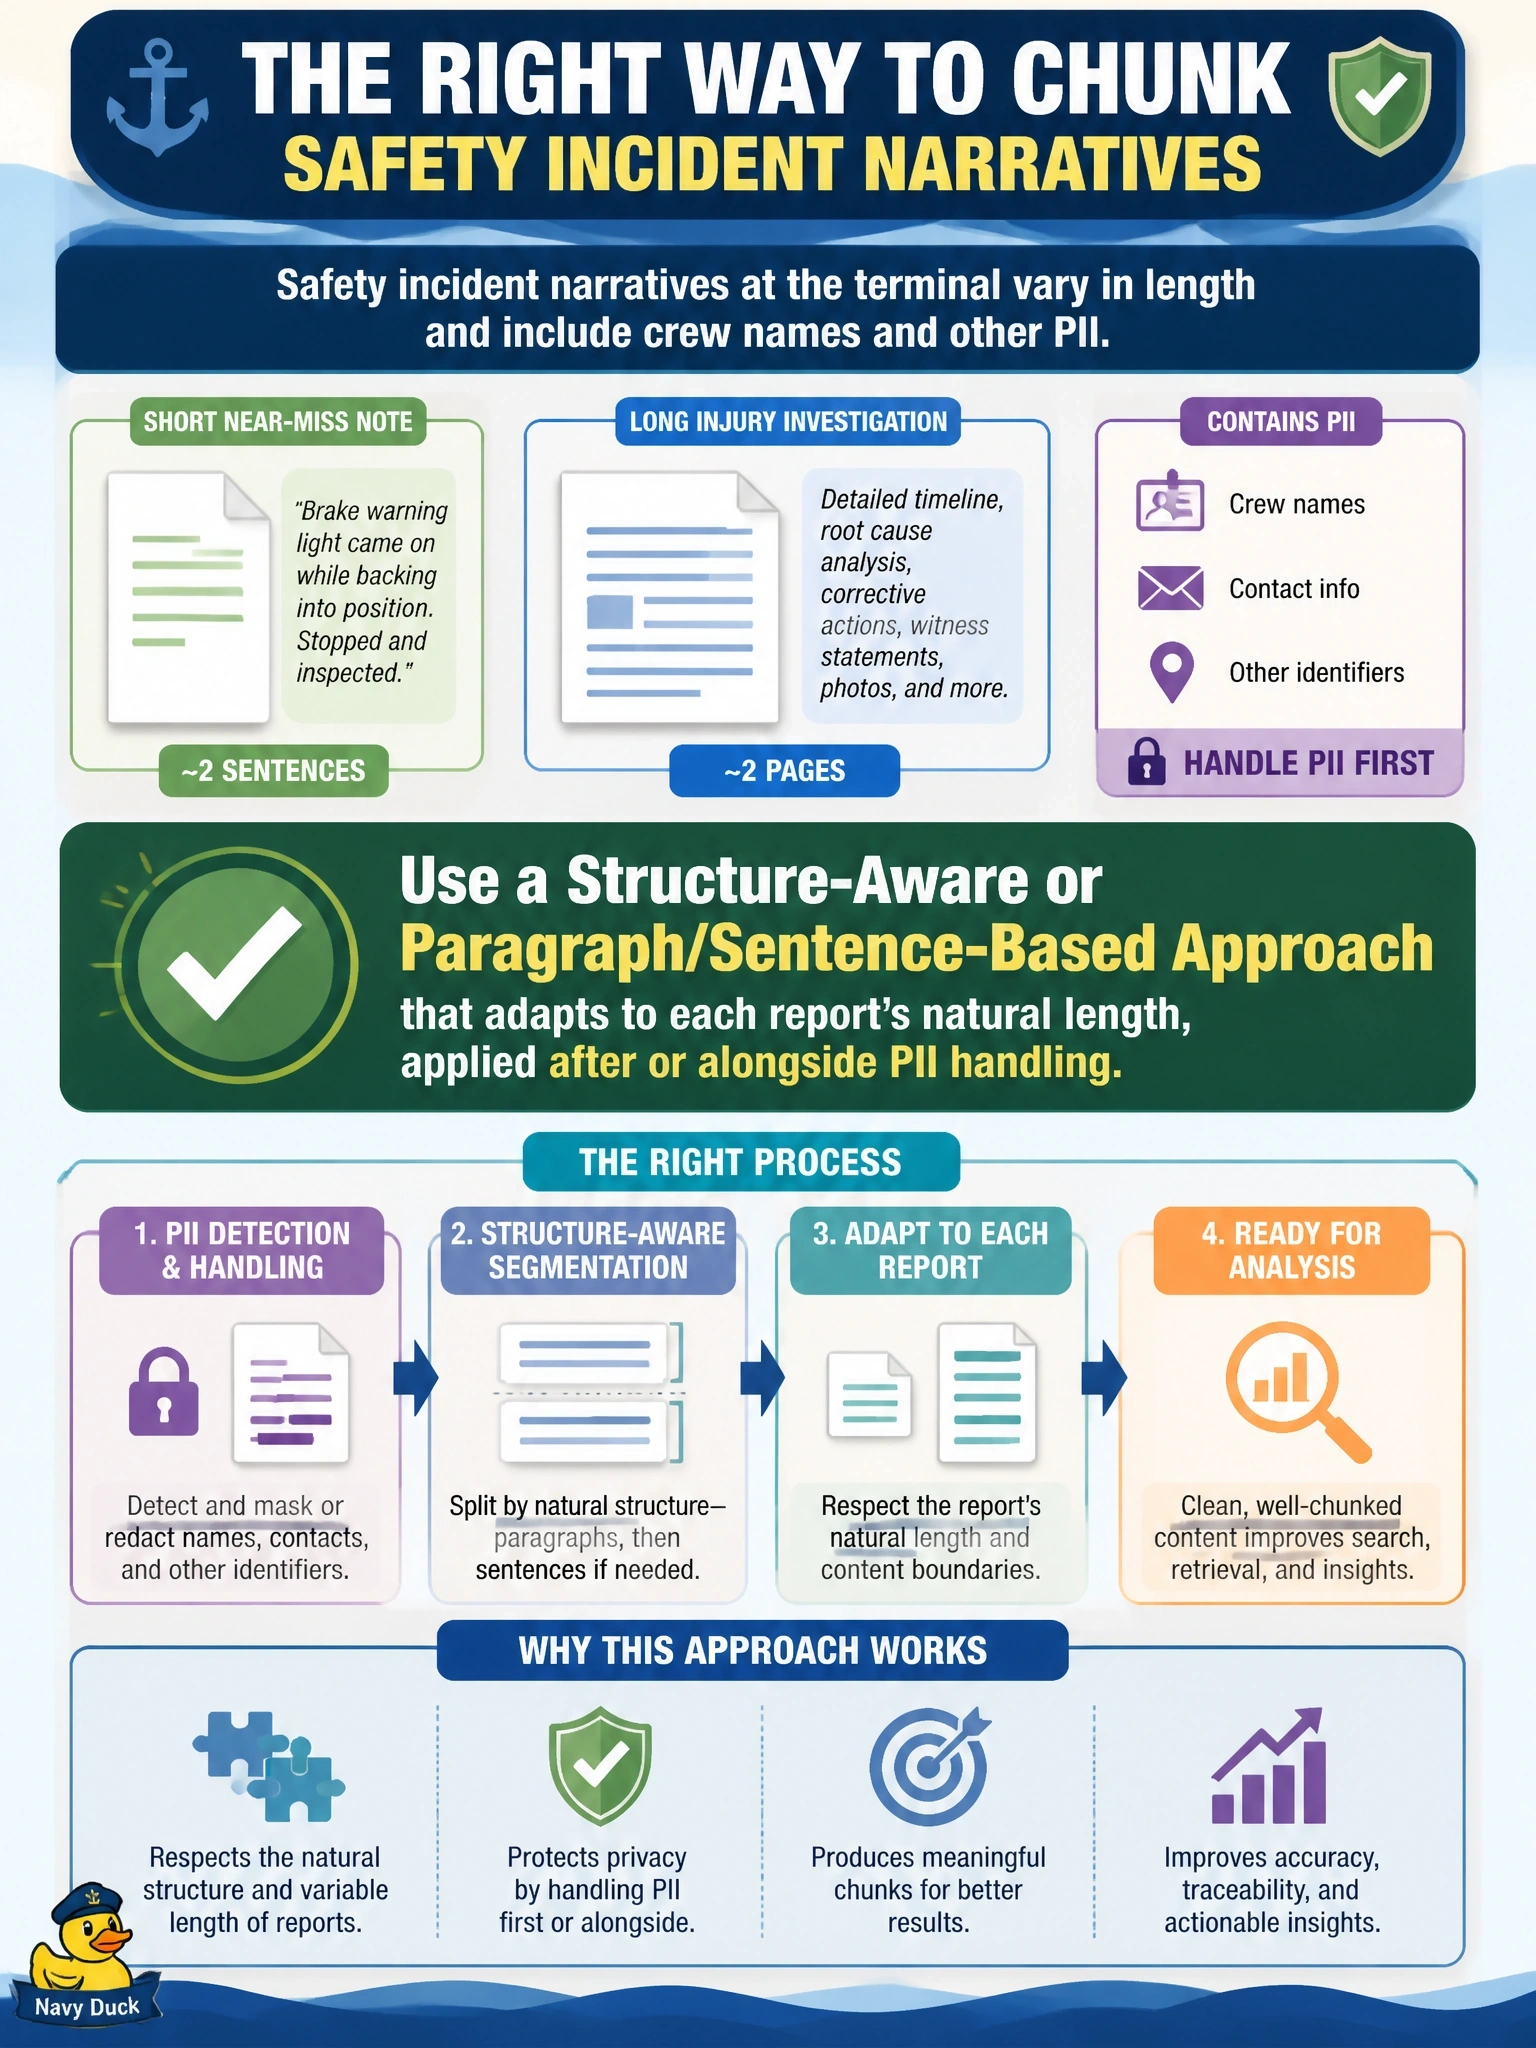
A two-sentence near-miss note and a two-page injury report shouldn't be forced through the same fixed-size cookie cutter - let the chunking adapt to each report's natural length and paragraph structure, and handle the PII question as its own governance step rather than skipping indexing altogether.
Full Explanation
A structure-aware or paragraph/sentence-based approach that adapts to each report's natural length is correct because this source varies enormously in length, from a two-sentence note to a two-page investigation, and a chunking strategy that respects natural paragraph or sentence boundaries will produce coherent, appropriately sized chunks for both a short note and a long report, rather than forcing every report through one uniform size. A single fixed, uniformly large chunk size is wrong because it under-utilizes a two-sentence note as a chunk (padding it with nothing while still paying per-chunk overhead) and may still truncate or awkwardly split a two-page report, failing both ends of the length distribution described in the scenario. Skipping chunking and indexing entirely because the content is sensitive is wrong because PII sensitivity is a governance and masking concern - addressed through data-masking and access-control techniques - not a reason to abandon indexing a corpus the safety-review summarizer application explicitly needs; the correct response to sensitive content is to protect it appropriately, not to withhold it from the pipeline. Chunking by container number is wrong because container number is a metadata field useful for filtering, not a chunking unit - grouping narrative text by an unrelated identifier field has no relationship to where the report's own meaning naturally breaks. The exam-relevant point is matching chunk boundaries to the natural structure of variable-length free text while treating PII handling as a separate, parallel governance concern.