
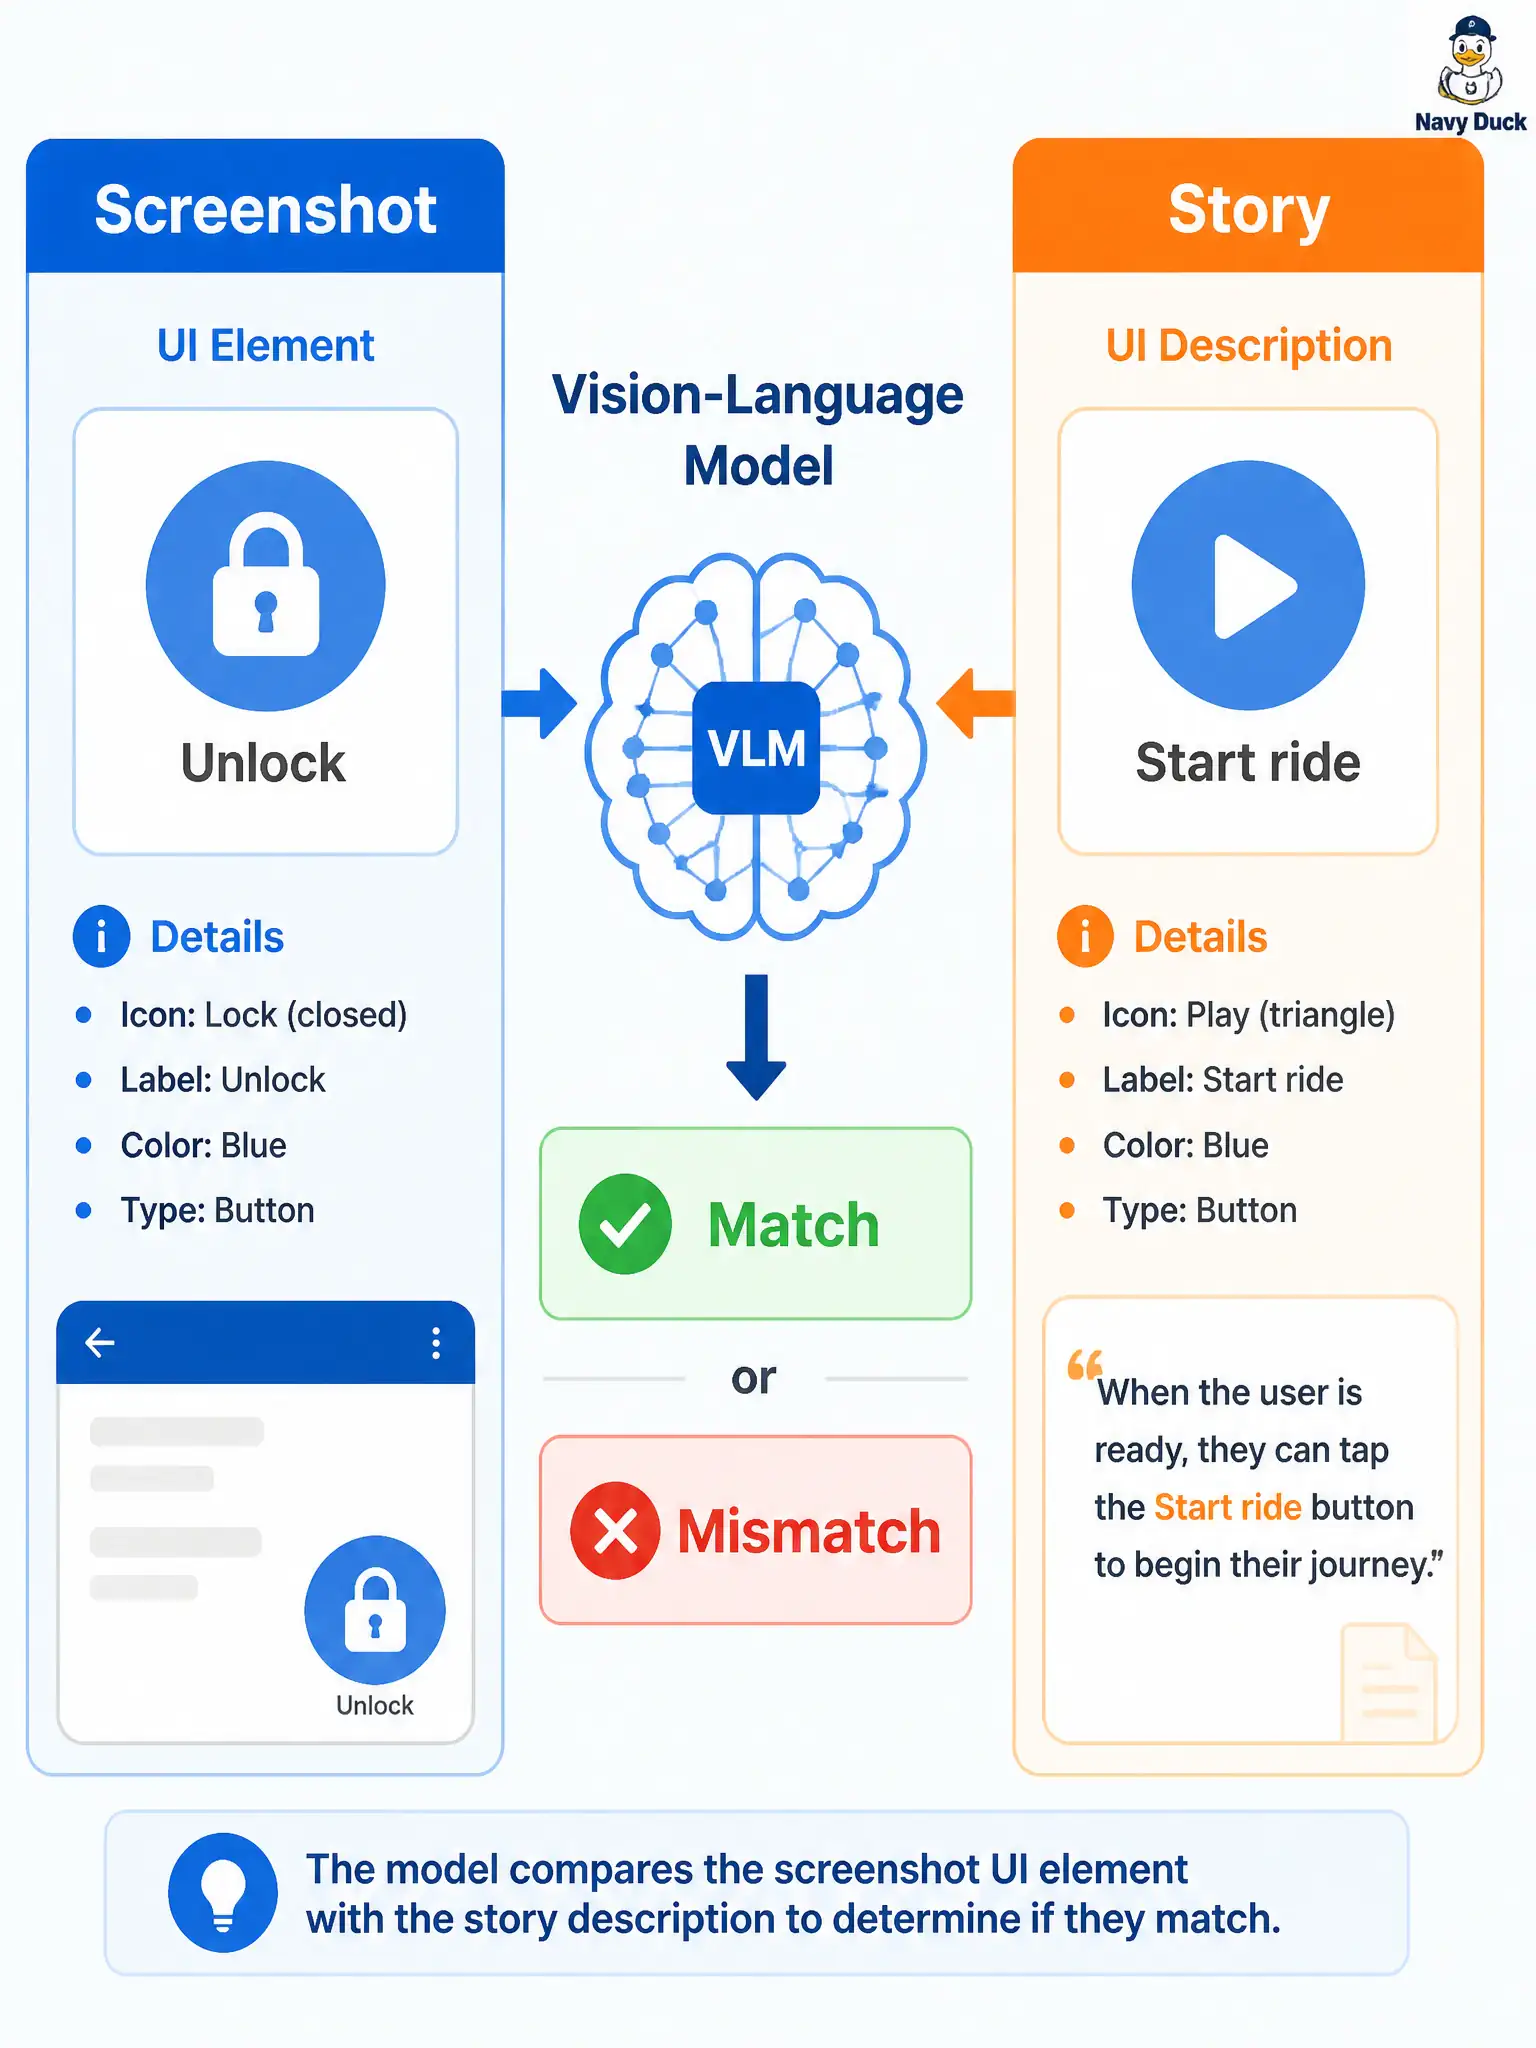
A bike-share screen shows the button label “Unlock” while the user story says the primary action is “Start ride.” How should a tester best use a vision-language (multimodal) model here?
Select an answer to reveal the explanation.
Short Explanation
Vision-language models shine when you feed them both the picture and the words so they can spot “Unlock” versus “Start ride.” Captioning the image alone skips the comparison that matters for testing. Use the join of visual and textual input as draft support, then review.
Full Explanation
Vision-language (multimodal) models jointly process visual and textual inputs, so the best testing use here is to compare the bike-share screenshot showing “Unlock” with the user story that says the primary action is “Start ride,” flagging the label mismatch for cases. Civic mobility UIs often drift from story verbs; joint input makes that drift reviewable draft evidence.
Describing the PNG in isolation with no story attached, then inventing expected results from memory, skips the comparison that makes the mismatch a requirements issue. Ignoring the image and asking a text-only model to rewrite the story into neuron-coverage metrics abandons multimodal comparison and imports model-as-SUT goals. Treating model output as an automated pass/fail of the production bike-share API overclaims: multimodal help is reviewable support, not an unattended production oracle.
Exam caveat: VLM value for testers is joint UI-versus-basis comparison. Caption-only or API-oracle fantasies miss the syllabus use.
Operational check: feed screenshot plus story; require the reply to list label mismatches; confirm “Unlock” versus “Start ride” appears; open a defect or case only after human confirmation against the civic build.