
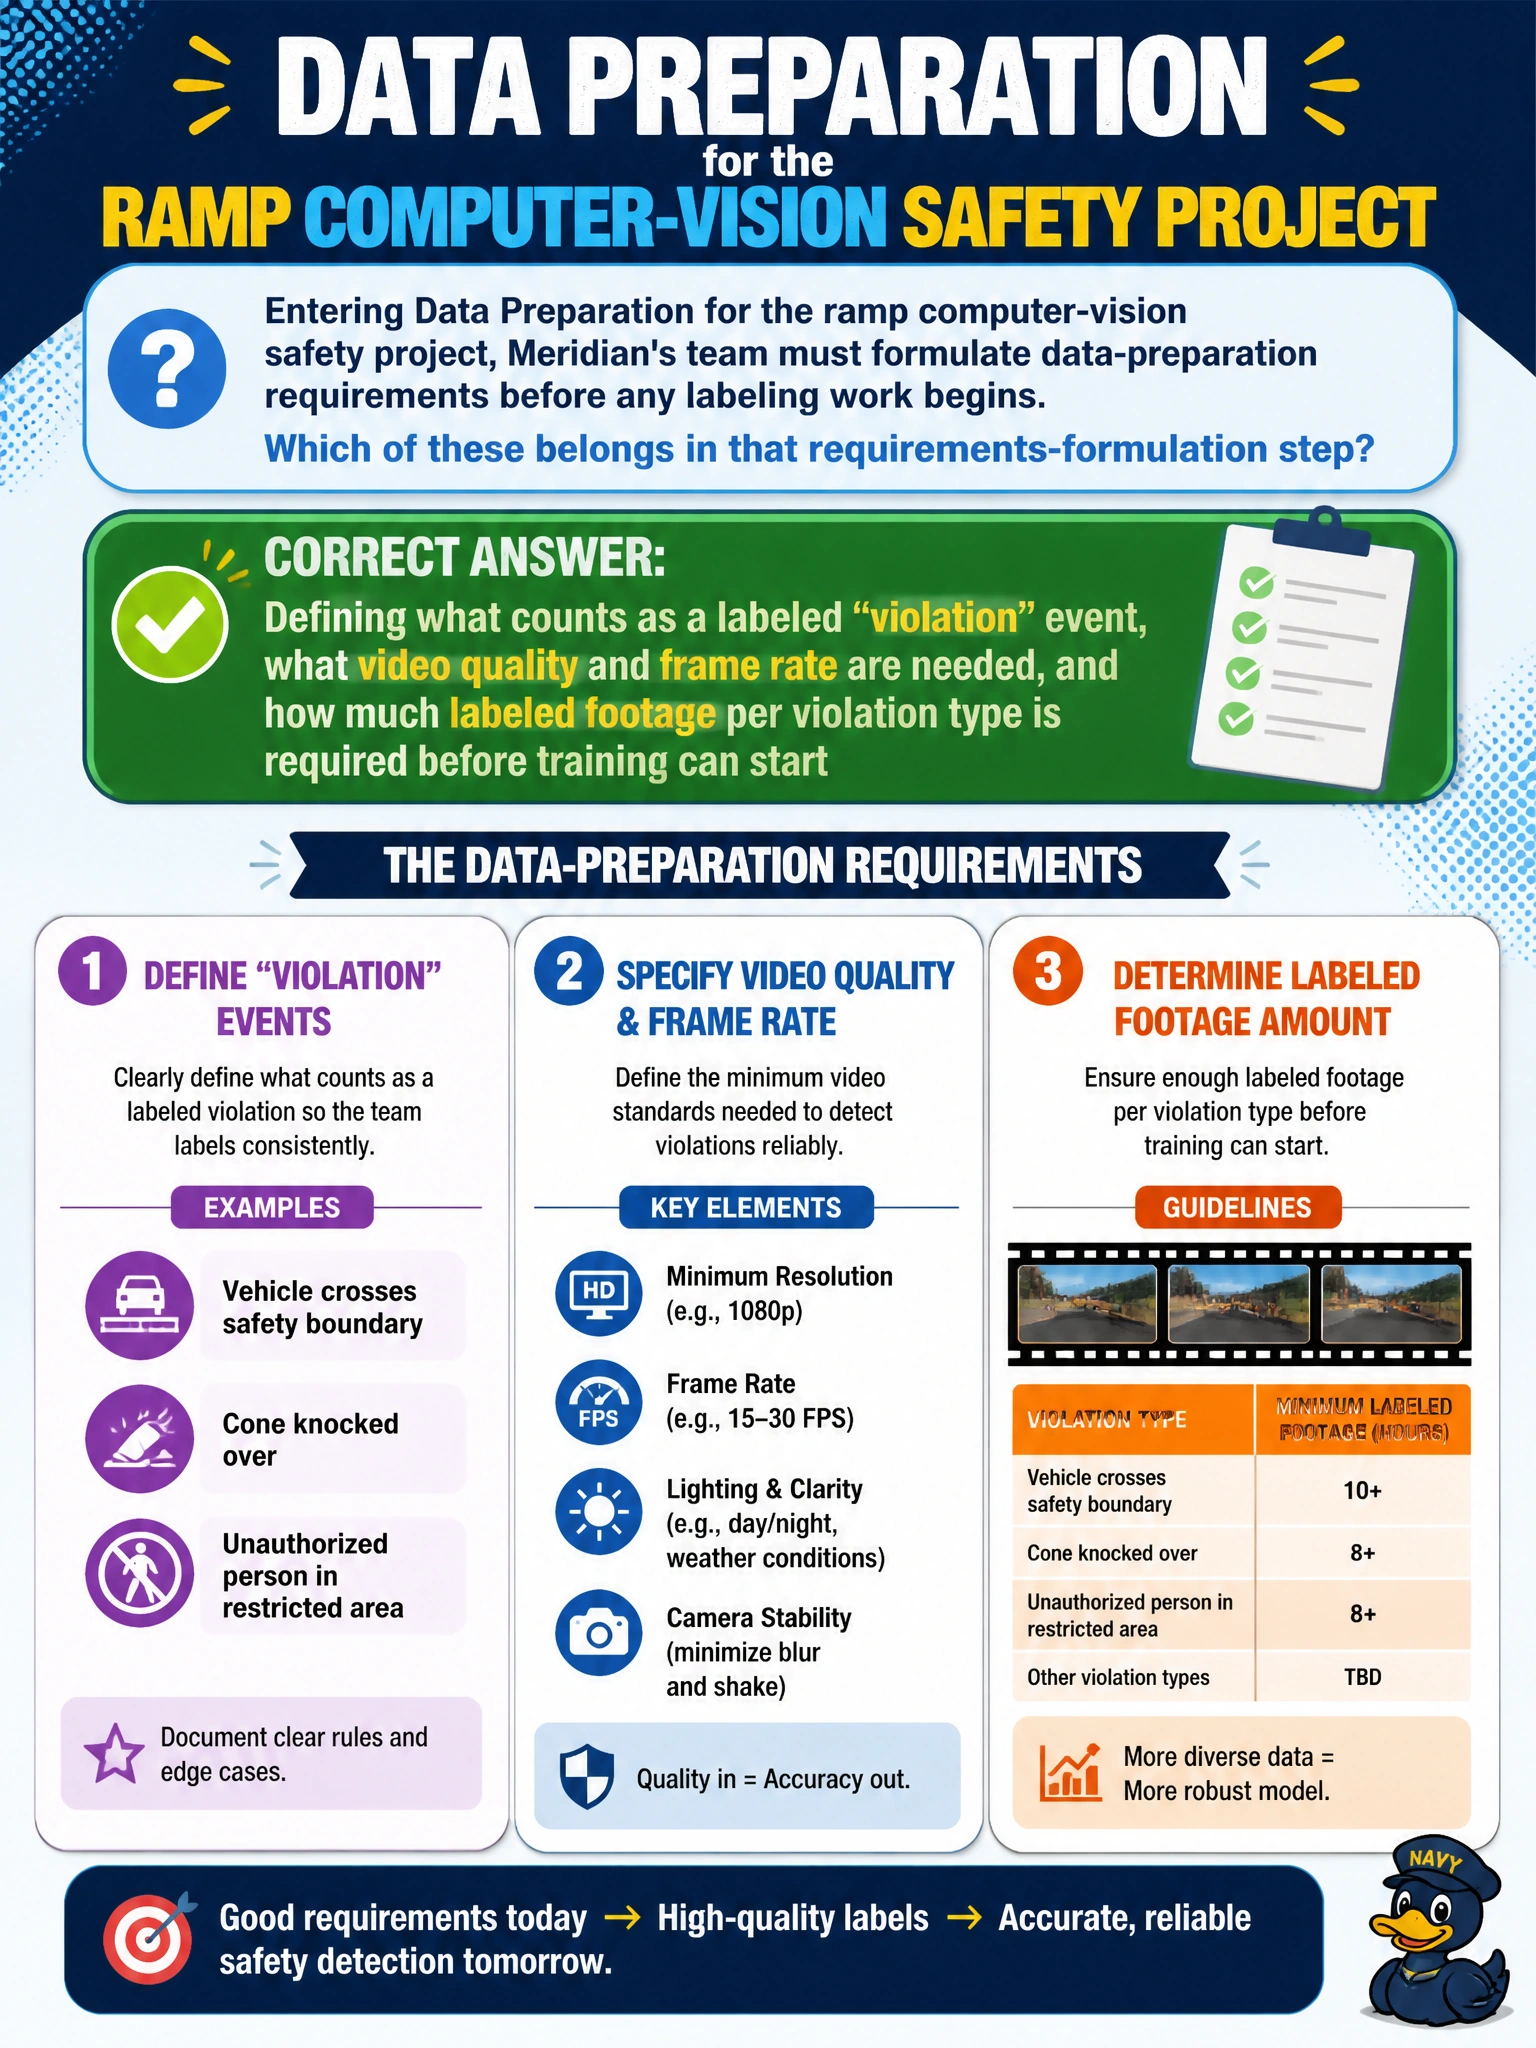
Entering Data Preparation for the ramp computer-vision safety project, Meridian's team must formulate data-preparation requirements before any labeling work begins. Which of these belongs in that requirements-formulation step?
Select an answer to reveal the explanation.
Short Explanation
Data-prep requirements are about what the data needs to look like before you train on it — clear labeling definitions, quality thresholds, and volume targets. Architecture choice and hosting come later; the newsletter never belongs in a CPMAI phase at all.
Full Explanation
Formulating data-preparation requirements means specifying, before labeling begins, what the prepared data must contain and look like: a clear operational definition of the target classes (what exactly counts as a "violation" versus normal ramp activity), technical quality thresholds (frame rate, resolution, lighting conditions), and sufficient volume per category so the eventual model has enough examples to learn from. Selecting the neural-network architecture is a Model Development activity — it happens after the data is prepared, and depends partly on what the prepared data turns out to look like. Choosing a cloud region for the inference endpoint is an Operationalization/deployment decision, far downstream and unrelated to how the training data gets prepared. Writing a newsletter description is a communications task with no place in a CPMAI phase task list at all — it's the kind of clearly out-of-scope distractor that signals it isn't testing the concept. Getting data-prep requirements wrong here specifically costs Meridian later: if "violation" isn't defined precisely up front, different annotators will label the same footage inconsistently, degrading the ground truth the eventual model is trained against.