
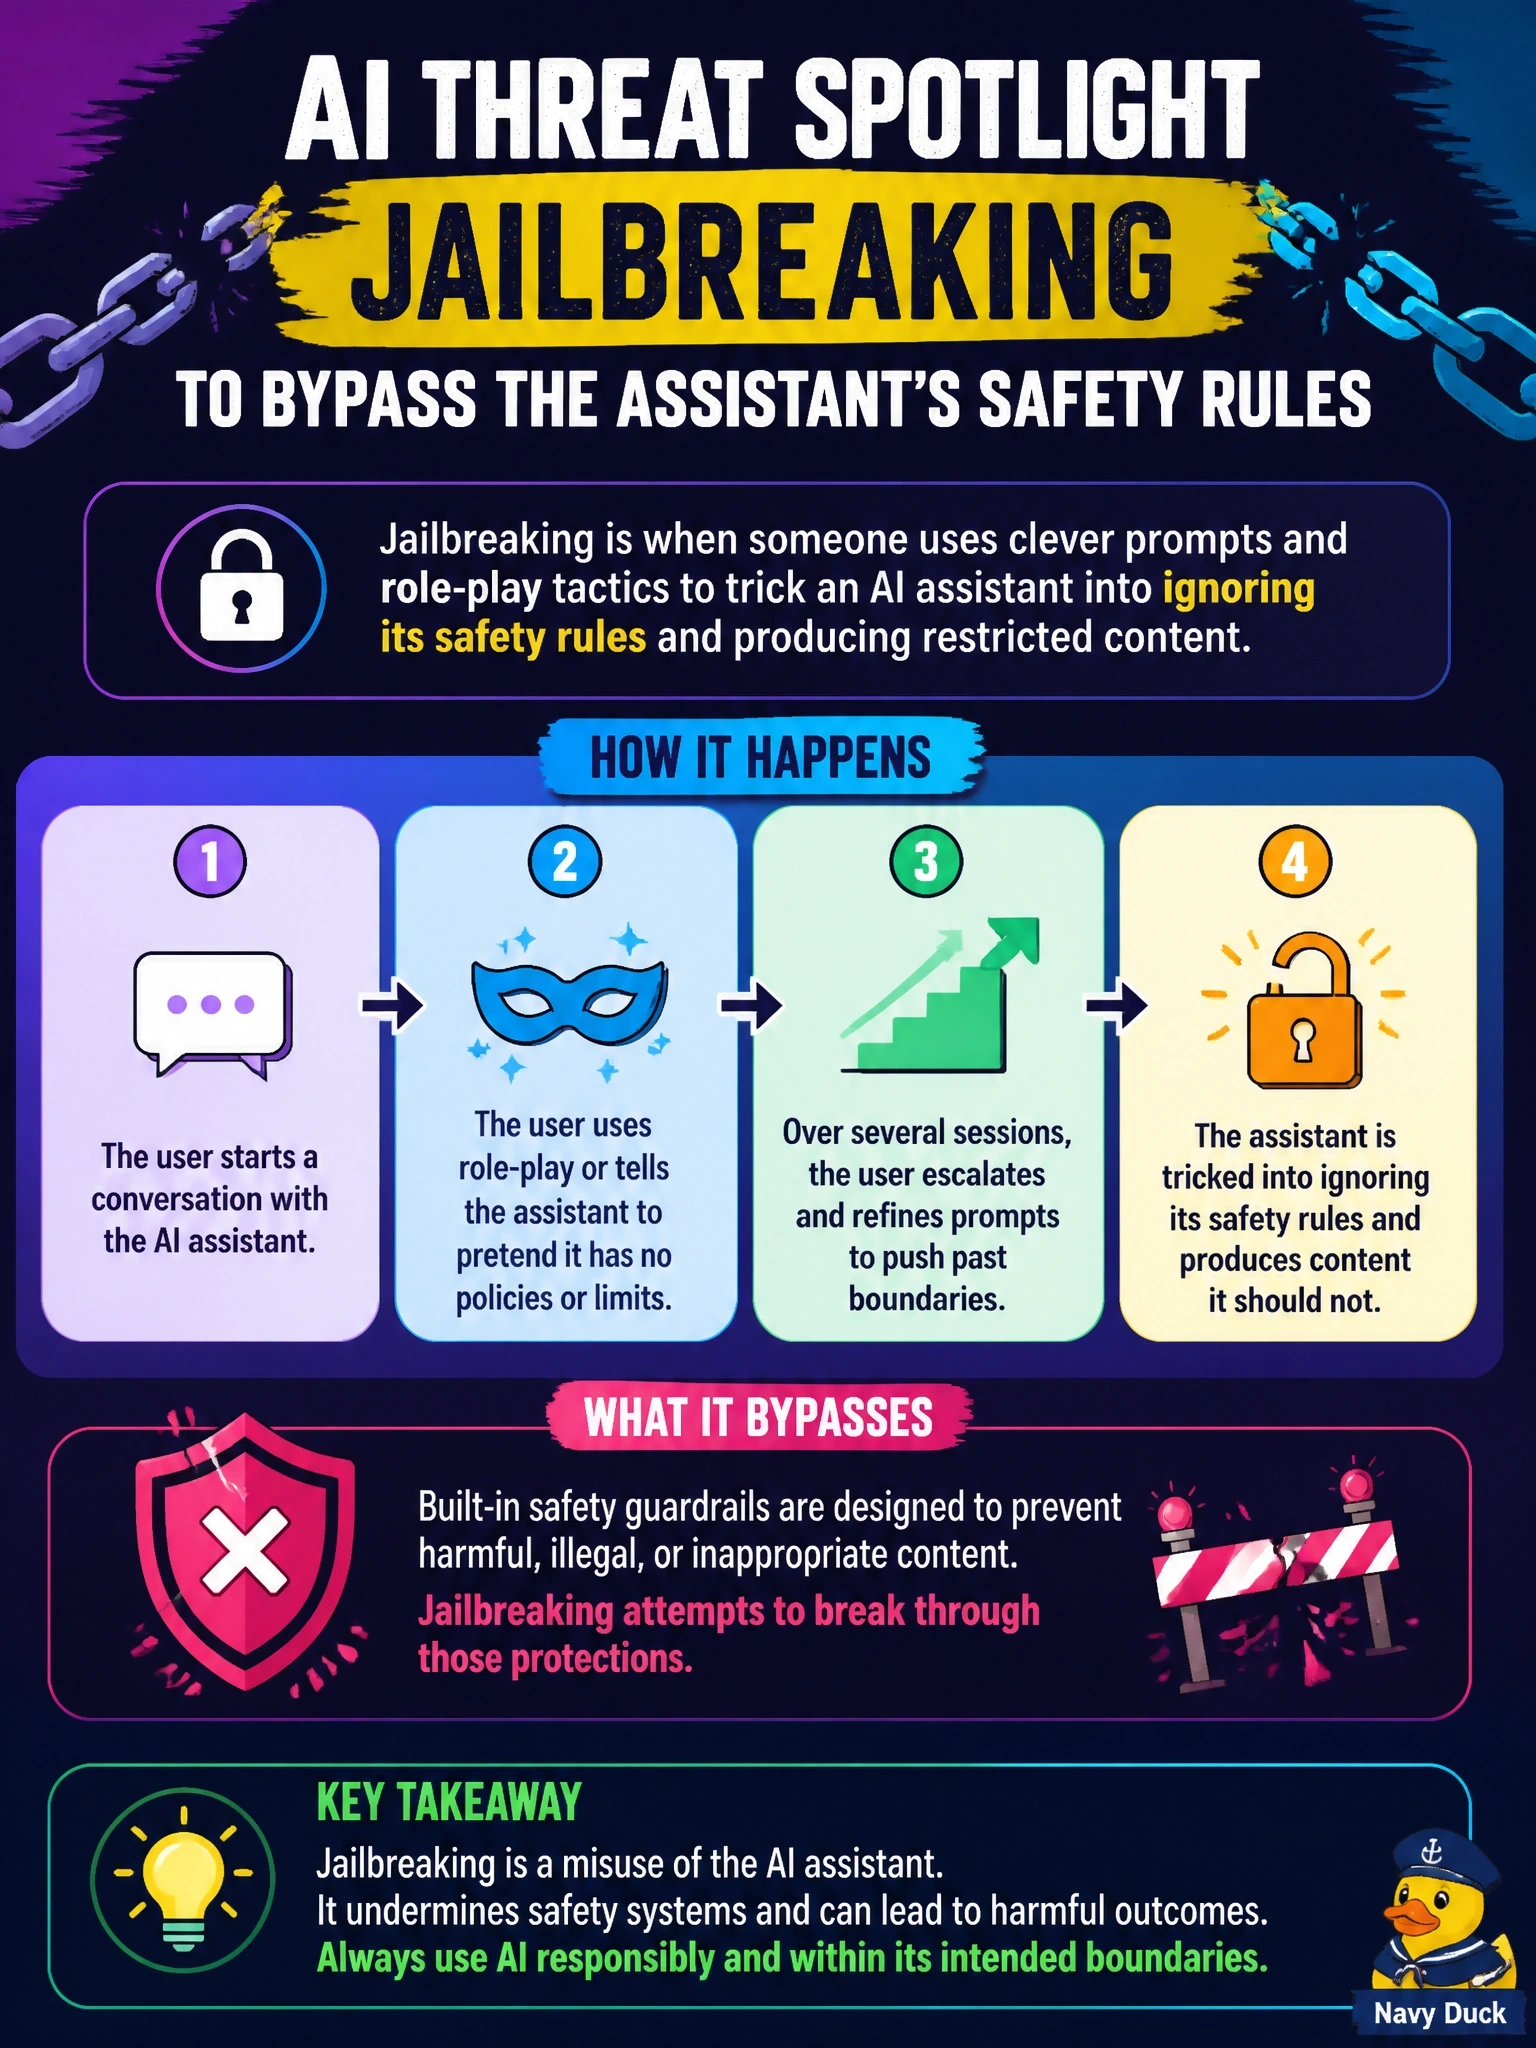
Over several sessions, an employee feeds an internal AI assistant elaborate role-play scenarios, such as asking it to pretend to be an unrestricted model with no policies, until it produces content its safety rules prohibit. No external documents, web pages, or files were involved. Which AI threat does this activity BEST represent?
Select an answer to reveal the explanation.
Short Explanation
It's like sweet-talking the bouncer with a story until he forgets the dress code. When you see a user craft role-play prompts to talk a model out of its own rules, that's jailbreaking. The trap is indirect prompt injection, which needs outside content, and the stem says there wasn't any.
Full Explanation
Jailbreaking is a technique in which the person interacting with a model crafts prompts designed to circumvent its safety policies and guardrails. Common methods include role-play framing, hypothetical scenarios, and persistent multi-turn persuasion that gradually moves the model away from its constraints. The defining traits here are that the user is the source of the manipulation and the goal is to unlock prohibited output. Indirect prompt injection places malicious instructions in content the model retrieves, such as documents or web pages; the stem explicitly rules out any external content, so the attack did not ride in on retrieved data. Model poisoning alters training data or the model itself so that it misbehaves for all users; this employee changed nothing in the model and only manipulated a conversation. Evasion attacks perturb inputs to make a classifier mislabel them, such as modified malware slipping past detection; that concerns classification accuracy rather than coaxing a generative assistant to violate its content policy. Exam caveat: jailbreaking and direct prompt injection overlap, but jailbreaking specifically targets the safety and policy layer rather than hijacking an application's task. Operational check: review the assistant's conversation logs for policy-bypass patterns, strengthen input and output guardrails, apply acceptable-use policy consequences, and test the assistant regularly against known jailbreak techniques.