
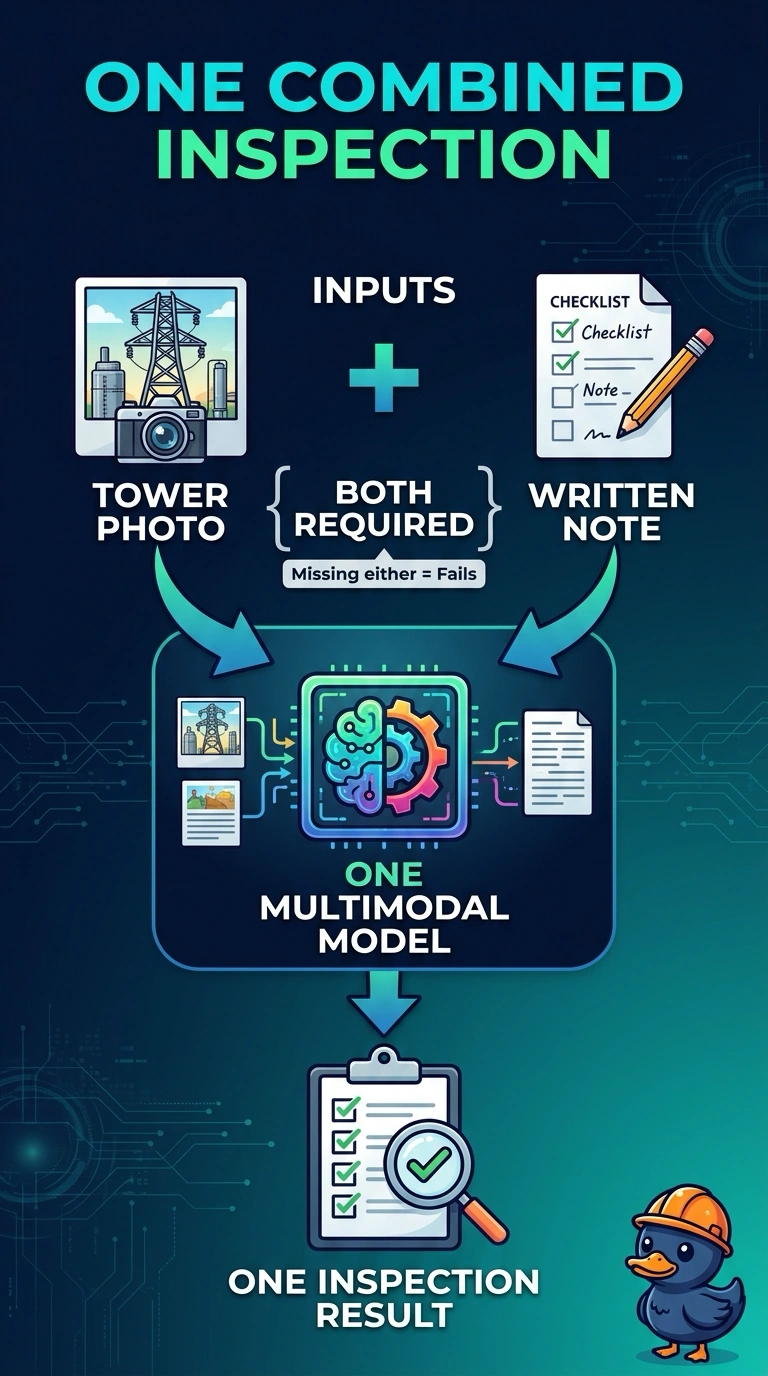
A utility model produces one inspection result from a tower photo and the technician's written note together. That result is not produced if either the photo or the note is removed. Which description fits this model?
Select an answer to reveal the explanation.
Short Explanation
A conclusion that collapses when you hide either the film or the note is using both. You have a multimodal model because the tower photo and the written note enter the same result. A vision-only or text-only model would still answer after you dropped the other input.
Full Explanation
A multimodal model takes more than one kind of input and uses them together in the same prediction. This inspection result is built from a tower photo and a written note, and it is not produced if either input is removed, so both kinds of input are required together. The photo is an image and the note is text, so the model is combining different kinds of input rather than two fields of one kind. A vision-only model would classify the photo without the note and would still produce a result after the note was removed. A text-only model would score the note and would still produce a result after the photo was removed. An anomaly model that scores the photo against ordinary towers and ignores the note uses one kind of input and does not match a result that dies when the note is absent. Exam caveat: storing the note beside a separate photo score is not a multimodal prediction unless the two inputs actually enter one result. Operational check: run the inspection twice, once without the photo and once without the note, and confirm neither run produces the original result.