
A retail loss-prevention model labels almost every transaction legitimate. Accuracy looks strong because that legitimate class supplies nearly all of the rows, yet the model rarely flags a theft. Which metric stays informative under that imbalance?
Select an answer to reveal the explanation.
Short Explanation
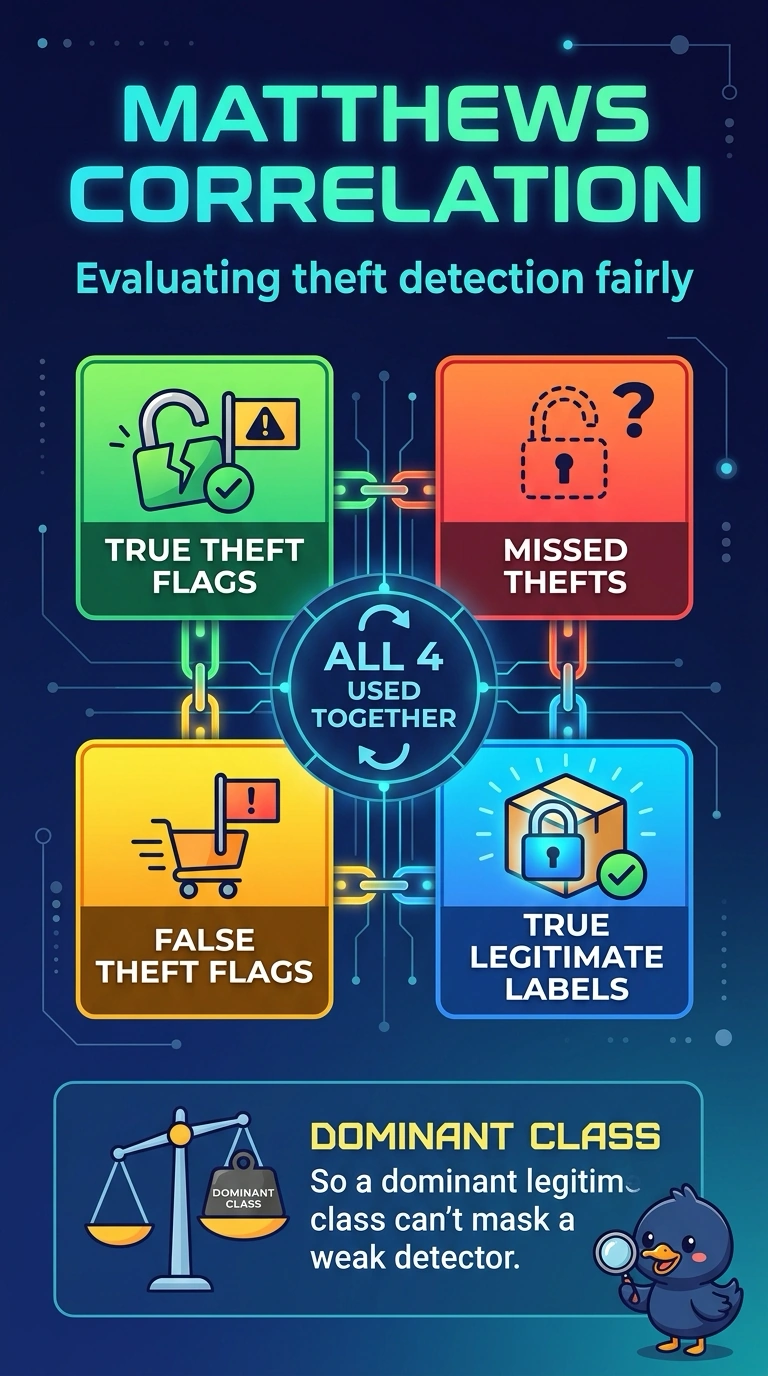
A class where almost every student passes can post a shiny average that hides the few who failed. Accuracy does that when legitimate transactions dominate, and Matthews correlation stays honest because it uses all four cells of the confusion matrix. Do not let the size of the legitimate class talk you into trusting accuracy here.
Full Explanation
Matthews correlation combines all four cells of the confusion matrix, so a large count of true legitimate labels cannot hide missed thefts and false theft flags. When a model mostly predicts the dominant class, accuracy rises with that class while Matthews correlation stays near zero unless the rare theft class is also handled well. Accuracy is the share of correct labels and is exactly the number the imbalance inflates, so it is the metric that looks strong while thefts are missed. The base rate of legitimate transactions describes how common that class is; it is not a detection score and does not measure how often theft is caught. A raw count of true legitimate labels grows with the majority class even if every theft is missed, so it cannot show that the detector works. Exam caveat: a high accuracy beside a Matthews correlation near zero is a warning that the majority class is carrying the accuracy, not proof that the two metrics disagree by arithmetic error. Operational check: build the four-cell table for theft versus legitimate, compute accuracy and Matthews correlation from those same cells, and confirm accuracy stays high when missed thefts are still numerous.