
A retail grocery chain fits a linear model of weekly sales on many promo flags and puts an L1 penalty on the coefficients. What can that penalty do that an L2 penalty does not?
Select an answer to reveal the explanation.
Short Explanation
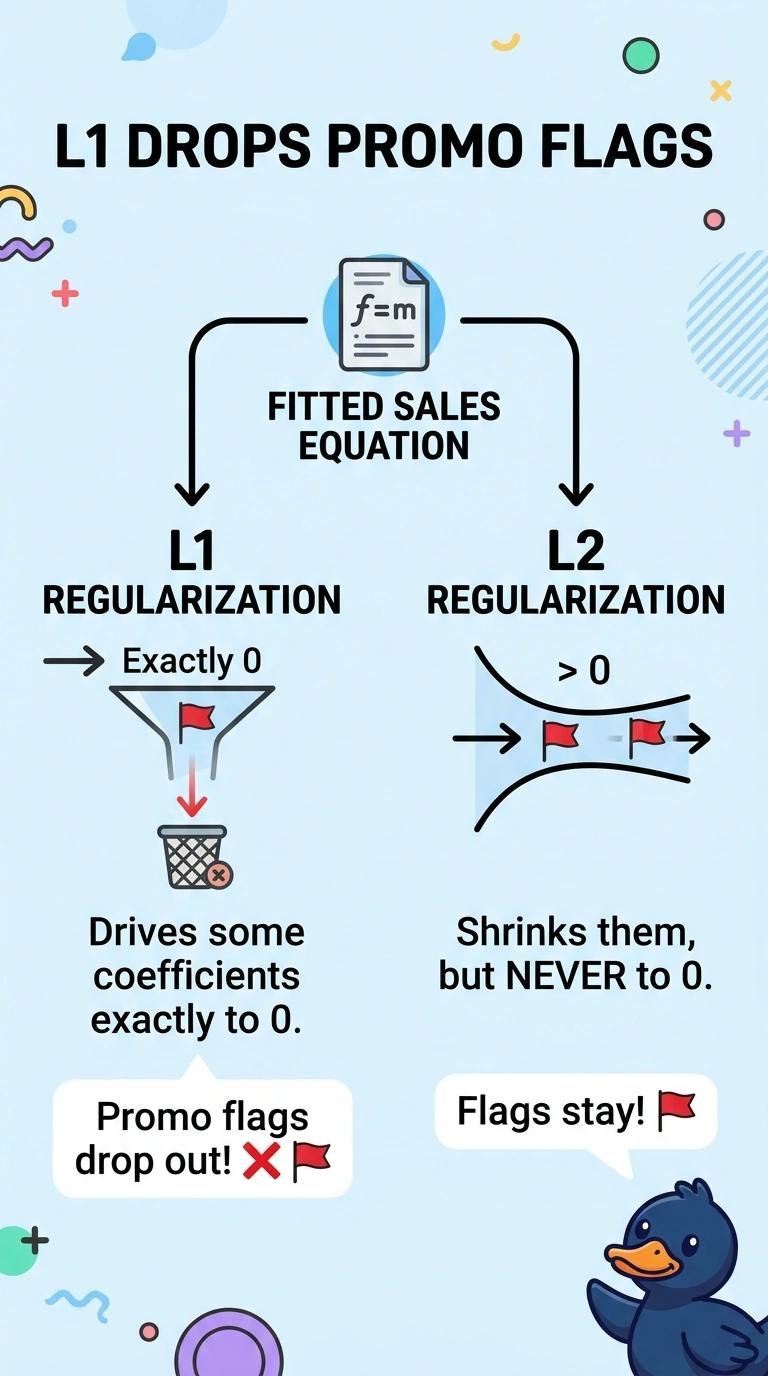
An L1 penalty can turn a promo flag all the way off until its coefficient is exactly zero. You do not get that hard shutoff from an L2 penalty, which only eases every knob down a bit. The trap is describing ridge shrinkage and calling it the L1 result.
Full Explanation
An L1 penalty adds a cost proportional to the absolute value of each coefficient. That geometry can push some coefficients to exactly zero, so the corresponding promo flags drop out of the fitted linear equation while others remain. An L2 penalty adds a cost proportional to the squared coefficients. It shrinks coefficients toward zero but does not, in ordinary use, set them exactly to zero, so the description of every flag staying slightly nonzero is the L2 behavior, not the extra thing L1 can do. Forcing every coefficient to one shared value is not what either penalty does; the flags are still allowed to differ. Dropping the intercept is a separate modeling choice about the origin, and neither the L1 nor the L2 penalty on the coefficients removes the intercept by itself. Exam caveat: L1 can produce exact zeros; it does not promise that every weak flag becomes zero in every fit. Operational check: inspect the fitted coefficients and see whether a stronger L1 penalty sets some promo flags to exact zero while an L2 refit on the same data leaves those flags nonzero.