
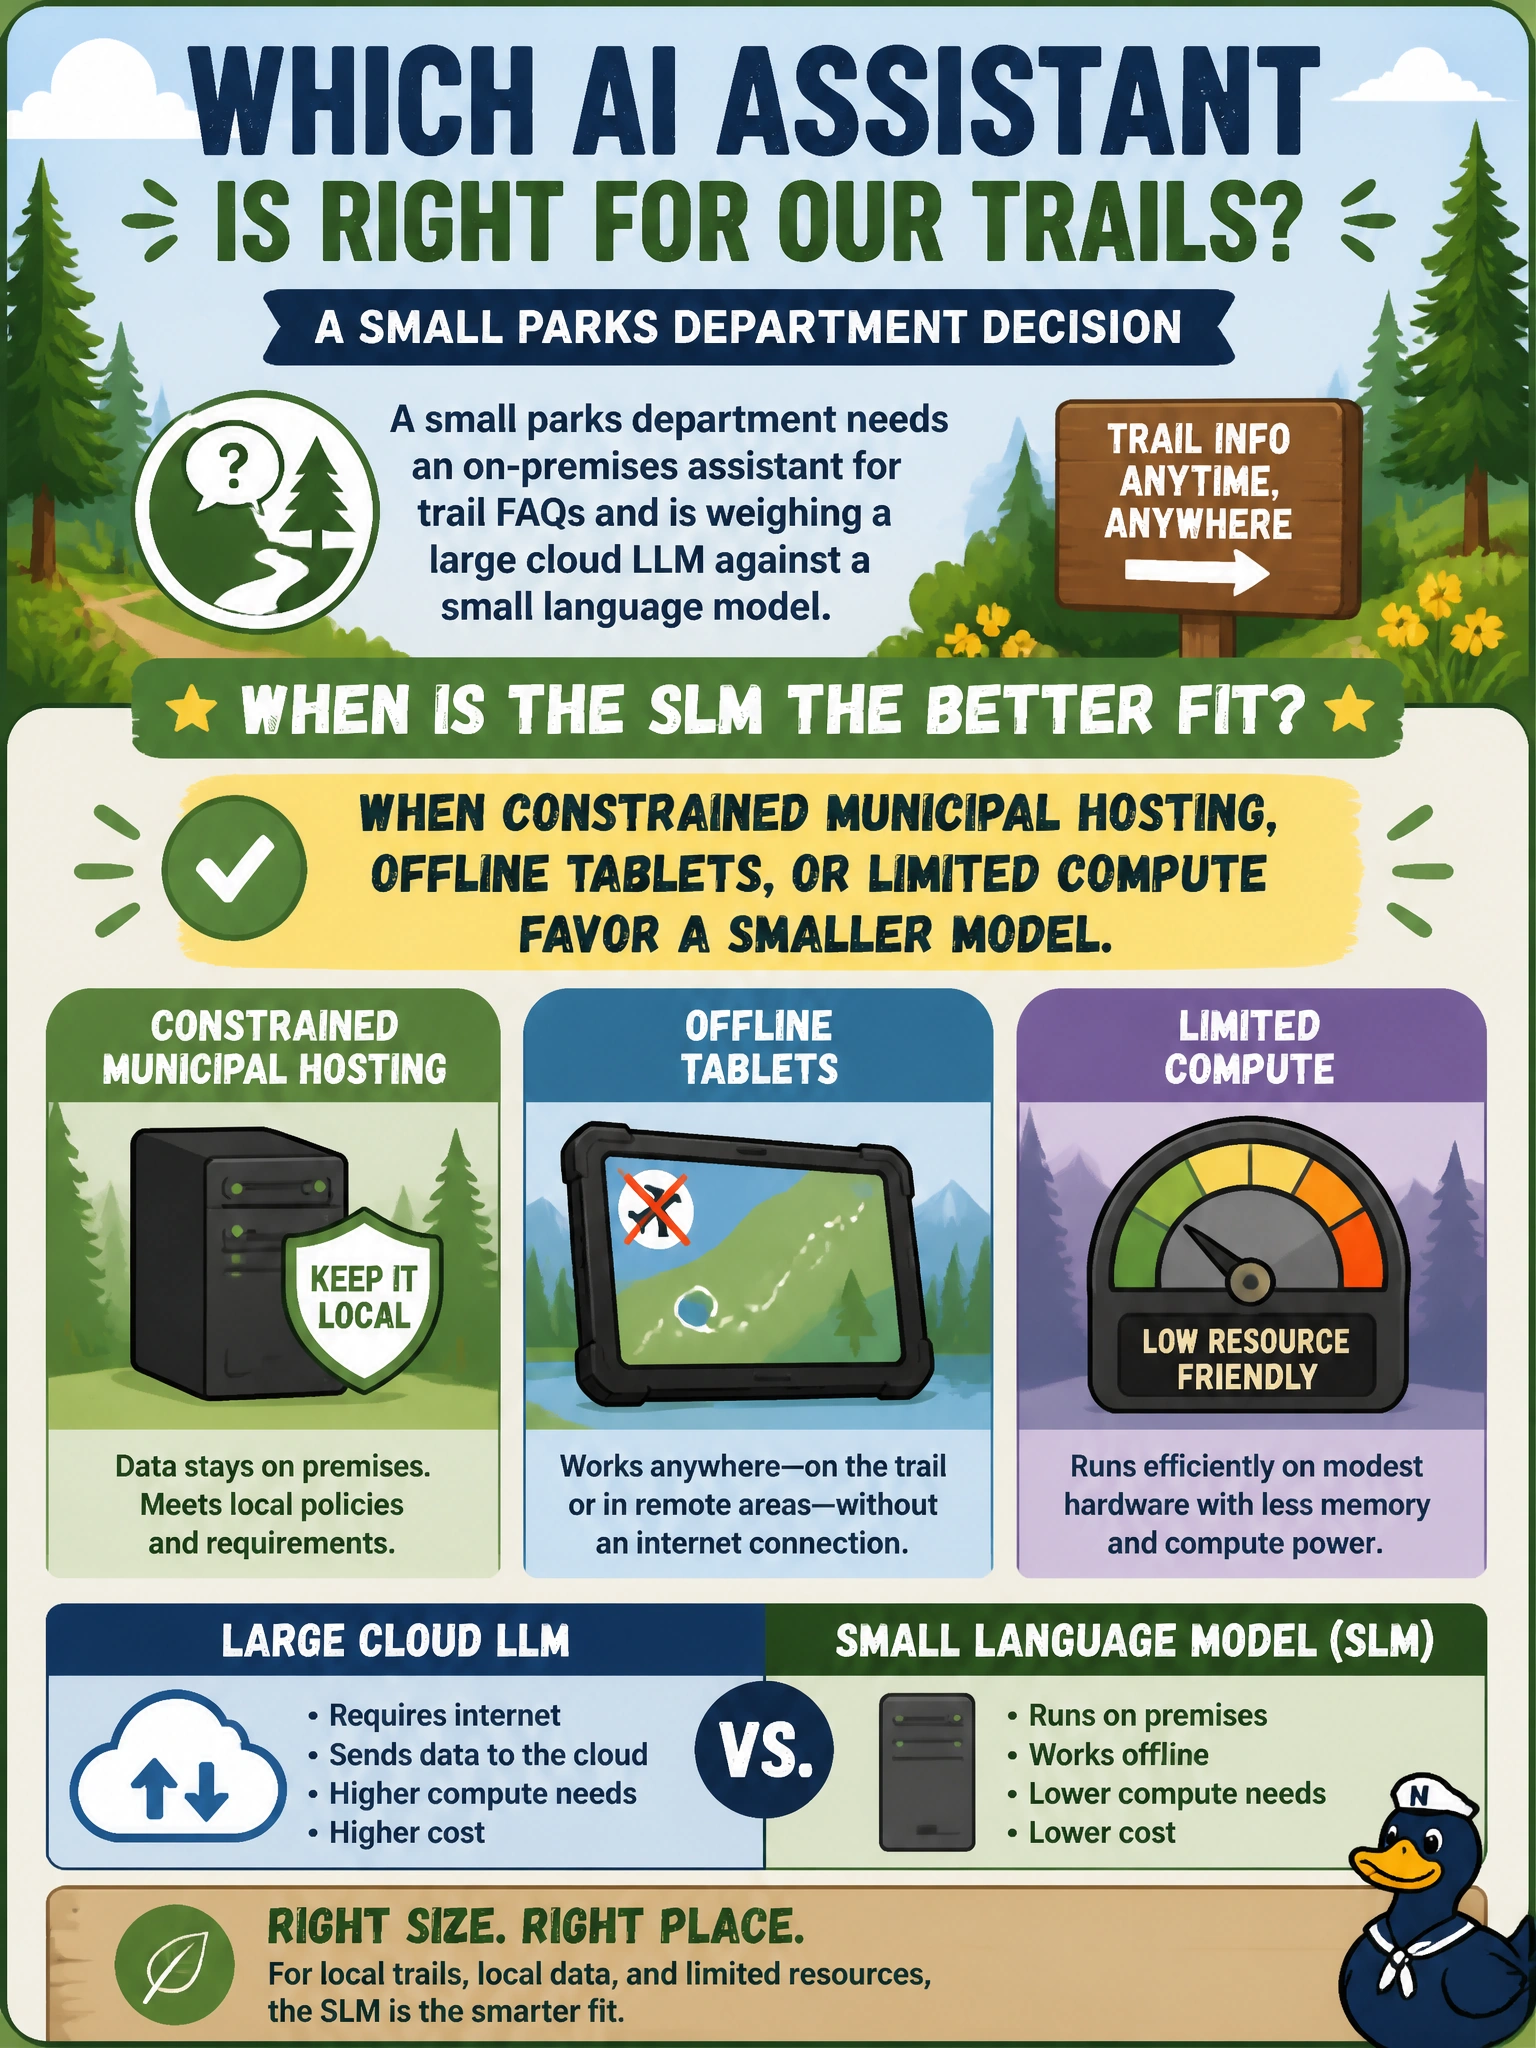
A small parks department needs an on-premises assistant for trail FAQs and is weighing a large cloud LLM against a small language model. When is the SLM the better fit?
Select an answer to reveal the explanation.
Short Explanation
Big cloud LLMs are like renting a stadium PA when you only need a park megaphone. If the trails FAQ has to stay on-prem or on tablets with tight compute, a small language model fits the municipal constraint box better.
Full Explanation
Choosing a small language model over a large cloud LLM is appropriate when constrained municipal hosting, offline tablets, or limited compute make a compact on-premises assistant the feasible parks FAQ solution. The SLM fits because trail FAQs are a bounded corpus: accuracy depends more on grounded local content and deployability than on multi-hop synthesis, which municipal hosting or offline tablets do not make a smaller model better at. Favoring a smaller model for multi-hop synthesis under municipal hosting or offline tablets fails by concept when the requirement is on-prem or offline operation—multi-hop synthesis is a large-model strength that presumes broader knowledge and heavy compute, not what makes a smaller model the better fit under municipal constraints. Favoring a smaller model for agentic tool chaining under limited compute or offline tablets fails because reliable chaining demands robust planning, tool-use accuracy, and error recovery that small models handle less reliably, while a compact on-premises SLM plus retrieval serves controlled, local FAQs without that orchestration overhead. Favoring a smaller model for cross-domain planning under municipal hosting or limited compute fails because cross-domain planning demands broad knowledge and general reasoning that are large-model strengths, so claiming a smaller model is preferred for that capability does not hold when infrastructure, budget, or air-gapped field devices call for deploying a small pre-trained model for bounded FAQ inference. Exam caveat: SLMs may need stronger retrieval grounding and more careful evaluation on edge cases; smaller size is not automatically more private if logging or sync paths still leak data. Operational check: measure answer quality on the parks FAQ gold set for candidate SLMs, confirm offline tablet resource budgets, and document when queries must escalate to a larger model or human ranger.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.