
After green is validated and the Service points at green Pods, what is an appropriate teardown step for the old blue Deployment?
Select an answer to reveal the explanation.
Short Explanation
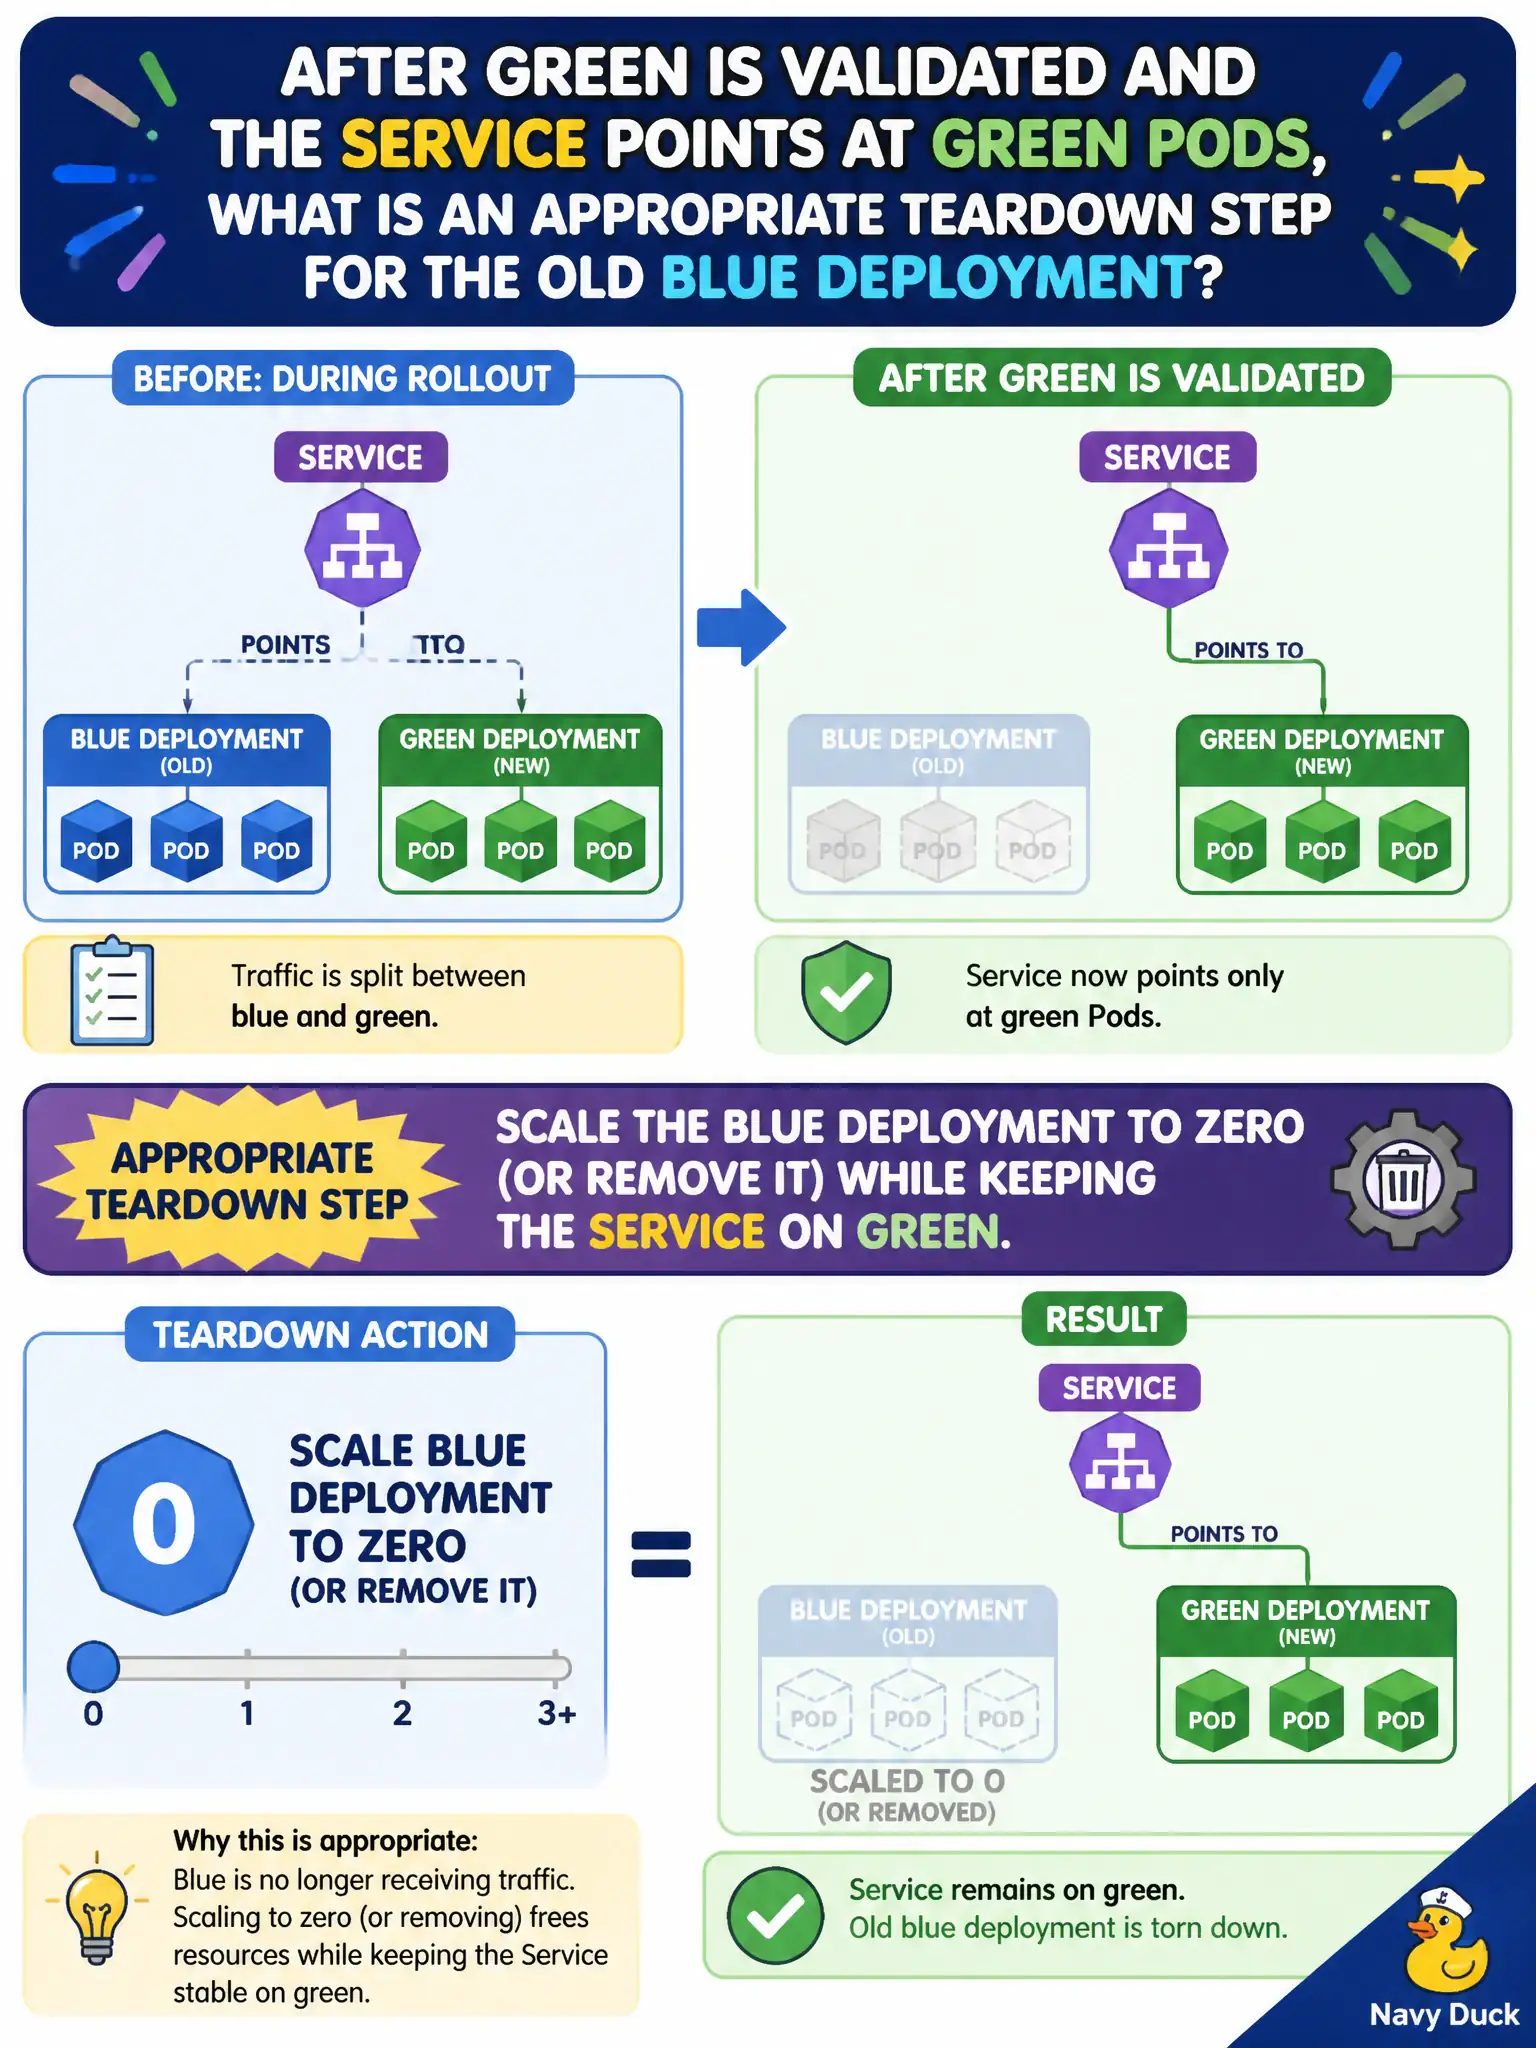
Show’s over for blue—dim those lights by scaling blue to zero, but leave the Service ticket booth aimed at green. Deleting the Service just locks out your users.
Full Explanation
After green is validated and the Service points at green Pods, an appropriate teardown step for the old blue Deployment is to scale blue to zero (or remove it) while keeping the Service on green. That frees capacity without disturbing the live selector that now serves the city site.
Deleting the Service so blue Pods lose ClusterIP also drops green traffic—an outage. Patching kube-proxy ConfigMaps by hand is unsupported. Recreating Ingress with a new UID to flush blue is unnecessary if Service already selects green.
Exam caveat: Order matters—shift traffic first, observe, then decommission blue. Keep blue warm briefly for fast rollback on municipal launch nights.
Operational check: kubectl get endpoints show only green; kubectl scale deploy/blue --replicas=0; confirm site health; delete blue after the soak period. In municipal environments, document the chosen pattern in the service runbook so on-call engineers apply the same kubectl checks during incidents, and keep the change tied to the application Deployment or Job rather than ad-hoc node mutation. In municipal environments, document the chosen pattern in the service runbook so on-call engineers apply the same kubectl checks during incidents, and keep the change tied to the application Deployment or Job rather than ad-hoc node mutation.