
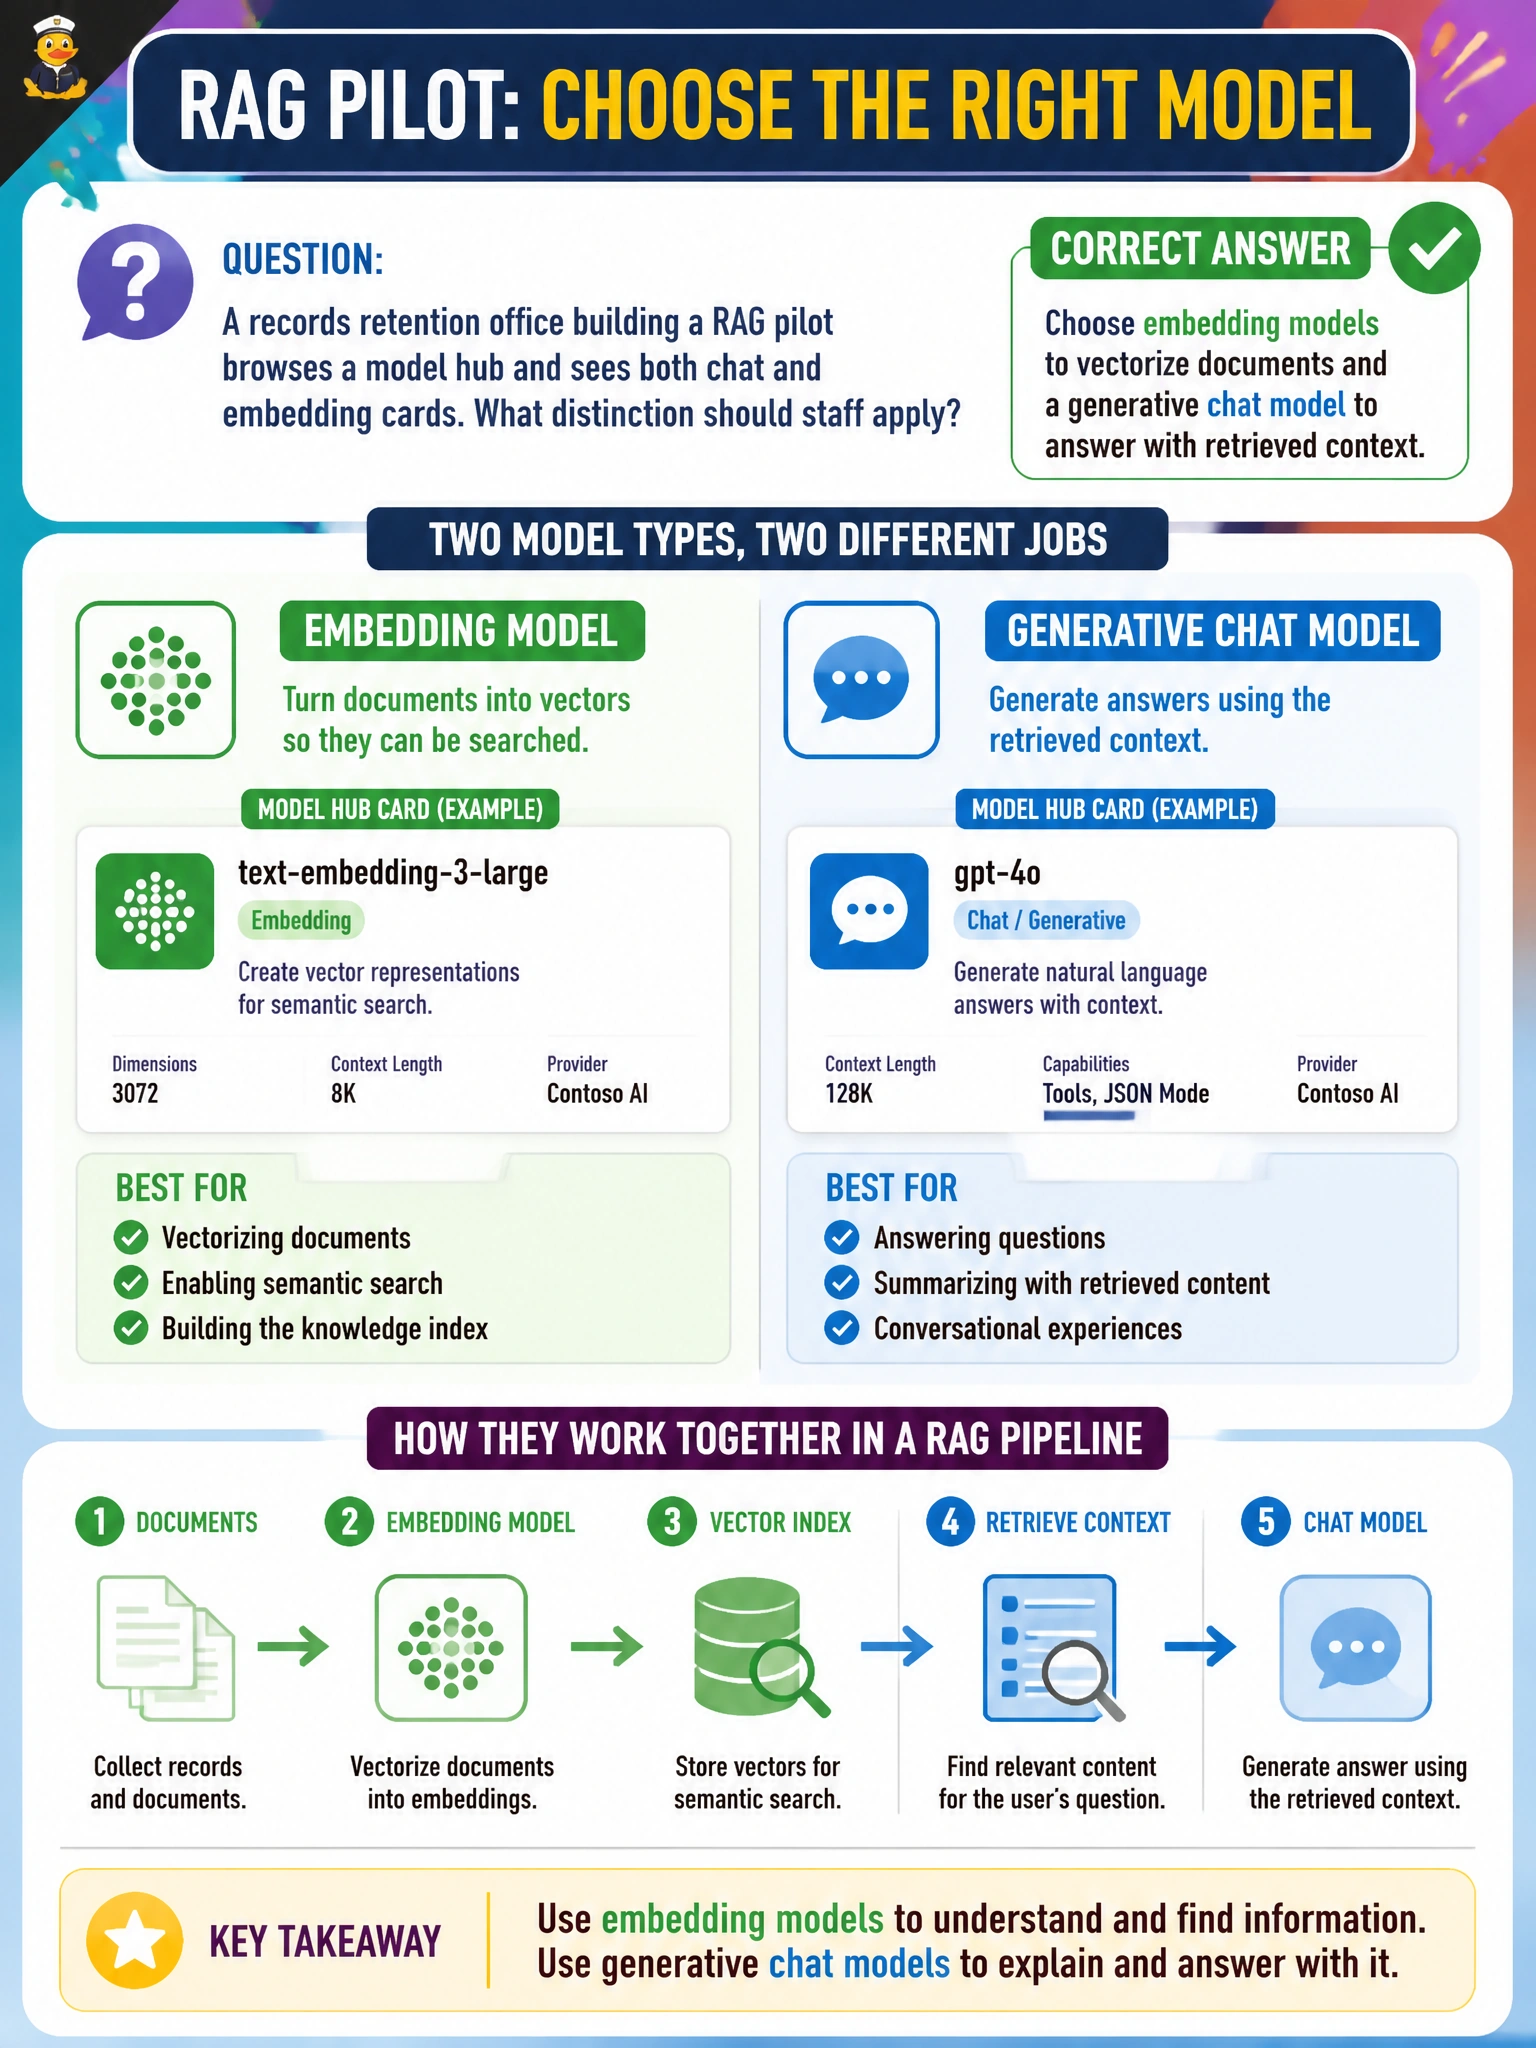
A records retention office building a RAG pilot browses a model hub and sees both chat and embedding cards. What distinction should staff apply?
Select an answer to reveal the explanation.
Short Explanation
Embeddings are the filing labels; the chat model is the clerk who reads the pulled folders and answers. Don't mix up the label maker with the clerk.
Full Explanation
A records-retention RAG pilot needs two different hub roles: embedding models to vectorize document chunks into an index, and a generative chat model to answer using retrieved passages. Staff should apply that distinction when browsing cards rather than treating every model as interchangeable. Correct pairing is what makes retrieval-augmented generation work for municipal records search.
Embedding and chat cards are not interchangeable for every civic workflow—embeddings encode similarity space; chat models generate language conditioned on prompts and context. Only chat models creating vector indexes while embeddings are "decorative" reverses the architecture: embeddings build the index; chat consumes retrieved text. Diffusion cards replace neither embeddings nor chat for records search; image generation does not vectorize retention schedules or answer records queries.
Exam caveat: embedding and chat models should be compatible with the same retrieval pipeline (chunking, metadata filters, citation format) and evaluated together, not in isolation. Operational check: select an embedding card for the records corpus, select a chat card for answer generation, and verify end-to-end that retrieved retention passages appear in grounded answers.