
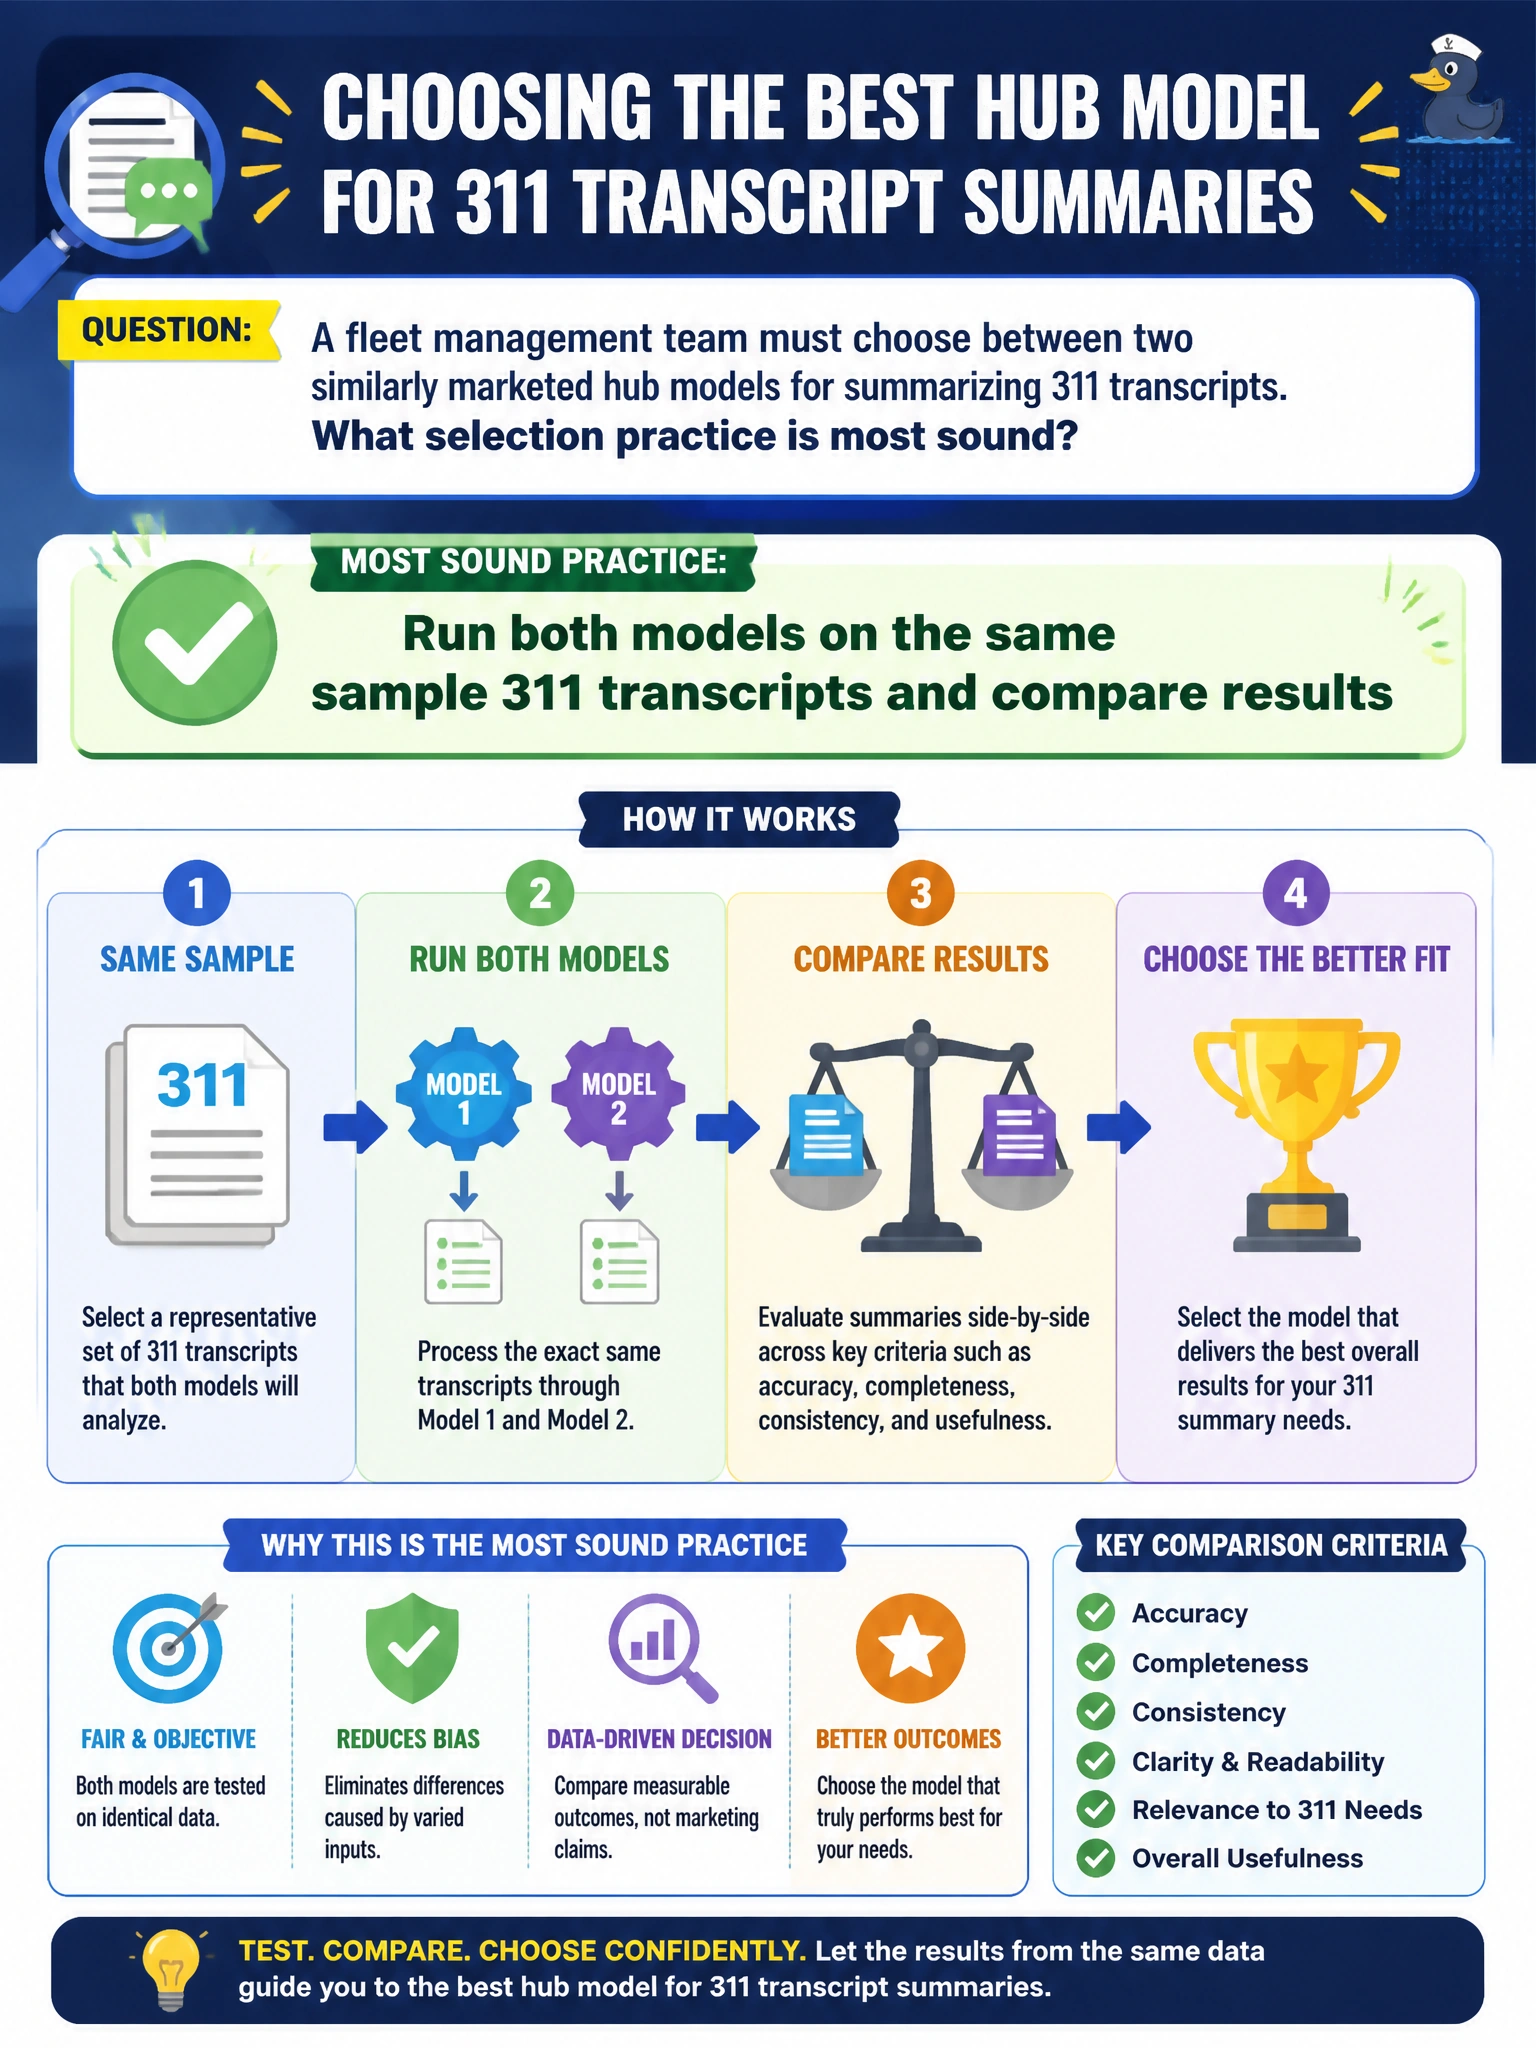
A fleet management team must choose between two similarly marketed hub models for summarizing 311 transcripts. What selection practice is most sound?
Select an answer to reveal the explanation.
Short Explanation
Don't marry a model because of the booth swag. Line up the same 311 samples, run both, and keep the one that actually summarizes better.
Full Explanation
Fleet management choosing between two similarly marketed hub models for summarizing 311 transcripts should decide with evidence drawn from the real workload, not vendor narrative. Running both models on the same sample 311 transcripts and comparing results grounds selection in observed summary quality, faithfulness to the call text, actionability for dispatch, latency, and PII handling. Side-by-side evaluation is the sound municipal practice when marketing claims, logos, and feature lists look interchangeable.
Picking the model whose logo uses the city's official Pantone confuses visual identity guidelines with summarization performance on citizen service requests. Choosing whichever vendor sponsored the last transit expo booth imports sponsorship bias and does not measure transcript quality. Defaulting to the alphabetically first model card on the hub page is arbitrary catalog ordering and is not an evaluation method.
Exam caveat: freeze a held-out transcript set and a predefined rubric so the comparison is repeatable for procurement records and cannot be gamed by one-off cherry-picked demos. Operational check: sample representative 311 transcripts across request types, blind-score both models with fleet analysts on the rubric, and select the winner from totals rather than sales relationships or booth swag.