
A 911 records lake fabric stages training batches on GPU servers. What host memory evaluation prevents GPUs from going idle?
Select an answer to reveal the explanation.
Short Explanation
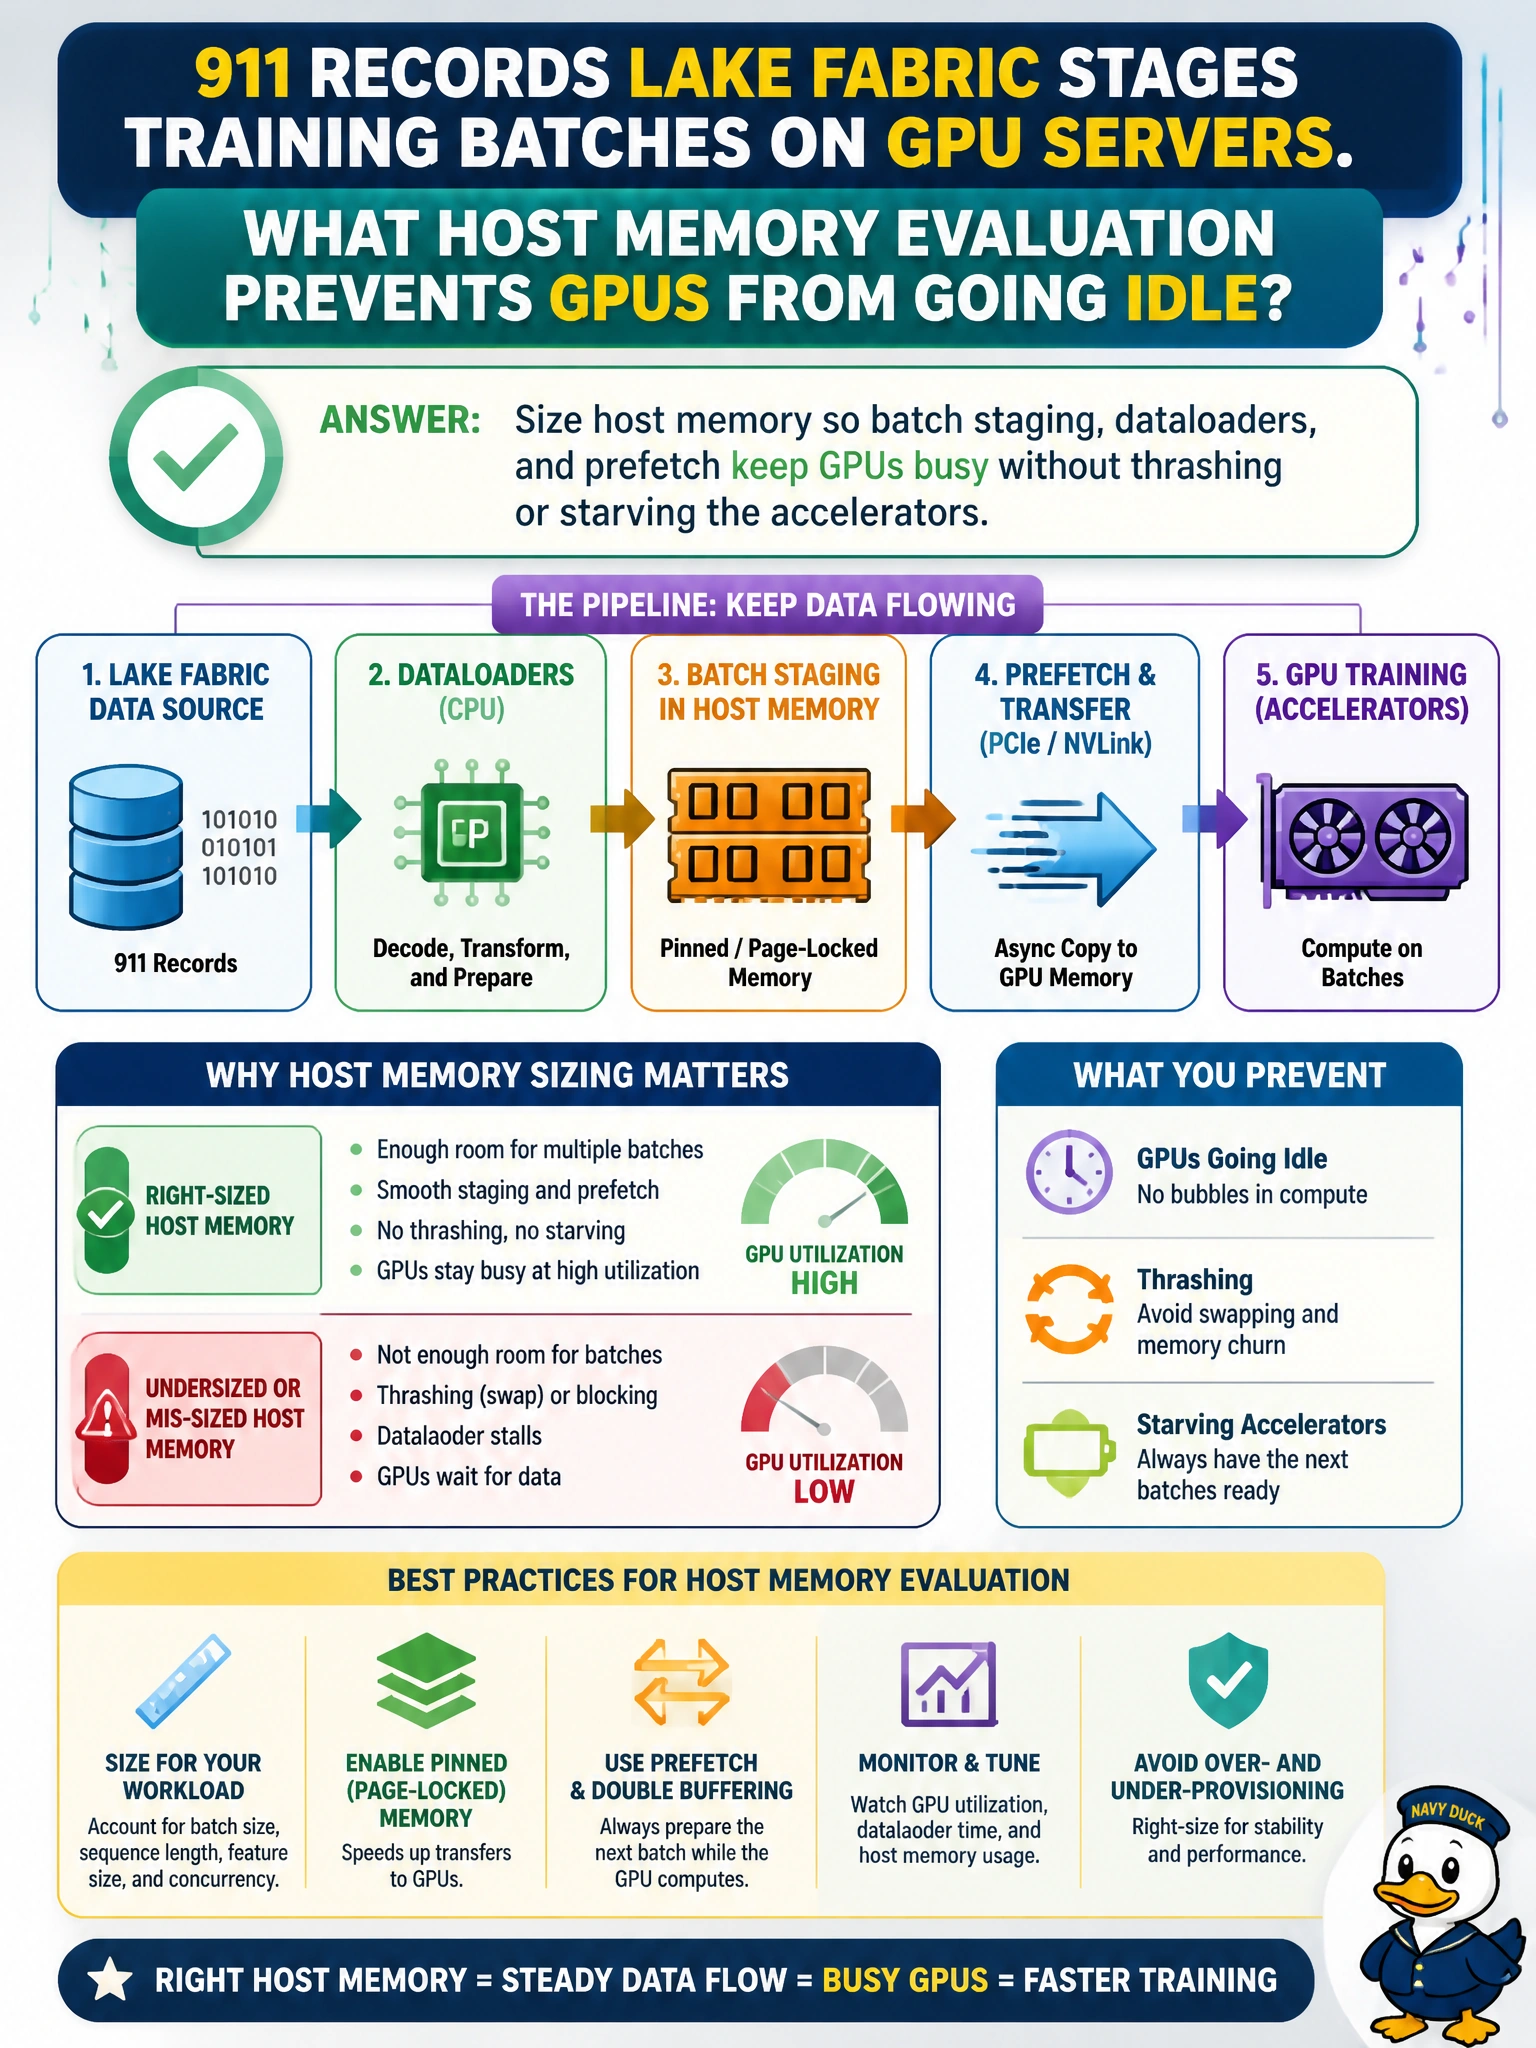
GPUs are race cars waiting in the pits—if the crew (host memory and dataloaders) can’t stage the next set of tires (batches), the cars sit there burning money. Give the host enough RAM to keep batches ready so the GPUs stay on track.
Full Explanation
Evaluating host DRAM only for optimizer offload and gradient buffers to keep GPUs busy without paging model states during training steps ignores the batch-staging path; dataloaders and prefetch buffers still need host RAM to queue samples, and sizing memory around paging model states leaves GPUs starving for data. Sizing host RAM so batch staging keeps GPUs busy without thrashing works because AI compute evaluation includes the host input path: if samples cannot be decoded, augmented, and queued in DRAM fast enough, GPUs stall even when the model and fabric are healthy. Adequate host memory aligns utilization with the civic training workload rather than leaving accelerators idle behind an I/O/memory wall.
Sizing host memory for checkpoint staging, write-ahead logs, and OS reserves to keep GPUs busy without stalling for worker restarts misdirects the evaluation; recovery reserves do not address the per-iteration batch staging that keeps GPUs busy during training. Provisioning host DRAM to cache validation datasets in memory to keep GPUs busy without waiting on evaluation loads between epochs addresses the wrong phase; validation caching does not solve the training batch staging problem, and GPUs can still idle while waiting for the next training batch.
Exam caveat: host memory sizing interacts with storage throughput and CPU decode capacity; huge DRAM with a slow NFS mount or single-threaded loader still starves GPUs. Operational check: monitor GPU utilization alongside host cache hit rate, dataloader wait time, and swap activity during a full 911 training epoch; increase host RAM or fix the loader when accelerators wait on staging rather than on compute.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.