
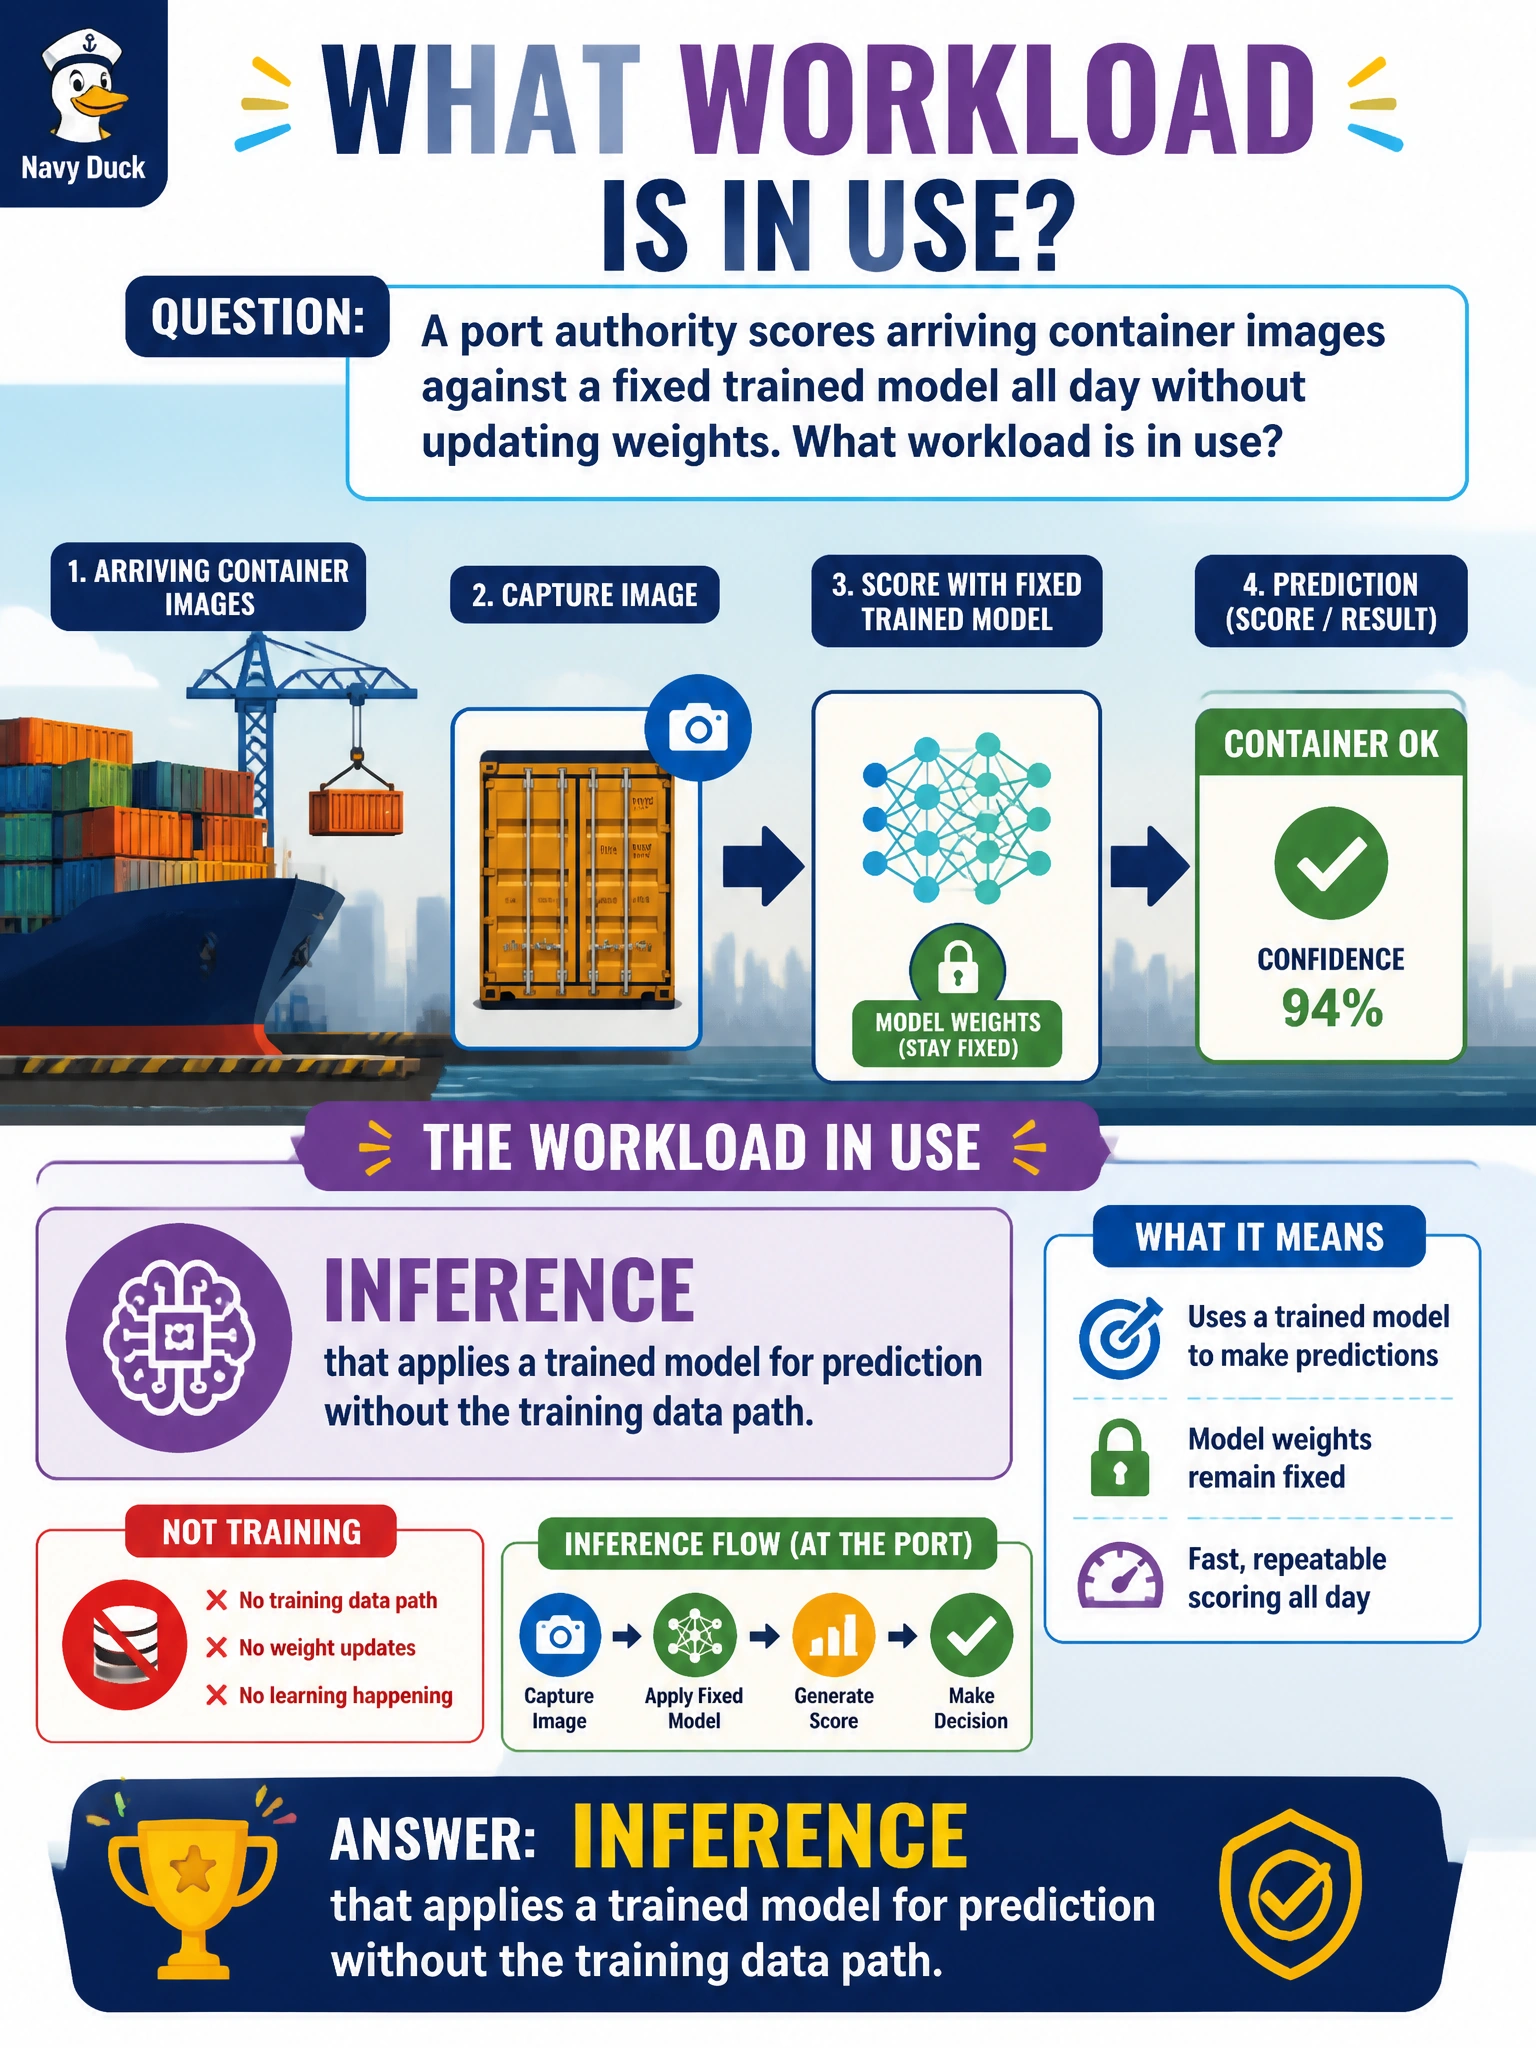
A port authority scores arriving container images against a fixed trained model all day without updating weights. What workload is in use?
Select an answer to reveal the explanation.
Short Explanation
You’re grading every new container photo with the same trained model all day—no homework, just grading. That’s inference on a fixed model, not supervised training that fits decision boundaries using labeled container photo batches.
Full Explanation
A port authority scoring arriving container images against a fixed trained model all day without updating weights is running inference: applying a trained model for prediction without the training data path or an online weight-update loop. Supervised training that fits decision boundaries using labeled container photo batches would still rewrite weights from labeled batches and incur optimizer cost, not the stem’s fixed-model all-day scoring. Fine-tuning that adapts a pretrained backbone to new container defect types updates the backbone weights for those defect types; it is not the fixed, no-update scoring run described in the stem. Offline evaluation that measures model accuracy on labeled test images before deployment is a pre-deployment accuracy check, not the live all-day gate scoring of arriving containers with a pinned checkpoint. Exam caveat: the same municipal cluster may later schedule a training job when labeled container data accumulates; that future training job is separate from today’s inference scoring and must not be confused with it on capacity plans. Operational check: confirm serving loads a pinned model version, that no optimizer or weight-update path runs on the scoring service, that throughput meets vessel-arrival rates, and that operators do not mis-label the job as fine-tuning or offline evaluation work.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.