
A computer vision engineer is training a convolutional neural network (CNN) to classify images but has a limited number of training samples. They decide to apply data augmentation. What is the main purpose of this technique?
Select an answer to reveal the explanation.
Short Explanation
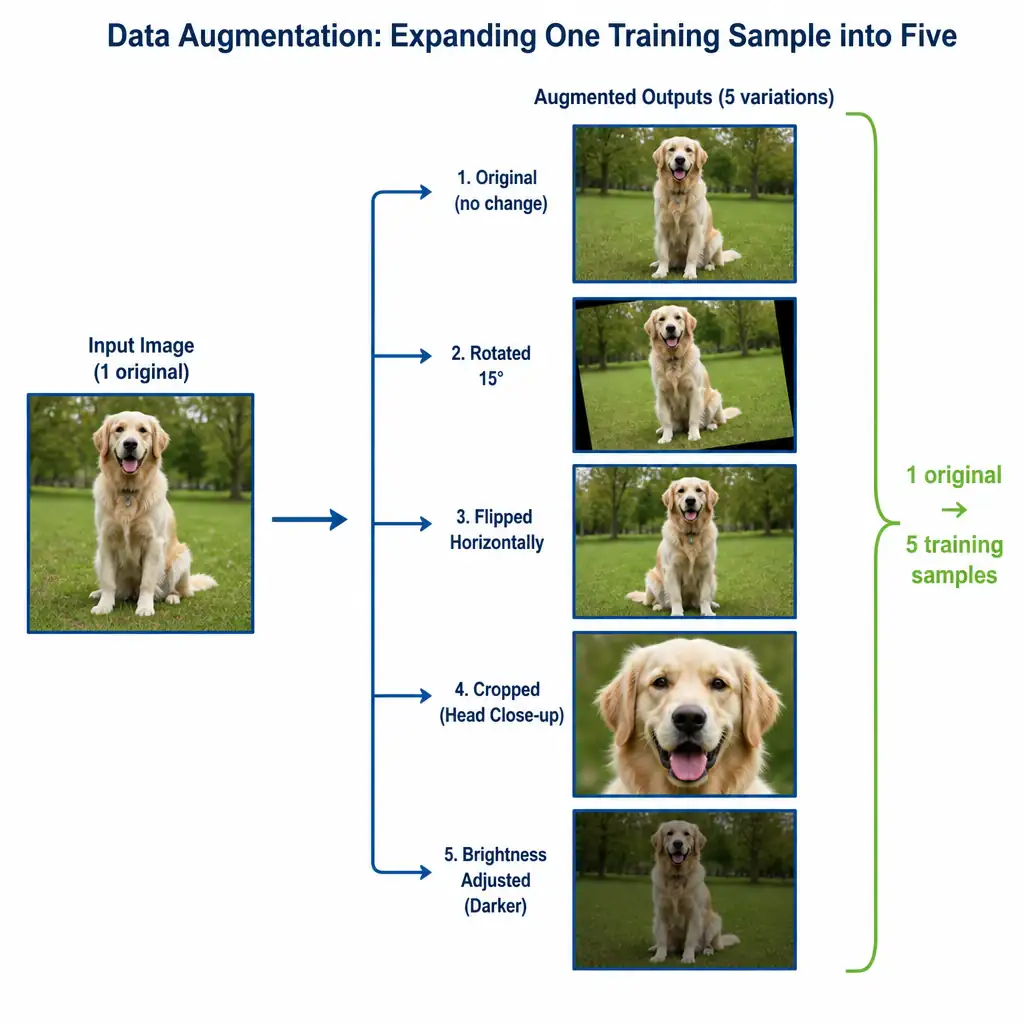
You're training a model to recognize cats, but all your training photos show cats sitting perfectly upright. If your model sees a cat lying on its side, it might completely freeze up. Data augmentation is the fix: you take existing images and create modified copies with rotations, flips, crops, and lighting changes, which expands your training set and stops overfitting.
Full Explanation
In computer vision, deep learning models like convolutional neural networks require vast amounts of diverse training data to generalize well to unseen images. However, collecting and labeling new images is often expensive and time-consuming. Data augmentation is a technique used to artificially expand the training dataset by creating modified versions of existing images. This is accomplished by applying various geometric and photometric transformations to the original images, such as random rotations, horizontal and vertical flips, translations, scaling, cropping, shearing, and color/brightness jittering. By training the network on these variations, data augmentation teaches the model to be invariant to these transformations. For instance, a horizontal flip teaches the model that an object, such as a car, is still the same object regardless of the direction it is facing. This effectively reduces overfitting and improves the model's robustness and generalization capabilities when deployed in real-world scenarios where camera angles and lighting conditions vary. Let's look at why the other choices are incorrect: The choice about compressing and downsampling images describes image compression or downsampling, which reduces resolution but does not increase dataset diversity. The choice about identifying and purging corrupted, blurry, or duplicate images refers to data cleaning or deduplication, which focuses on removing unwanted data rather than generating variations. The choice about scaling pixel intensity values to a range between zero and one describes pixel normalization or standardization, which is a scaling preprocessing step used to ensure numerical stability during training, not data augmentation. Therefore, the correct answer is the statement describing artificial expansion of the dataset through random image modifications.