
An NLP developer is designing a text cleaning pipeline and must decide between using stemming or lemmatization to normalize word variations. What is the fundamental difference between these two techniques?
Select an answer to reveal the explanation.
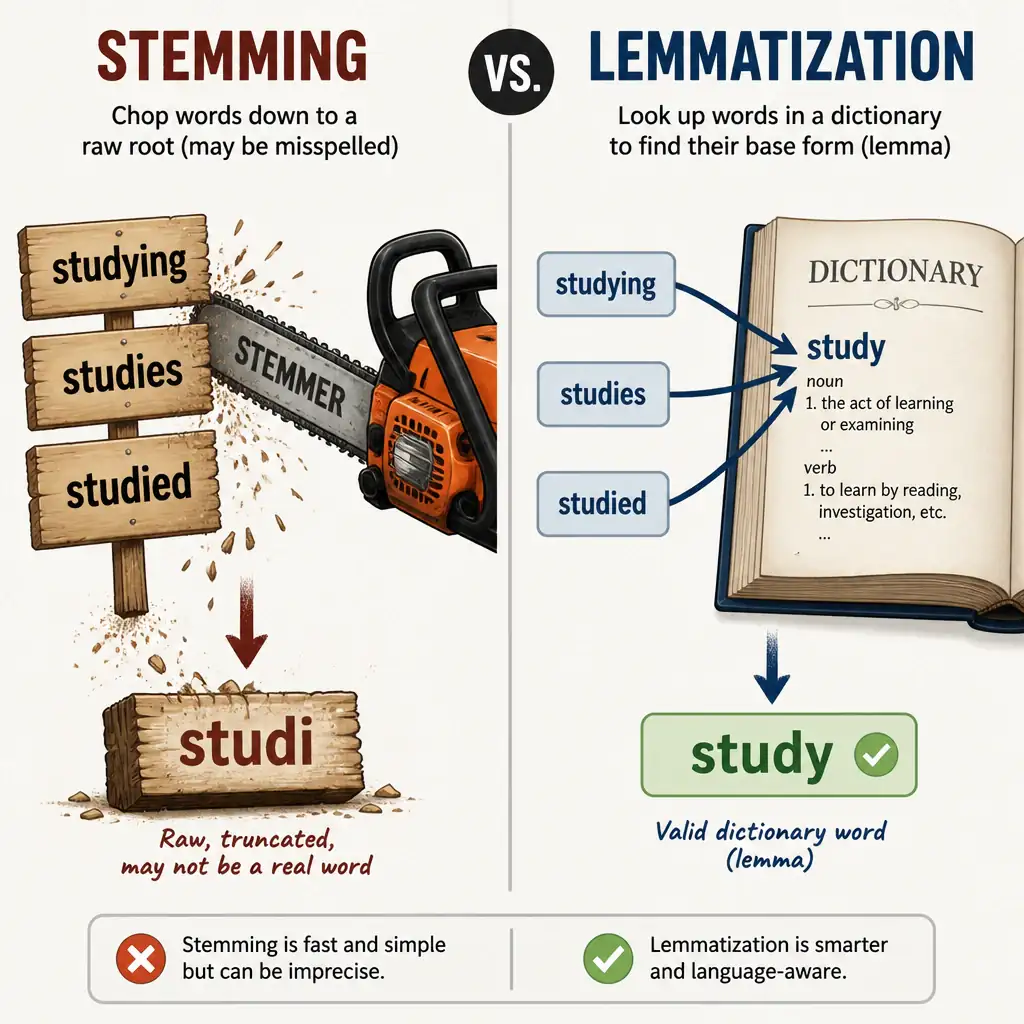
Short Explanation
Here's the deal: you use stemming when you want fast, crude suffix chopping, even if it leaves you with non-dictionary roots. You use lemmatization when you want morphological analysis and dictionary lookups to return the actual root. Stemming is fast but rough; lemmatization is slower but grammatically accurate.
Full Explanation
In natural language processing (NLP), both stemming and lemmatization are text normalization techniques used to reduce words to their base or root forms. However, their underlying mechanisms and outputs differ significantly. Stemming is a heuristic, rule-based approach that strips characters from the ends of words (such as suffixes like '-ing', '-ed', '-s') without considering grammatical context. Algorithms like the Porter Stemmer use predefined rules to truncate words. Because it is purely algorithmic character-chopping, stemming is computationally very fast, but it often results in stems that are not actual dictionary words (e.g., 'community' becomes 'commun', or 'universe' and 'university' both reduce to 'univers'). Lemmatization, by contrast, performs a full morphological analysis of words by referencing a vocabulary (dictionary) and considering the word's part of speech within the sentence. For example, running 'better' through a lemmatizer returns 'good', whereas a stemmer would likely leave it unchanged or chop it incorrectly. Similarly, 'was' lemmatizes to 'be'. Lemmatization ensures that the returned base form (the lemma) is always a valid dictionary word. The correct description is the one that says stemming applies crude, rule-based heuristics to slice off suffixes, which can result in non-dictionary root words, while lemmatization uses morphological analysis and dictionaries to reduce words to their actual linguistic root. The reversed-definition description is incorrect because it falsely attributes dictionary lookups and grammatical analysis to stemming and heuristic prefix chopping to lemmatization. The description that calls lemmatization a fast, computationally inexpensive heuristic approach and stemming a complex deep learning model is incorrect because neither technique is a deep learning model; they are algorithmic preprocessing steps, and lemmatization is the one that is more computationally demanding. The description that says stemming is used exclusively to normalize action verbs while lemmatization is used exclusively to normalize singular and plural nouns is incorrect because both techniques can be applied to all parts of speech (verbs, nouns, adjectives, etc.) to normalize text. Remember for the exam: stemming is crude and fast, while lemmatization is smart and grammatically accurate.