
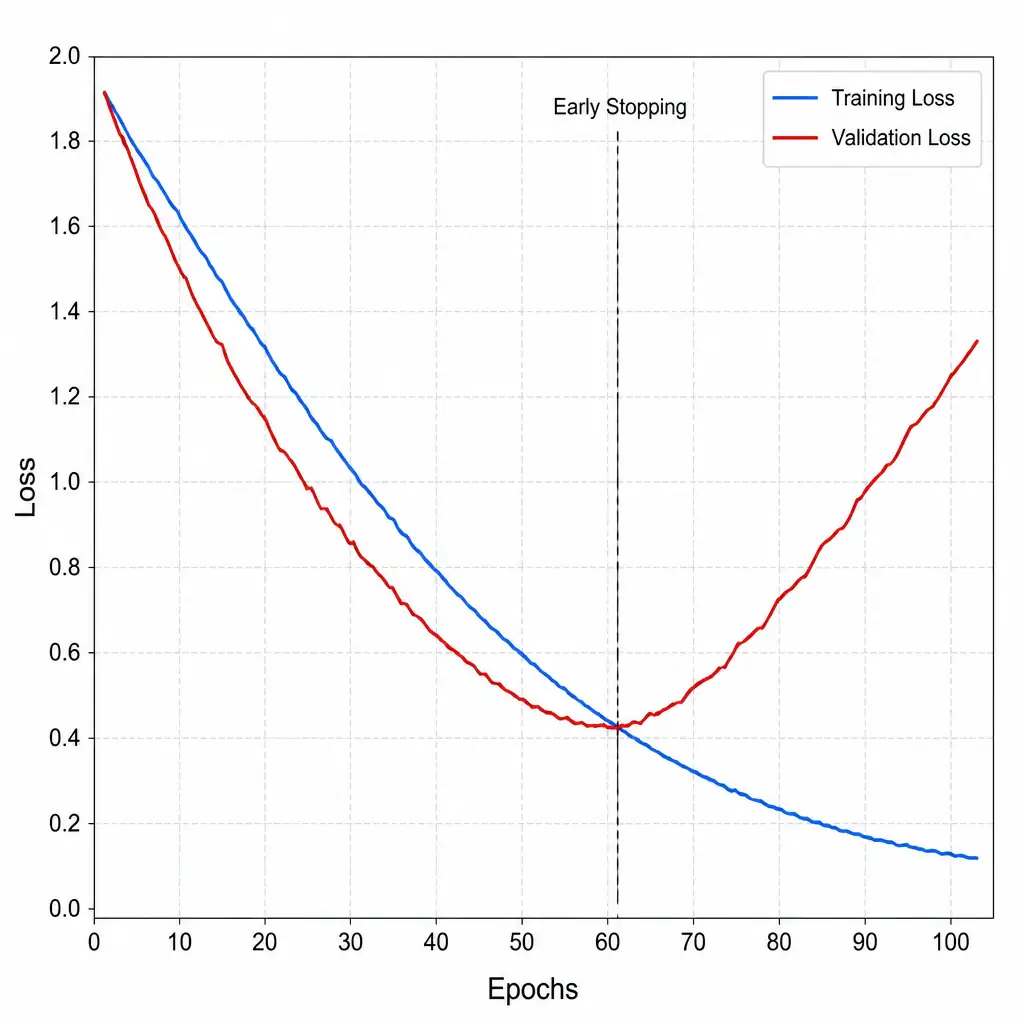
While training a deep neural network, you observe that the training loss continuously decreases, but the validation loss begins to rise after a certain epoch. Which technique should you implement to resolve this issue?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal: when training loss keeps dropping but validation loss starts climbing, your model's overfitting. You should use early stopping: watch validation loss, halt training when it stops improving, and restore the best weights. That saves time and gives you a better model.
Full Explanation
The divergence of training loss (decreasing) and validation loss (increasing) is a hallmark symptom of overfitting. The model is learning noise and patterns specific to the training set that do not generalize to unseen validation data. Early stopping is a regularization technique that monitors the model's loss or accuracy on an independent validation set during training. When validation performance stops improving and begins to degrade (typically measured over a window of epochs called 'patience'), the training process is programmatically terminated. The weights from the epoch that achieved the lowest validation loss are then restored.
The correct technique is early stopping because it halts the training loop at the point of optimal generalization before overfitting deteriorates model utility. Increasing the learning rate is incorrect because it will cause weight updates to take larger steps, which usually increases instability and does not address overfitting. Expanding the batch size is incorrect because it changes the noise profile of gradient updates and alters training throughput, but it does not act as a regularizer or stop training when validation loss degrades. Randomly initializing weights is incorrect because weight initialization occurs only once before the training loop starts and cannot be applied dynamically to address overfitting observed mid-training.