
When training a machine learning model, what is the primary role that the loss function plays in the optimization process?
Select an answer to reveal the explanation.
Short Explanation
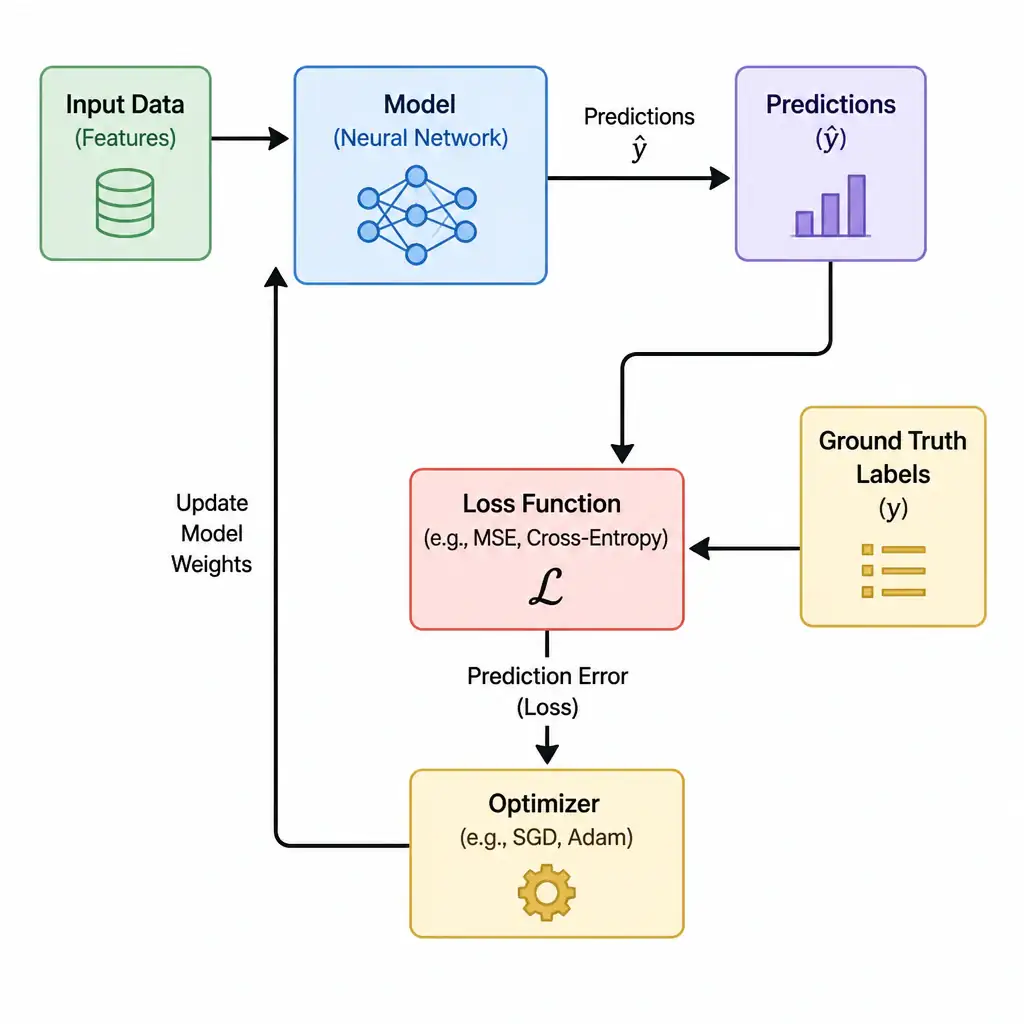
Think of a loss function like rumble strips on the side of the highway. When your model drifts off course, it gives you a single number showing how far its predictions are from the actual target values, so the optimizer can adjust the weights. Without that error signal, you can't steer the model back on track.
Full Explanation
The correct answer is the choice that calculates the discrepancy between the model's predictions and the actual target values. The loss function, also referred to as the cost, objective, or error function, is a mathematical algorithm that serves as the foundation of the optimization process in machine learning model training. During training, the model takes input data, passes it through its layers during forward propagation, and produces a prediction. The loss function then calculates a scalar value that quantifies the discrepancy between this prediction and the ground-truth label.
The optimizer, such as Stochastic Gradient Descent, Adam, or RMSprop, calculates the mathematical gradients of this loss function with respect to the model's parameters, including weights and biases. These gradients are backpropagated through the network, determining the exact adjustments needed to minimize the error in subsequent iterations. Without a loss function, the model has no way to evaluate its performance or guide weight updates, rendering optimization impossible.
The choice that identifies and removes highly correlated input features is incorrect because that is a feature-selection and dimensionality-reduction preprocessing step. Those tasks are performed before training begins to simplify the input space, rather than during training to guide parameter updates.
The choice that computes human-readable evaluation metrics like precision and recall is incorrect because evaluation metrics, such as precision, recall, accuracy, and F1-score, are calculated after training to evaluate the model's overall performance for humans. While useful, they are frequently non-differentiable, meaning their mathematical derivatives cannot be computed, making them unsuitable for direct optimization.
The choice that prevents the model from overfitting by penalizing high weights is incorrect because preventing overfitting by penalizing complex model structures is the specific job of regularization techniques, such as L1/L2 weight decay or dropout. Although regularization penalties can be appended to the loss function to create a combined objective, the primary purpose of the loss function itself is to quantify prediction error.