
Once a machine learning model is trained and validated, it is often deployed behind a RESTful API. What is the primary purpose of this approach during the model serving phase?
Select an answer to reveal the explanation.
Short Explanation
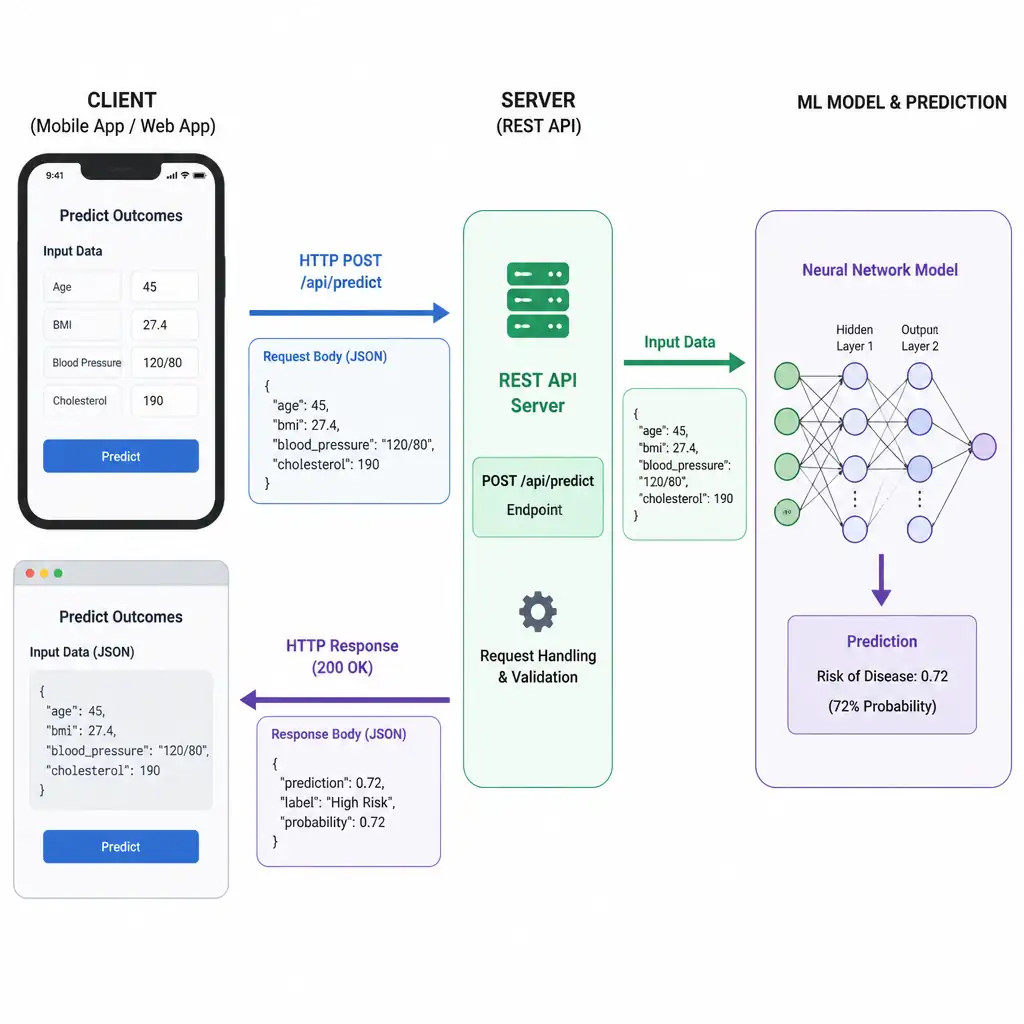
When your team builds a model and your web or mobile apps need predictions, you put the model behind a RESTful API. The app sends an HTTP request with the input data, the server runs the model, and the prediction comes right back. That's how you serve real-time inference without stuffing the model into every client.
Full Explanation
Deploying a machine learning model behind a RESTful (Representational State Transfer) API is a standard practice for model serving and inference. The RESTful API acts as an interface between the deployed model and client applications, such as web browsers, mobile apps, or other microservices.
When a client needs a prediction, it sends an HTTP/HTTPS request, typically a POST request carrying a JSON payload of features, to the API endpoint. The model serving framework receives the request, parses the input data, passes it through the model to perform forward-pass inference, and returns the output predictions back to the client in the HTTP response. This decouples the model's complex runtime environment, such as Python, TensorFlow, or PyTorch, from the client applications, which can be written in any programming language that supports standard HTTP communication.
The correct purpose is enabling external client applications to request real-time inference and receive predictions over HTTP network protocols.
The other choices are incorrect: - Running distributed pipeline steps for raw data collection and feature extraction is not the primary purpose of a serving API. Data collection and feature engineering belong to data preparation, although lightweight preprocessing can be performed inside the serving container before inference. - Acting as a code repository that tracks changes to model weight files and source files is not what a serving API does. Model version control is handled by model registries or Git. - Executing training optimization loops and updating model weights using backpropagation is not the role of a serving API. Training is a resource-intensive process executed during development, whereas a serving API is strictly for running inference on already-trained models.
For the exam, associate RESTful APIs with model serving and facilitating real-time inference over HTTP.