
In Natural Language Processing (NLP), how is a word represented when using the one-hot encoding technique?
Select an answer to reveal the explanation.
Short Explanation
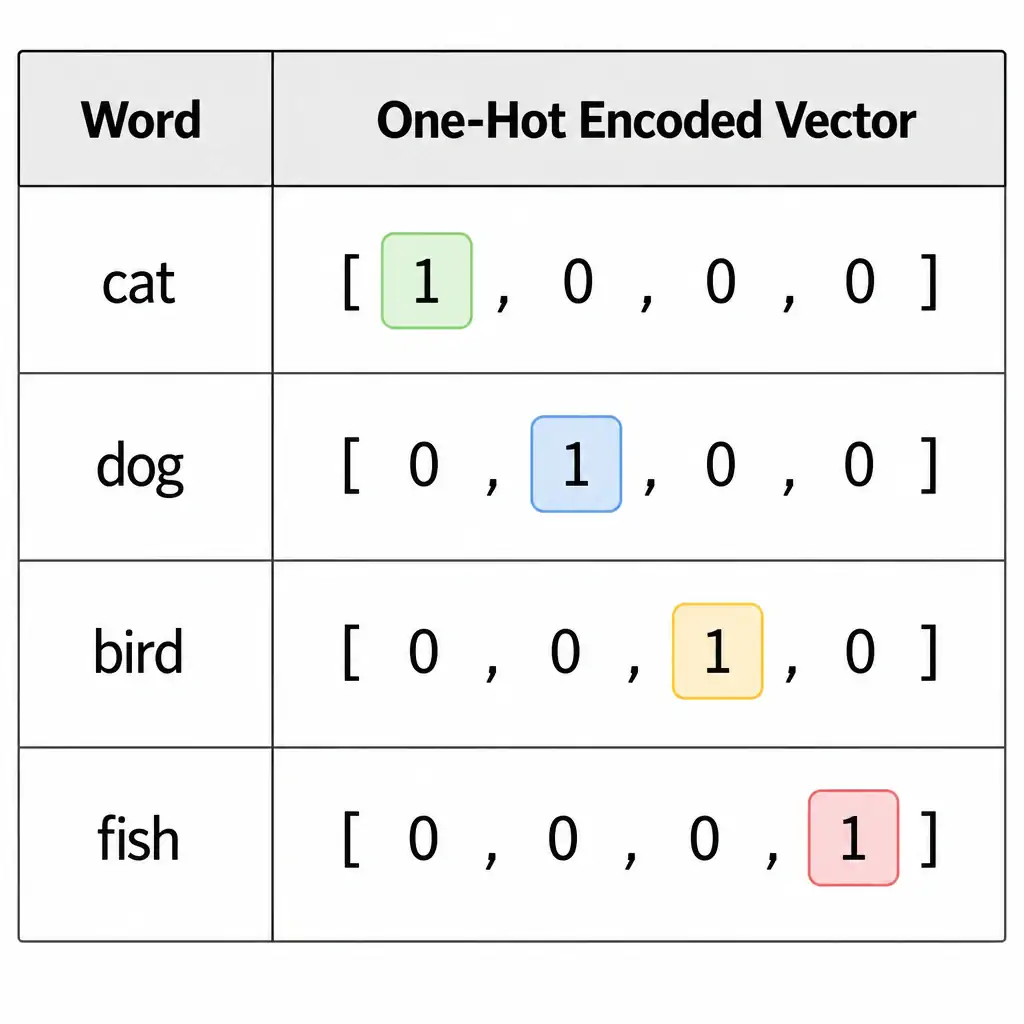
Think of it like this: one-hot encoding gives every word its own slot in a vector. You'll set the word's slot to 1 and every other slot to 0, so it's high-dimensional and sparse.
Full Explanation
One-hot encoding is a fundamental vectorization technique used to convert categorical variables, such as words in a vocabulary, into a numerical format that machine learning algorithms can process. In a one-hot representation, a vocabulary is established, and each unique word in the vocabulary is assigned a unique index. Each word is then represented as a binary vector whose length equals the vocabulary size. In this vector, the element at the word's assigned index is set to 1, while all other elements are set to 0. This creates a high-dimensional and highly sparse vector. While simple to implement, one-hot encoding has significant limitations in NLP: it does not capture semantic similarity between words, because the dot product of any two distinct one-hot vectors is always 0, and the vector size grows linearly with the vocabulary, leading to high memory consumption. The low-dimensional, dense vector of real numbers that captures semantic relationships between words describes dense word embeddings, such as Word2Vec, GloVe, or FastText, which represent words in a low-dimensional space, for example 300 dimensions, where real-valued numbers capture semantic and syntactic relationships. The single integer indicating the word's frequency of occurrence across the entire document corpus describes term frequency or integer mapping, not one-hot encoding. The character-level sequence of ASCII values that represents the word's phonetic pronunciation is incorrect because it refers to character encoding rather than categorical word vectorization. For the exam, remember that one-hot encoding produces sparse vectors where a single element is 1 and all others are 0.