
During the data preprocessing stage, a machine learning engineer discovers that several independent variables in the dataset are highly correlated with one another. What is a standard engineering technique used to address this issue?
Select an answer to reveal the explanation.
Short Explanation
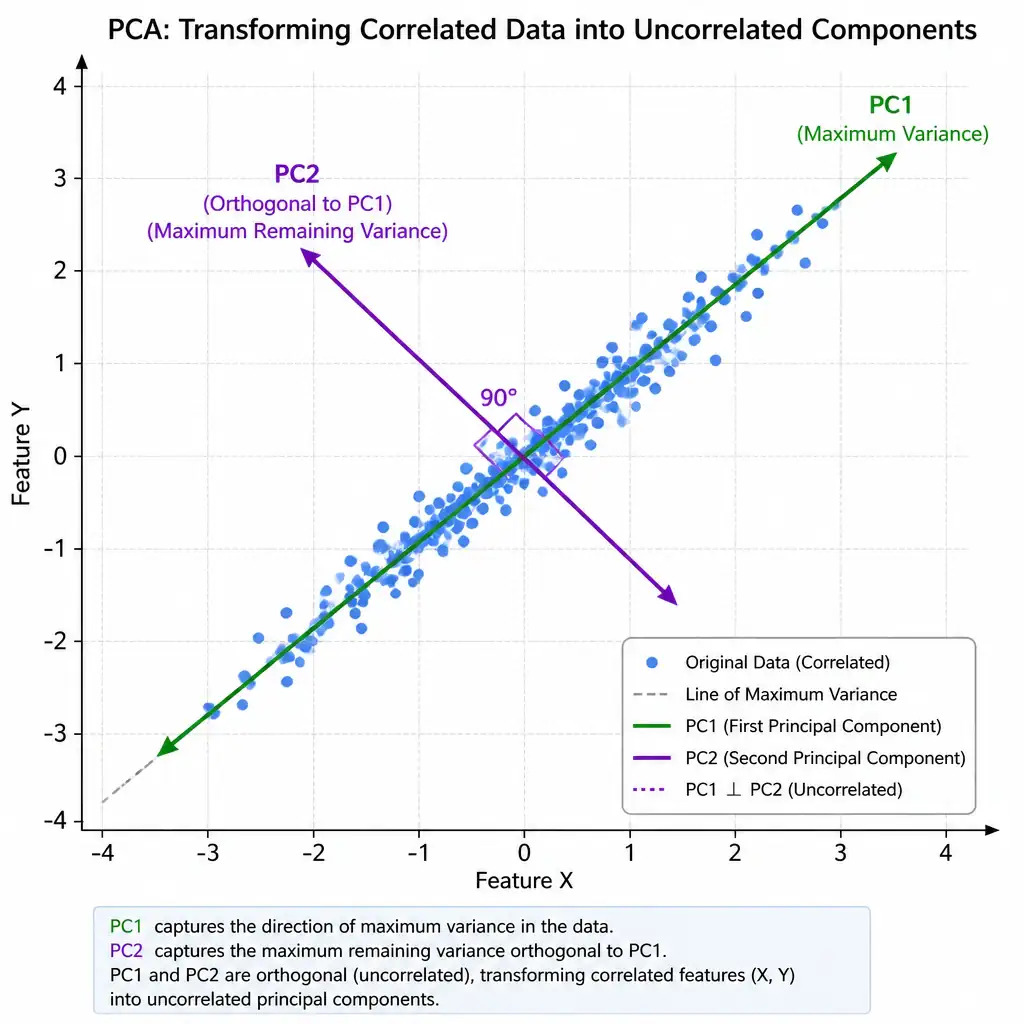
Here's the deal: highly correlated features are redundant and can make your model unstable. You can use principal component analysis to turn them into a smaller set of uncorrelated components while keeping the most important information.
Full Explanation
In machine learning, high correlation between input features is known as multicollinearity. Multicollinearity can cause numerical instability, especially in linear models, because it makes it difficult to estimate the individual relationship between each independent variable and the target variable.
A standard technique to address this is Principal Component Analysis, which is an unsupervised dimensionality reduction method. It projects the original features onto a lower-dimensional space. It does this by finding new directions, or eigenvectors, of maximum variance in the data, which are orthogonal to one another. Because these new features, called principal components, are orthogonal, they are mathematically uncorrelated. This eliminates multicollinearity while retaining most of the variance, or information, present in the original dataset.
Now check the distractors: - The option that suggests increasing the number of training samples is incorrect because adding more samples will not resolve high correlation between features if the underlying relationship is a physical or logical rule, such as height in inches and height in centimeters. - The option that suggests eliminating the target label columns is incorrect because dropping the target label converts a supervised learning task into an unsupervised clustering task, which does not solve the original target task. - The option that suggests implementing L1 regularization on the final output predictions after inference is incorrect because L1 regularization is applied to model weights during the training optimization process to penalize and zero out weights of less important features, not to the final predictions after inference has finished.
For the exam, associate principal component analysis with dimensionality reduction and the creation of uncorrelated features, or components, from correlated ones.