
You are building a classification model to categorize incoming support tickets as either "Urgent" or "Routine" based on the text description. Which supervised learning algorithm is a classic, highly effective baseline choice for this type of text classification task?
Select an answer to reveal the explanation.
Short Explanation
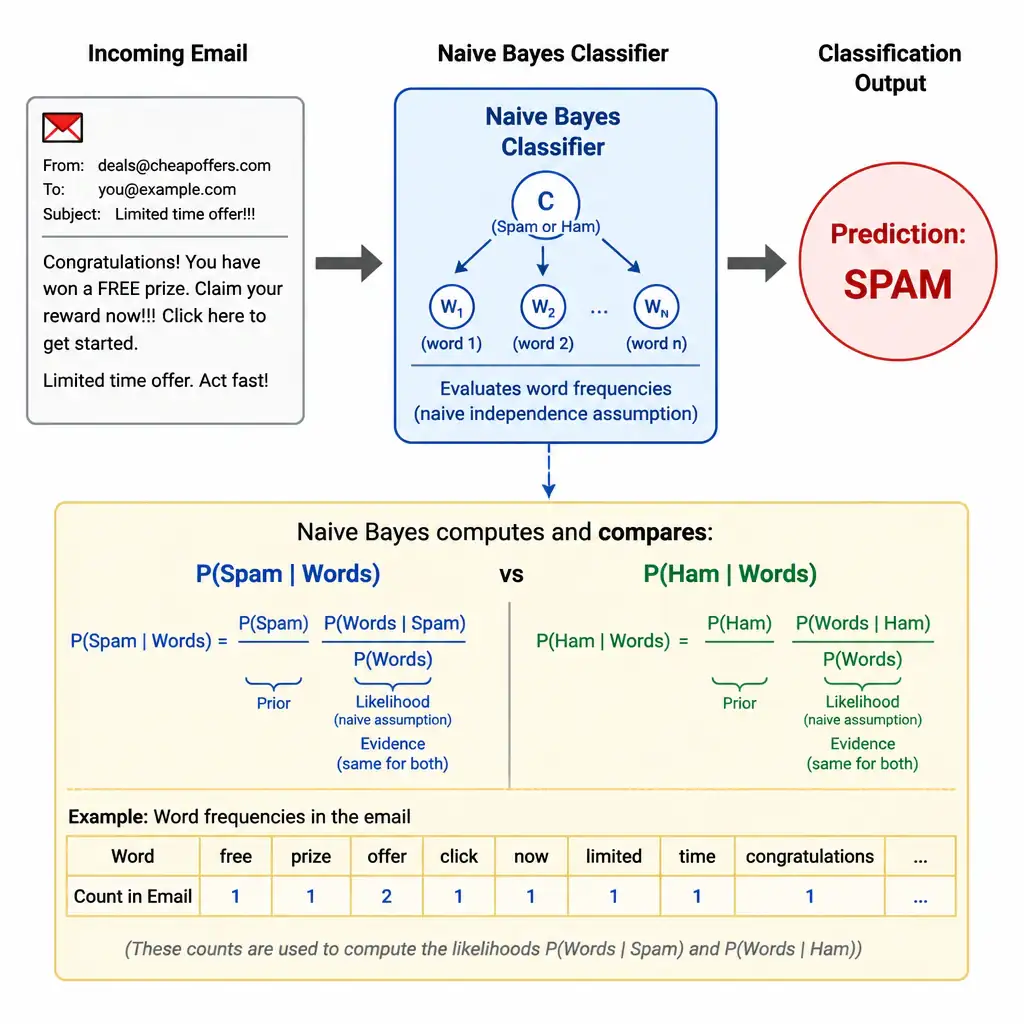
Here's the deal: when you're classifying text, you're really working with word probabilities. Naive Bayes is the classic supervised baseline because it uses Bayes' theorem to score classes from word frequencies. K-Means and DBSCAN are unsupervised clustering, and Principal Component Analysis just shrinks dimensions.
Full Explanation
For text classification tasks such as spam filtering or sentiment categorization, the Naive Bayes classifier is a highly effective and computationally efficient supervised learning algorithm.
Naive Bayes is based on Bayes' Theorem, which calculates the probability of a hypothesis (in this case, a class label like 'Urgent' or 'Routine') given prior knowledge (the words present in the document). The algorithm is called 'naive' because it operates under the assumption of conditional independence: it assumes that the presence of a particular feature (word) in a class is completely unrelated to the presence of any other feature, given the class label. Although this assumption rarely holds true in natural language (where word order and context matter), Naive Bayes performs surprisingly well in practice. It requires relatively little training data to estimate the necessary parameters and is highly scalable to large vocabularies.
The Principal Component Analysis approach is incorrect because it is an unsupervised dimensionality reduction technique. It is used to project high-dimensional data into a lower-dimensional space to simplify analysis or speed up other models, not to perform classification.
The K-Means approach is incorrect because it is an unsupervised clustering algorithm. It groups data points into a pre-specified number of clusters based on distance metrics without using labels, meaning it cannot be trained to predict predefined categories like 'Urgent' or 'Routine'.
The DBSCAN approach is incorrect because it is also an unsupervised clustering algorithm. It groups data points based on density (spatial proximity) and is used to discover clusters of arbitrary shapes and identify outliers, not for supervised classification.