
An organization is setting up an automated CI/CD pipeline for machine learning. Where should the pipeline upload the built Docker images containing the models to make them available for deployment?
Select an answer to reveal the explanation.
Short Explanation
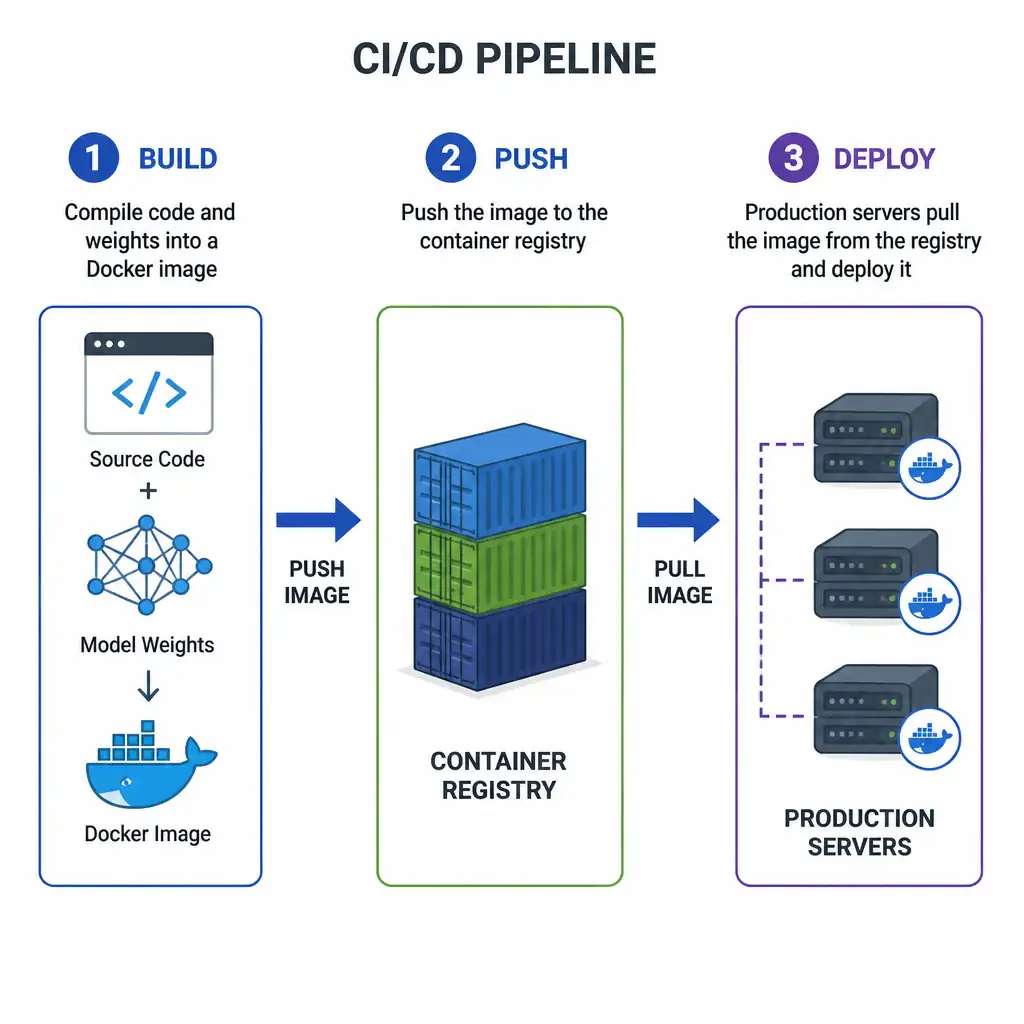
Check this out: once you've built your Docker image with your model inside, you need a container registry so deployment servers can grab the exact image version. Think of a container registry like an app store for your custom Docker containers, with services like Amazon ECR or Docker Hub storing and distributing those images securely. It doesn't store your raw database text or training data—it stores the executable images.
Full Explanation
In an MLOps pipeline, a container registry is a dedicated service designed to store, manage, and distribute container images, most commonly Docker images. After a model is trained and packaged along with its application code and dependencies into a container image, that image must be hosted in a location that is highly accessible to the orchestration and deployment infrastructure, such as Kubernetes, Amazon ECS, or Google Cloud Run.
The container registry serves as the intermediary in this process: - Centralized storage: it hosts the built images and keeps track of image tags and immutable digests. - Access control and security: it manages permissions, ensuring only authorized deployment pipelines or production clusters can pull specific images. Many registries also run automated vulnerability scans on the images. - Distribution: it is optimized for high-throughput distribution, allowing deployment servers to pull down large image layers quickly to scale instances horizontally.
The relational SQL database designed to store real-time model predictions and user inputs is incorrect because SQL databases are designed for relational tables and transactional query data, not for storing large binary container images.
The version control repository like GitHub, optimized for hosting plain-text source code, is incorrect because git repositories are designed for tracking changes in source code text files. Storing large compiled binary container images in git leads to performance issues and is not supported by standard workflows.
The data lake house used to store unstructured raw training datasets is incorrect because data lakes and lake houses are specialized for storing raw, semi-structured, or unstructured datasets, like CSVs, Parquet, or JSON, for data engineering and model training, not for application runtimes.