
A machine learning engineer decides to package a newly trained computer vision model inside a Docker container before deploying it to production. What is the primary benefit of using containerization in this deployment strategy?
Select an answer to reveal the explanation.
Short Explanation
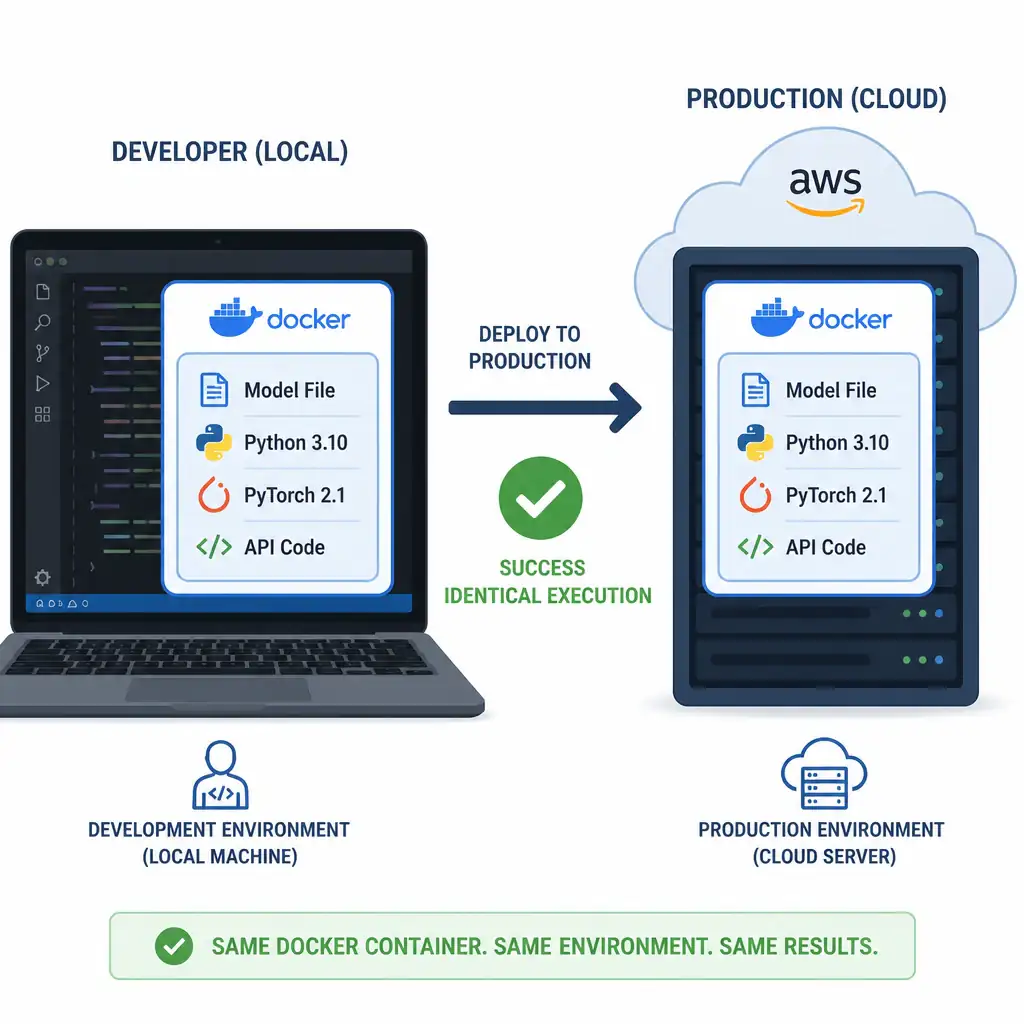
Check this out: you get consistency because Docker wraps the model, code, and exact dependency libraries into one package, so it runs the same on your laptop, a server, or the cloud. It won't make the model smarter or train faster, but it kills the 'worked on my machine' mess.
Full Explanation
The primary advantage of containerizing machine learning models using Docker is the guarantee of environment consistency and reproducibility, often referred to as solving dependency hell or the 'works on my machine' issue.
In modern machine learning, models rely on a deep stack of software dependencies, including specific versions of programming languages (for example, Python 3.10), machine learning frameworks (for example, PyTorch or TensorFlow), utility libraries (for example, NumPy or Pandas), and system-level libraries (for example, CUDA drivers for GPU acceleration). Differences in any of these components between the development environment and the production server can lead to runtime crashes, silent performance degradation, or subtle bugs.
Docker addresses this by creating a lightweight, standalone, executable package called a container. The container includes everything needed to run the application: the model weights, application code, runtime environment, system tools, and libraries. This ensures that the container behaves identically whether it is running on a local development laptop, an on-premises test server, or a cloud provider's managed Kubernetes cluster. This consistency simplifies the CI/CD pipeline, reduces deployment risk, and facilitates horizontal scaling.
The claim that containerization optimizes the model's internal weights and architecture to increase classification accuracy is incorrect because containerization is a deployment and packaging tool. It does not alter the model's math, weights, or architecture, and therefore has no impact on model accuracy.
The claim that containerization speeds up the distributed training phase by parallelizing matrix operations on local GPUs is incorrect because Docker is typically used for packaging and serving models, and while containers can be used in training pipelines, they do not inherently speed up the training process or parallelize mathematical operations; that is managed by the training framework and hardware.
The claim that containerization eliminates the need for any underlying operating system or hardware virtualization is incorrect because containers still run on top of a shared host operating system kernel and require physical hardware resources; they do not eliminate the need for them.