
Imagine you are deploying a machine learning model to detect credit card fraud. Since missed fraudulent transactions (false negatives) cost the company millions in direct losses, the business demands a model that catches as many fraud cases as possible. Which evaluation metric should you prioritize to minimize these costly misses?
Select an answer to reveal the explanation.
Short Explanation
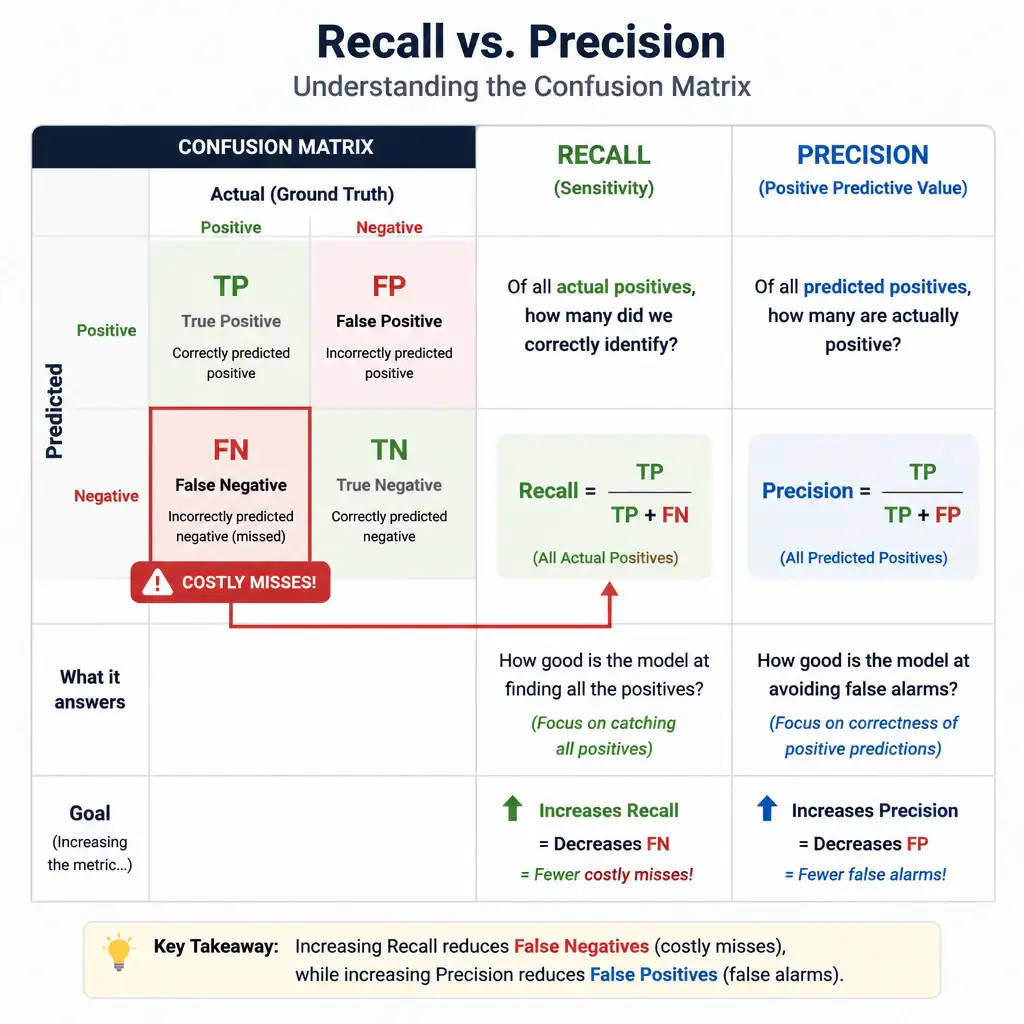
Here's the deal: if a fraudulent transaction slips past your system, that's a false negative, and that costs money. You want to catch as many fraud cases as possible, even if you occasionally flag a legitimate transaction. That is exactly what recall measures.
Full Explanation
In classification tasks, the choice of evaluation metric is driven by the business consequences of different types of errors: false positives and false negatives. In a fraud detection scenario, a false negative occurs when a transaction is fraudulent, but the model classifies it as normal. This results in direct financial loss and security breaches.
Recall, also known as sensitivity or the true positive rate, is mathematically defined as: Recall = True Positives / (True Positives + False Negatives). Because false negatives are in the denominator, maximizing recall directly minimizes false negatives. High-recall models capture most of the actual fraudulent transactions, ensuring they do not go unnoticed.
The precision-focused answer, which aims to ensure that every transaction flagged as fraud is indeed fraudulent, measures the proportion of flagged transactions that are actually fraudulent: Precision = True Positives / (True Positives + False Positives). Optimizing for precision minimizes false positives, which are cases where a normal transaction is flagged as fraud. While high precision prevents customer frustration by reducing blocked legitimate cards, models optimized solely for precision will be very conservative, missing many actual fraud cases because they only flag transactions they are extremely certain are fraudulent.
The accuracy-focused answer, which aims to maximize total correct predictions across both normal and fraudulent transactions, is the ratio of correct predictions to total predictions. In fraud detection, the dataset is highly imbalanced, for example 99.9% of transactions are legitimate. In fraud detection, a naive model that predicts normal for every transaction would achieve 99.9% accuracy but catch 0% of the fraud, making accuracy a misleading and dangerous metric here.
The F1-score-focused answer, which incorrectly prioritizes a perfectly balanced weight between training time and inference speed, is the harmonic mean of precision and recall. While it is a good metric to balance both concerns, it does not prioritize minimizing false negatives above all else. Additionally, the definition in the F1-score-focused answer incorrectly relates the F1-score to training time and inference speed, which are operational performance metrics, not classification metrics.