
When planning a machine learning project, a team must choose between supervised and unsupervised learning approaches. What is the fundamental difference in how these two paradigms utilize data?
Select an answer to reveal the explanation.
Short Explanation
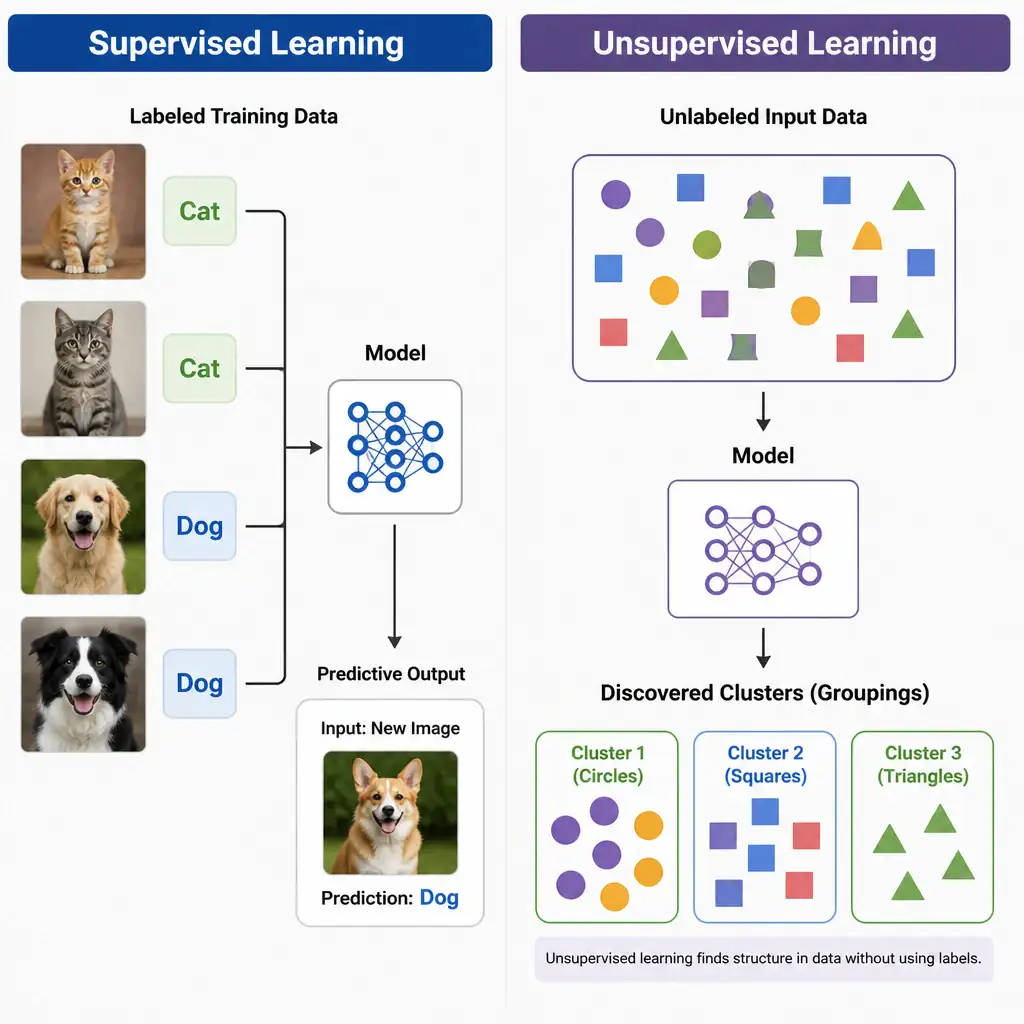
Here's the deal: supervised learning has the answers already written in, so you feed the model inputs and labels and it learns the mapping. Unsupervised learning has no teacher and no labels; it just looks at raw data and figures out what groups together. That label/no-label difference is bedrock for your exam and career.
Full Explanation
The core distinction between supervised and unsupervised machine learning lies in the structure of the training dataset, specifically the presence or absence of target labels, often referred to as ground truth. The correct statement is the one saying supervised learning trains on data that includes ground-truth output labels to predict target variables, while unsupervised learning analyzes unlabeled data to discover hidden patterns.
In supervised learning, the training dataset consists of input-output pairs. Each training instance features a set of input characteristics, or independent variables, and a corresponding label or target value, or dependent variable. The goal of the algorithm is to learn a mapping function that can accurately predict the output label for new, unseen input data. Supervised learning is broadly categorized into classification, which predicts discrete class labels such as spam or not spam, and regression, which predicts continuous numerical values such as housing prices.
In contrast, unsupervised learning deals with datasets that do not contain pre-labeled output targets. The algorithm is given only the input features and is tasked with exploring the data to identify intrinsic structures, relationships, or patterns. Common tasks in unsupervised learning include clustering, which groups similar data points together such as customer segmentation; dimensionality reduction, which simplifies data representation while retaining key information; and association rule learning, which identifies relations between variables such as market basket analysis.
The statement claiming supervised learning focuses exclusively on continuous numerical prediction while unsupervised learning is used solely for categorical classification is incorrect because supervised learning is used for both classification, which is discrete, and regression, which is continuous, not just regression. Furthermore, unsupervised learning does not perform classification, because classification by definition requires pre-defined target labels.
The statement claiming supervised learning relies on the algorithm autonomously generating its own feedback loop while unsupervised learning requires manual labeling for every training iteration is incorrect because unsupervised learning specifically operates on unlabeled data; it does not utilize labeled data or require manual labeling iterations. Supervised learning's defining trait is the use of labeled training targets, not autonomous feedback generation.
The statement claiming supervised learning processes unlabeled raw datasets to build association rules while unsupervised learning uses labeled targets to establish boundary thresholds is incorrect because it reverses the definitions. Supervised learning requires labeled targets, while unsupervised learning works with unlabeled datasets and may discover association rules. Understanding this label/no-label distinction is bedrock for the exam and career.