
A developer is using a pre-trained Word2Vec model for a downstream text classification task. What is the fundamental property of the static word embeddings generated by this model?
Select an answer to reveal the explanation.
Short Explanation
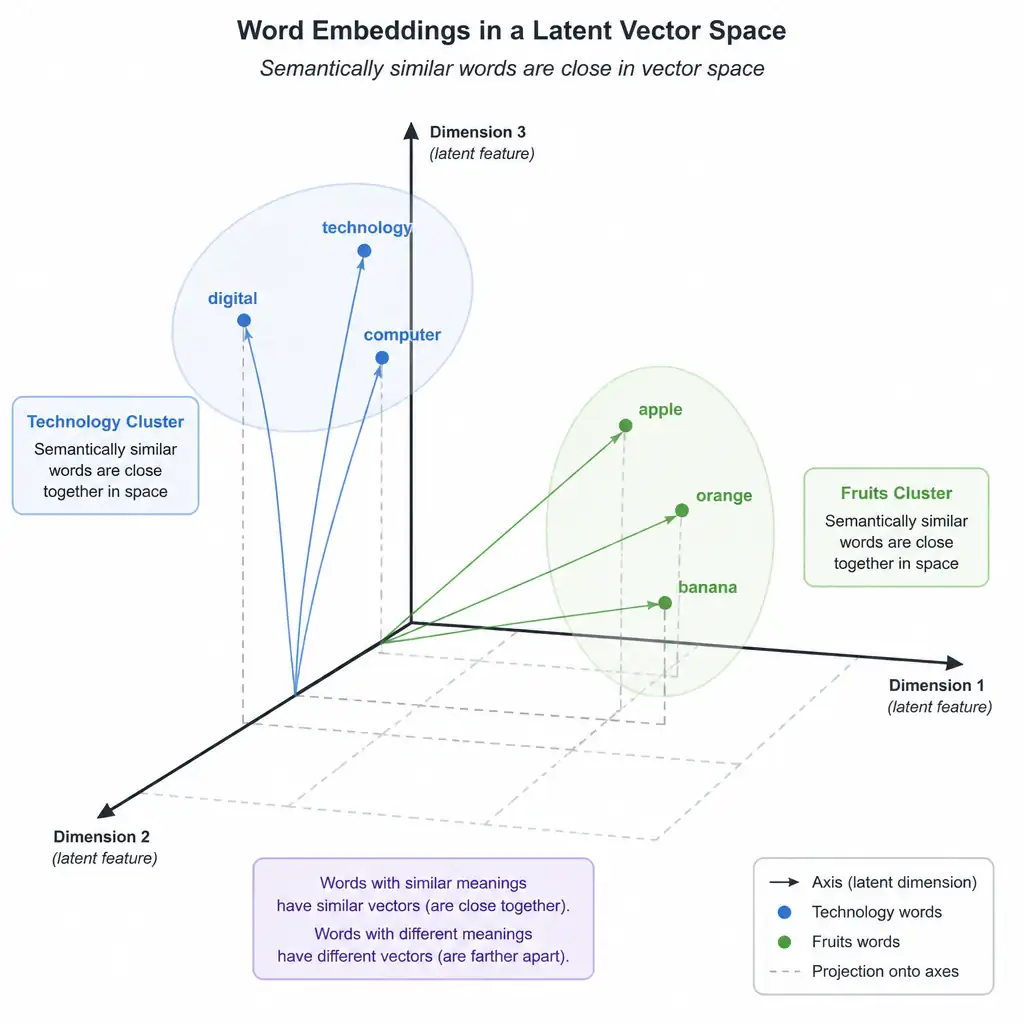
Here's the deal: Word2Vec uses the distributional hypothesis, so you can know a word by the company it keeps. If words show up in similar contexts, their vectors end up close together. It's static, so it won't change based on sentence context.
Full Explanation
The core feature of the Word2Vec model is its ability to map words into a dense vector space based on context. This is rooted in linguistics—specifically J.R. Firth's distributional hypothesis: "You shall know a word by the company it keeps." During training (via Skip-gram or CBOW), the model learns vectors by predicting a target word from its context, or predicting context words from a target word. Through this optimization, words that occur in similar linguistic contexts end up with high cosine similarity (small angles between their vector representations). This allows the model to capture semantic relationships (like synonyms or analogies like "king - man + woman = queen") and syntactic relationships (like verb tenses).
The statement that words that frequently appear in similar contexts in the training corpus will have mathematically similar vector representations is correct because it accurately describes this semantic grouping based on context.
The claim that words sharing similar prefixes or suffixes will always be mapped to adjacent coordinates is incorrect because Word2Vec treats each word as a single token and does not examine its spelling or character structure. This is a feature of subword-based models like FastText.
The claim that the vector representation of any given word changes dynamically depending on the surrounding context of the sentence is incorrect because it describes contextualized word embeddings, such as those from BERT, RoBERTa, or GPT models. Word2Vec is a static model, meaning a word has a single, fixed vector representation regardless of the sentence context in which it appears at inference time.
The claim that the model produces sparse vectors composed primarily of zero values to minimize memory usage is incorrect because word embeddings are dense vectors, where every dimension is filled with a real-valued number, unlike the sparse vectors of Bag-of-Words or One-Hot Encoding.