
In natural language processing, what is the primary architectural advantage of using FastText over standard Word2Vec for generating word representations?
Select an answer to reveal the explanation.
Short Explanation
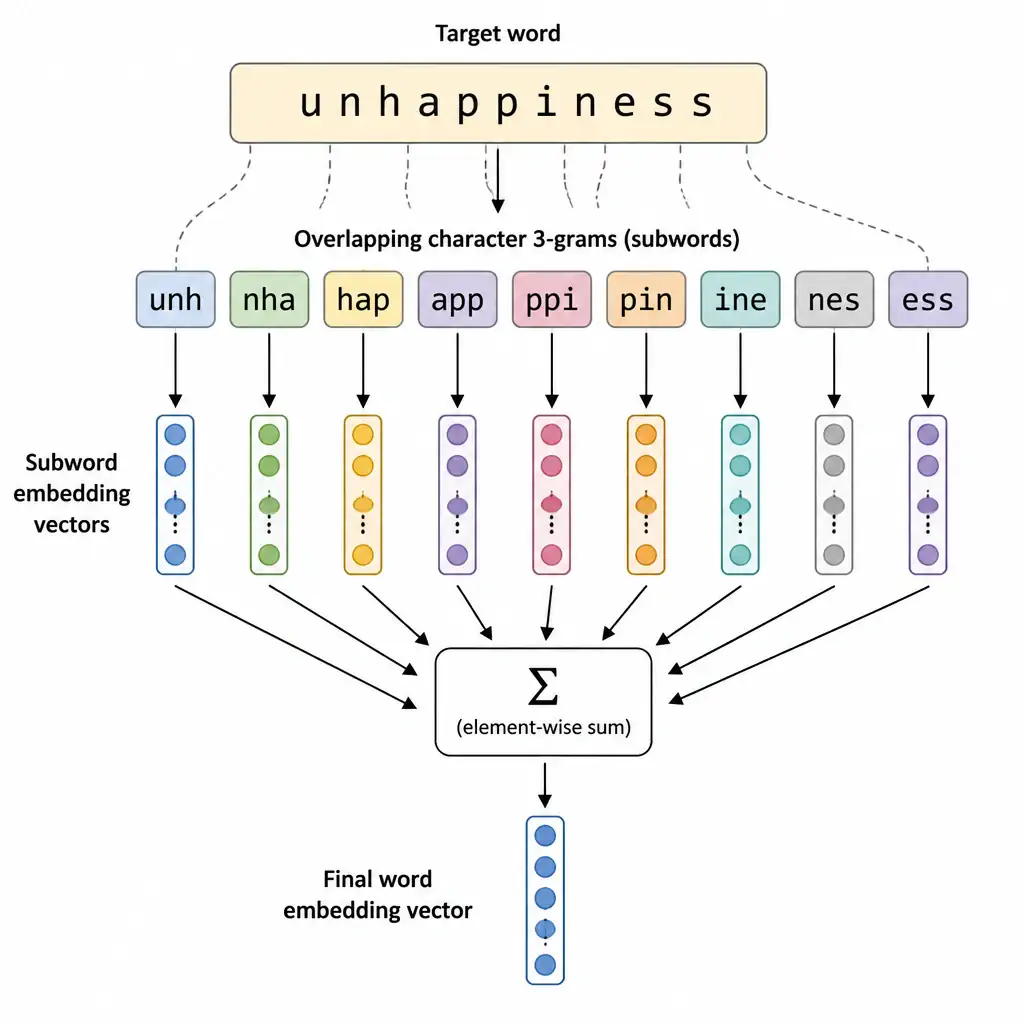
You get a reliable vector for unseen or misspelled words because FastText builds each word from character chunks instead of treating it as one indivisible token. That subword approach lets you handle out-of-vocabulary terms and spelling variations, unlike standard Word2Vec.
Full Explanation
The correct choice is the bag-of-character-n-grams approach, because FastText is an extension of the Word2Vec model designed to address its core limitation: the inability to handle out-of-vocabulary words. In standard Word2Vec (both Continuous Bag-of-Words and Skip-gram architectures), each word in the vocabulary is assigned a distinct, static vector. If a word was not present in the training corpus, the model cannot generate a vector for it during inference.
FastText overcomes this by representing each word as a sum of its character n-grams. For example, using three-character chunks, the word 'fast' is represented by '<fa', 'fas', 'ast', 'st>', where '<' and '>' denote the word boundaries. The word vector for 'fast' is the sum of the vector representations of these chunks.
This subword approach provides several key benefits: 1. Handling out-of-vocabulary words: even if a word is missing from the training vocabulary, FastText can construct a vector by combining the vectors of its constituent chunks. 2. Robustness to typos: minor misspellings, such as 'computerr' instead of 'computer', still share most of their chunks with the correct word, resulting in a similar vector. 3. Morphologically rich languages: languages like German or Finnish, which rely on compound words, are much easier to model because subwords capture prefixes and suffixes.
The deep bidirectional transformer structure claim is wrong because it describes contextual embedding models such as BERT or GPT, whereas FastText produces static embeddings rather than dynamic, context-dependent word vectors. The syntactic parsing and part-of-speech tagging claim is wrong because those are grammatical parsing and syntactic analysis tasks, not operations performed by FastText before generating sparse text matrices. The graphics-hardware and sparse-index claim is wrong because FastText is a lightweight CPU-friendly algorithm, and it outputs dense, not sparse, vectors.