
In modern Natural Language Processing (NLP), how are word embeddings (such as Word2Vec, GloVe, or FastText) typically utilized in downstream applications?
Select an answer to reveal the explanation.
Short Explanation
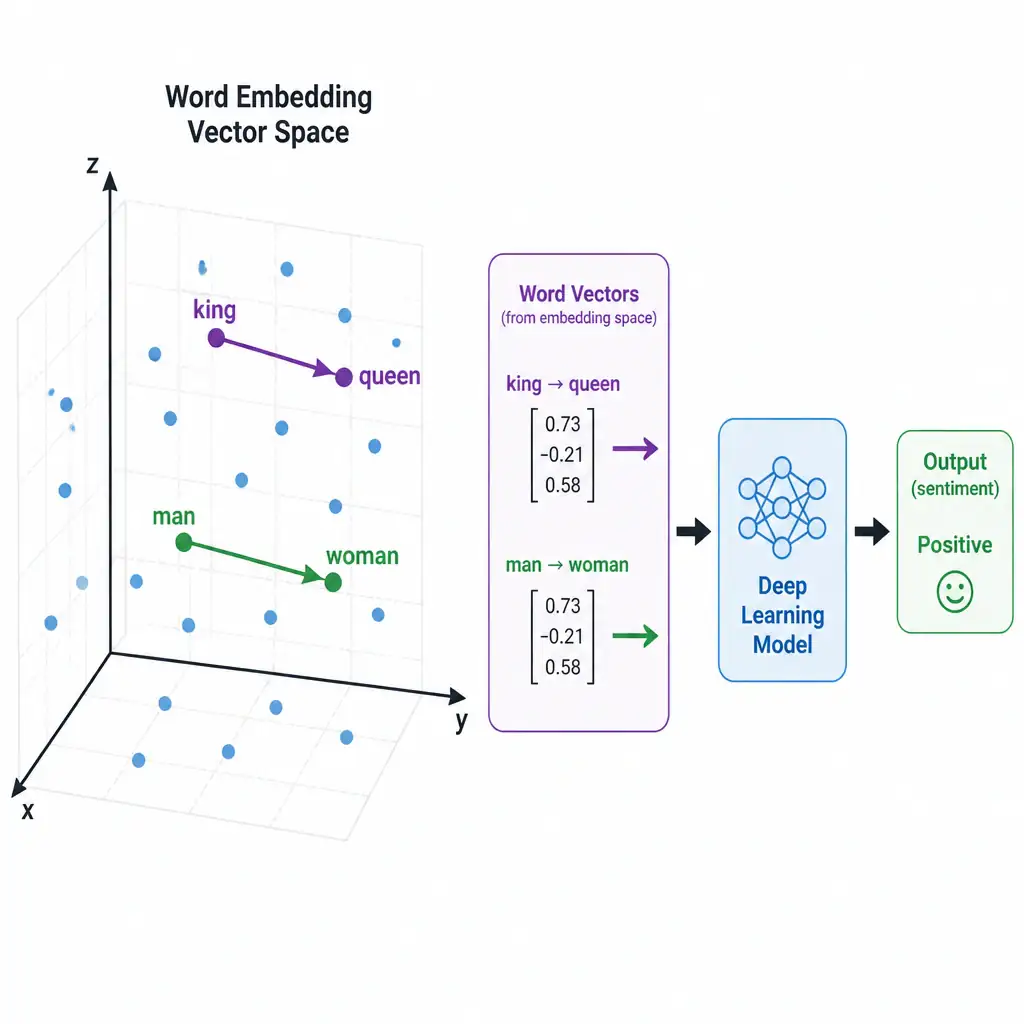
Computers don't understand words, they understand numbers. Word embeddings turn words like 'apple' and 'pear' into dense vector coordinates that sit close together, so you can feed those vectors into neural networks for sentiment analysis or machine translation. Pretty cool, right?
Full Explanation
Word embeddings are a class of techniques in NLP where individual words are mapped to real-valued vectors in a continuous vector space. The key property of word embeddings is that words with similar meanings or semantic contexts are mapped to vectors that are geometrically close to one another, using metrics like cosine similarity.
In downstream applications, word embeddings serve as the fundamental input layer for deep learning models. Instead of using high-dimensional, sparse representations like one-hot encoding, where a vocabulary of 50,000 words requires 50,000-dimensional vectors with a single '1', word embeddings compress words into dense, lower-dimensional vectors, typically 100 to 768 dimensions. These dense vectors capture semantic relationships and are fed as input features into recurrent neural networks, convolutional neural networks, or transformer architectures to perform complex tasks such as sentiment analysis, machine translation, named entity recognition, and question answering. That is why the correct choice is the one describing dense vector representations of words that serve as the input features for neural network models performing tasks like sentiment analysis or machine translation.
The wrong choices fail for different reasons. The choice describing raw inputs to convolutional neural networks to perform high-resolution image classification is incorrect because word embeddings represent linguistic units, not pixel matrices processed by image-classification models. The choice describing policy networks in reinforcement learning to calculate optimal physical movements for robotics is incorrect because reinforcement-learning policy networks use state observations such as positions, velocities, or raw pixels to select actions, rather than utilizing word embeddings. The choice describing a replacement for database indexes to group and sort structured numeric records is incorrect because database indexing is a computer science data structures problem, typically solved with balanced tree indexes or hash tables to accelerate queries, not a semantic NLP embedding task.