
In a standard Natural Language Processing (NLP) pipeline, what preprocessing step is typically performed immediately after text has been split into tokens?
Select an answer to reveal the explanation.
Short Explanation
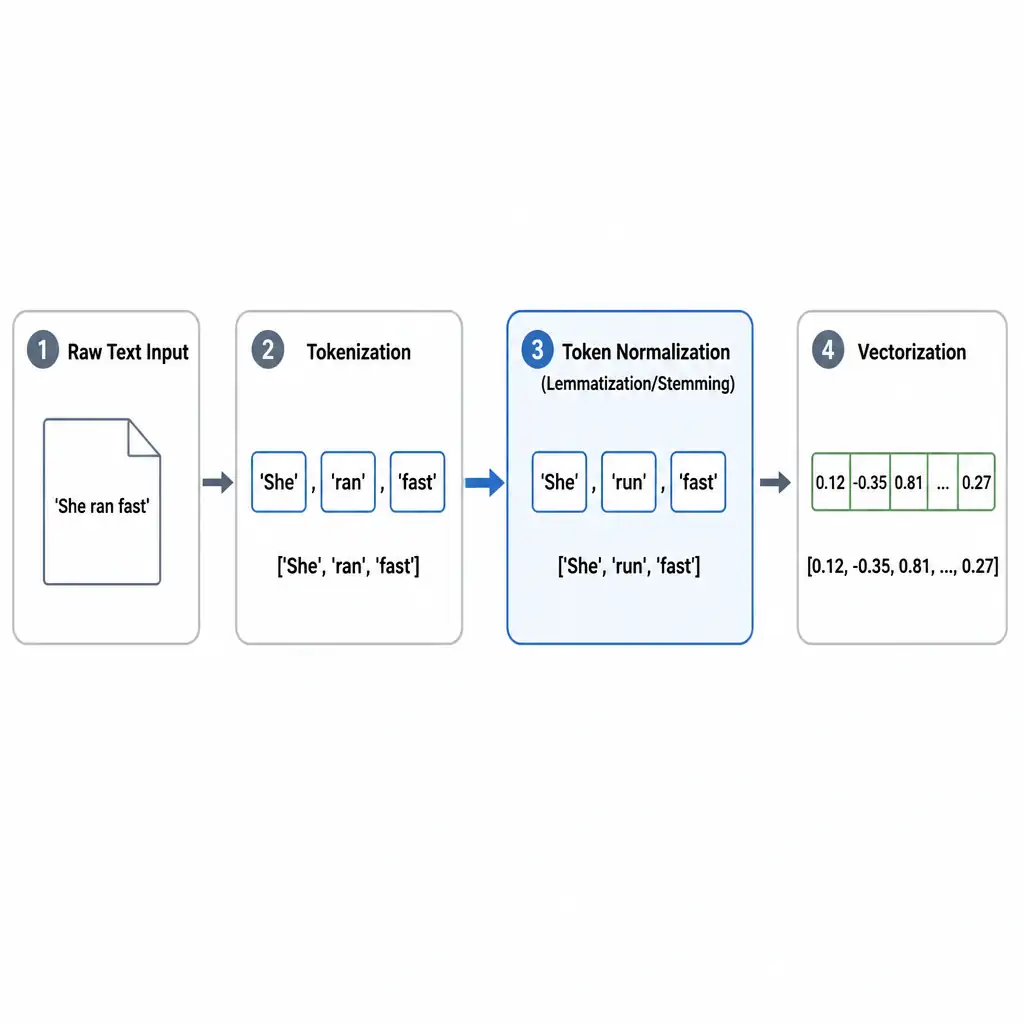
Here's the deal: after you split raw text into tokens, those tokens are still messy with plurals, verb tenses, and capitalization. You normalize them next with stemming or lemmatization so your model sees clean base forms before training or prediction. Get your tokens clean first, then feed them to your model.
Full Explanation
In an NLP pipeline, tokenization is the foundational step where raw character sequences are parsed and split into individual structural units called tokens, typically words, subwords, or characters. Once tokenization is complete, the tokens must undergo normalization before they are converted into numerical representations for model training or inference. This normalization step typically involves stemming or lemmatization. Stemming is a heuristic process that chops off the ends of words, such as converting 'flying', 'flew', and 'flies' to 'fli'. Lemmatization uses vocabulary databases and morphological analysis to return the base dictionary form, or lemma, of a word, such as converting 'better' to 'good' or 'running' to 'run'. Performing this immediately after tokenization ensures that subsequent vectorization steps, such as Bag-of-Words, TF-IDF, or word embeddings, map semantically related tokens to the same feature index, reducing vocabulary sparsity. The dataset-splitting choice is incorrect because dataset splitting into training and validation sets is an overall machine learning workflow step that occurs at the dataset level, not a step within the text token preprocessing sequence. The model-weight serialization choice is incorrect because saving model weights to disk occurs after model training, which is at the very end of the development lifecycle. The final model inference choice is incorrect because making predictions occurs after the model has been fully trained and all preprocessing and feature extractions are complete.