
A software engineer wants to extract names of organizations, locations, and dates from a large volume of multi-lingual text using the spaCy library. Which feature of spaCy makes it highly suitable for this Named Entity Recognition (NER) task?
Select an answer to reveal the explanation.
Short Explanation
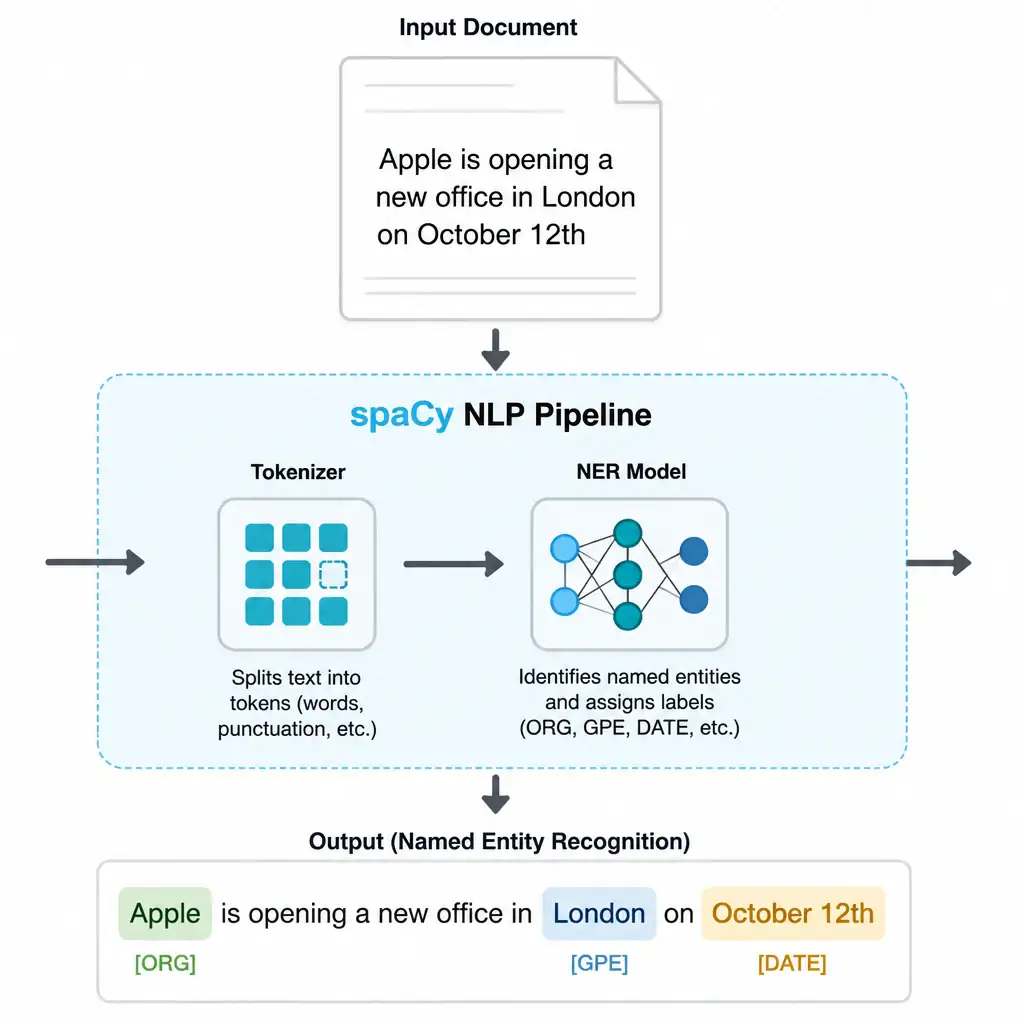
Check this out: spaCy is like the Swiss Army knife of industrial-strength NLP. If you need to find organizations, locations, and dates in multi-lingual text, you can load pre-trained pipeline models and let them detect, locate, and classify entities out of the box. It's fast, efficient, and ready for production without weeks of training or endless regex work.
Full Explanation
spaCy is an open-source library for advanced Natural Language Processing in Python, designed specifically for production use. One of its standout capabilities is Named Entity Recognition (NER)—the process of identifying and categorizing key entities in text (such as names of people, organizations, locations, quantities, and dates).
The key feature that enables spaCy to perform NER so efficiently is its suite of pre-trained pipelines. spaCy provides pre-trained statistical models and transformer-based pipelines for a wide variety of languages (including English, Spanish, German, French, and Japanese). These models are already trained on large, annotated corpora (such as OntoNotes or Wikipedia), allowing them to recognize standard entity types immediately without requiring the developer to label data or train a model from scratch. That is why the approach that offers pre-trained pipeline models across multiple languages that can automatically detect, locate, and classify named entities out of the box is the correct fit for extracting organizations, locations, and dates from large volumes of multi-lingual text.
The approach that requires the developer to manually define regular expression patterns for every possible entity type before running extraction is incorrect because spaCy's primary NER mechanism is statistical/deep learning model-based, not reliant on manual regex patterns, although rule-based matching can be added if desired. The approach that compiles all text into C++ executables that can only execute NER on small, single-sentence inputs is incorrect because spaCy is highly optimized (written in Cython) and designed to process massive datasets and long documents efficiently, not just small inputs. The approach that relies exclusively on active internet connections to query cloud APIs for entity resolution is incorrect because spaCy runs completely locally and offline; it does not require an active internet connection or cloud API calls to perform inference.