
When designing a tokenizer for a machine learning model to process natural language, which of the following statements is technically accurate?
Select an answer to reveal the explanation.
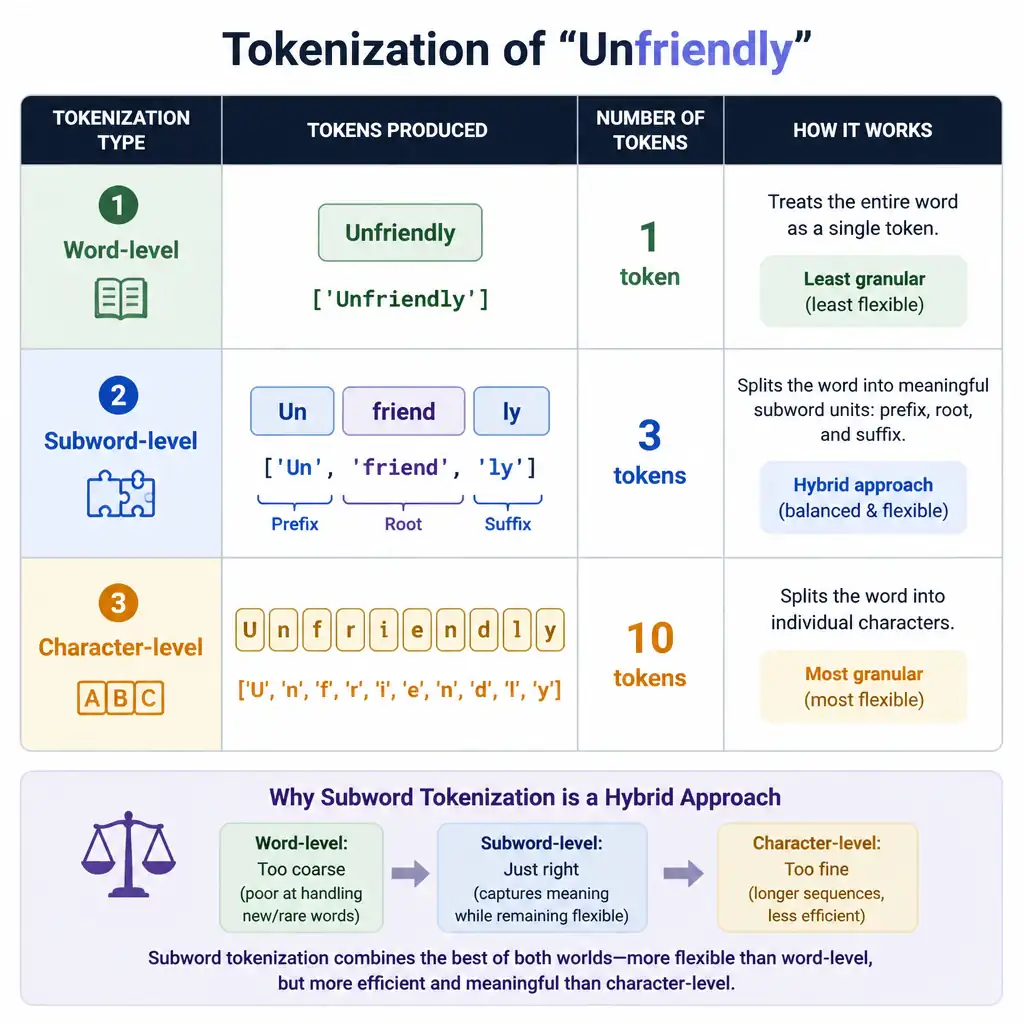
Short Explanation
Check this out: tokenization is how you translate human speak into something a computer can actually digest. You've got choices: split text by whole words, individual characters, or subwords, and the best choice depends on vocabulary size and the task. Subword tokenization is what modern models use because it handles typos and weird words without blowing up vocabulary size.
Full Explanation
Tokenization is the process of breaking a stream of text into smaller, meaningful pieces called tokens. There are three primary levels of tokenization used in modern NLP:
1. Word-Level Tokenization: splitting text based on whitespace and punctuation. While intuitive, it results in a massive vocabulary size and cannot handle out-of-vocabulary words (e.g., typos or new terms). 2. Character-Level Tokenization: treating every individual character as a token. This completely eliminates out-of-vocabulary errors and keeps vocabulary size very small, but it results in extremely long sequences that lose word-level semantic features and increase computational load. 3. Subword-Level Tokenization: the standard in modern transformer models (e.g., byte-pair encoding, WordPiece). It splits frequent words into full words and infrequent words into subword pieces (e.g., 'unbelievable' becomes 'un' + 'believable'). This strikes a balance: it manages vocabulary size, avoids out-of-vocabulary errors, and retains semantic structure.
The correct statement is the one saying tokenization can be performed at the word, subword, or character level, with the optimal choice depending on the vocabulary size and the specific task. That matches the facts above: each level has tradeoffs, so the best level depends on the model, task, and vocabulary constraints.
The statement saying tokenization must always be executed at the character level to prevent any out-of-vocabulary errors is incorrect. Character-level tokenization does eliminate out-of-vocabulary errors, but it is not required and is not always optimal; it loses word-level semantics and creates very long sequences. Subword tokenization is widely preferred in modern architectures because it avoids out-of-vocabulary errors while keeping vocabulary size manageable.
The statement saying tokenization is a post-processing technique applied only after a model outputs its final predictions to make them human-readable is incorrect. Tokenization is an input preprocessing step, not a post-processing step. Models consume tokenized input.
The statement saying tokenization is only used in classification tasks and is bypassed entirely in generative language models is incorrect. Generative language models rely heavily on tokenization to parse prompt inputs and structure generated token predictions.