
The Transformer model revolutionized NLP by replacing older sequential architectures. Which core building block is found in both the encoder and decoder layers of a standard Transformer architecture?
Select an answer to reveal the explanation.
Short Explanation
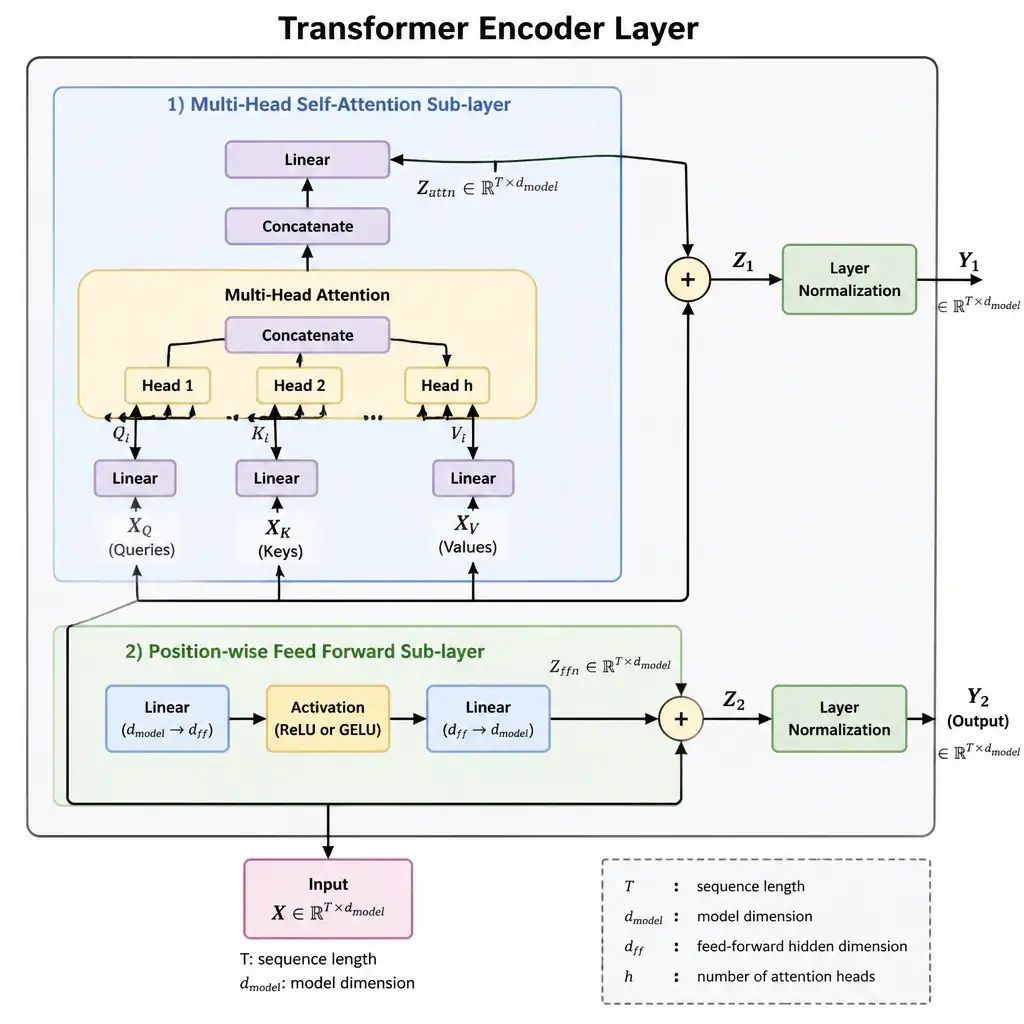
When you open a standard Transformer block, the piece you'll find in both encoder and decoder layers is the Multi-Head Self-Attention module. It lets the model weigh relationships across the whole sequence in parallel, so if you remember one Transformer term for the exam, make it attention.
Full Explanation
The Transformer architecture, introduced in the seminal paper "Attention Is All You Need," relies on a modular block structure that repeats across both the encoder and decoder stacks. The defining characteristic of the Transformer is its complete omission of recurrence (RNNs) and convolution (CNNs) for sequence processing. The core component within each Transformer layer is the Multi-Head Self-Attention module. This module allows the model to process input sequences in parallel by dividing the attention mechanism into multiple "heads." Each head projects queries, keys, and values into different representation spaces, allowing the model to attend to information from different representation subspaces at different positions simultaneously. For example, one head might track syntactic relations (subject-verb agreement), while another focuses on semantic associations (connecting pronouns to the correct noun phrases). The Bidirectional Recurrent Units (BRUs) choice is incorrect because recurrent units (such as GRUs or LSTMs) are deliberately excluded from the Transformer architecture to allow parallel processing. The 2D Spatial Pooling Layers choice is incorrect because pooling layers are primarily used in Convolutional Neural Networks (CNNs) for computer vision tasks to reduce spatial dimensions, not in standard Transformers. The Residual Dilated Convolutional Filters choice is incorrect because standard Transformers do not use dilated convolutional filters, which are characteristic of CNN architectures like WaveNet.