
When constructing a deep learning model for text analysis in PyTorch, a developer includes the torch.nn.Embedding module as the first layer. What is the primary function of this module during the forward pass?
Select an answer to reveal the explanation.
Short Explanation
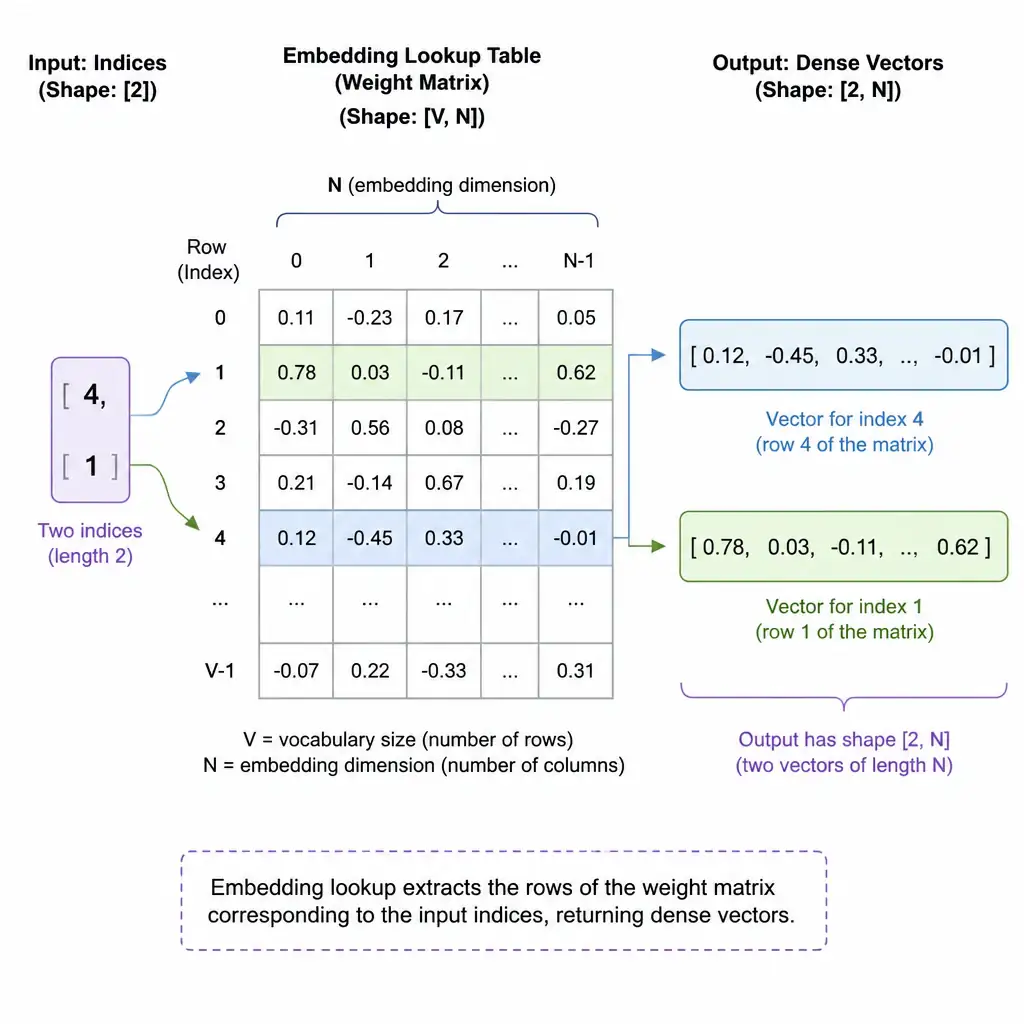
Let's get practical with PyTorch: you can't feed raw strings or integer word numbers straight into linear layers. torch.nn.Embedding is a lookup table that turns those numbers into dense, fixed-size vectors the model can learn from. Keep this straight for the exam: it maps discrete tokens into continuous space.
Full Explanation
In PyTorch, the torch.nn.Embedding module acts as a lookup table that maps discrete tokens (represented by integer indices) to dense, continuous vectors. When building models for NLP, input text is first tokenized, and each unique token is assigned an integer index from a vocabulary dictionary. However, integer values carry no inherent semantic meaning (e.g., index 5 is not mathematically related to index 6). In effect, it replaces a high-dimensional sparse representation with a lower-dimensional dense vector of a predetermined size.
The embedding layer translates these sparse integer indices into dense, floating-point vectors of a fixed size (the embedding dimension, e.g., 128, 256, or 512). The module initializes a weight matrix of shape (num_embeddings, embedding_dim). During the forward pass, the input tensor of token indices is used to index into this weight matrix, retrieving the corresponding row vector for each token. Importantly, these embedding vectors are learnable parameters. During model training, backpropagation adjusts these vector values, allowing the network to group semantically similar words closer together in the vector space.
Let's examine the incorrect approaches: - The approach that categorizes raw token indices directly into class probabilities using a softmax activation function is incorrect because text classification is typically performed by the final output layer (e.g., a linear layer followed by softmax), not the initial embedding layer. - The approach that applies spatial filters across characters to identify regional patterns, mimicking a one-dimensional convolution, is incorrect because spatial filtering across sequences is the job of convolutional layers (torch.nn.Conv1d), not embedding layers. - The approach that calculates the attention weights between every pair of input tokens in a sequence is incorrect because calculating attention weights is the role of attention layers (torch.nn.MultiheadAttention), not standard embeddings.