
An engineer building a sentiment classifier notices that highly frequent but uninformative words (such as 'really', 'extremely', and 'very') are dominating the model's feature weights and skewing the classification outputs. Which preprocessing step should the engineer implement to address this issue?
Select an answer to reveal the explanation.
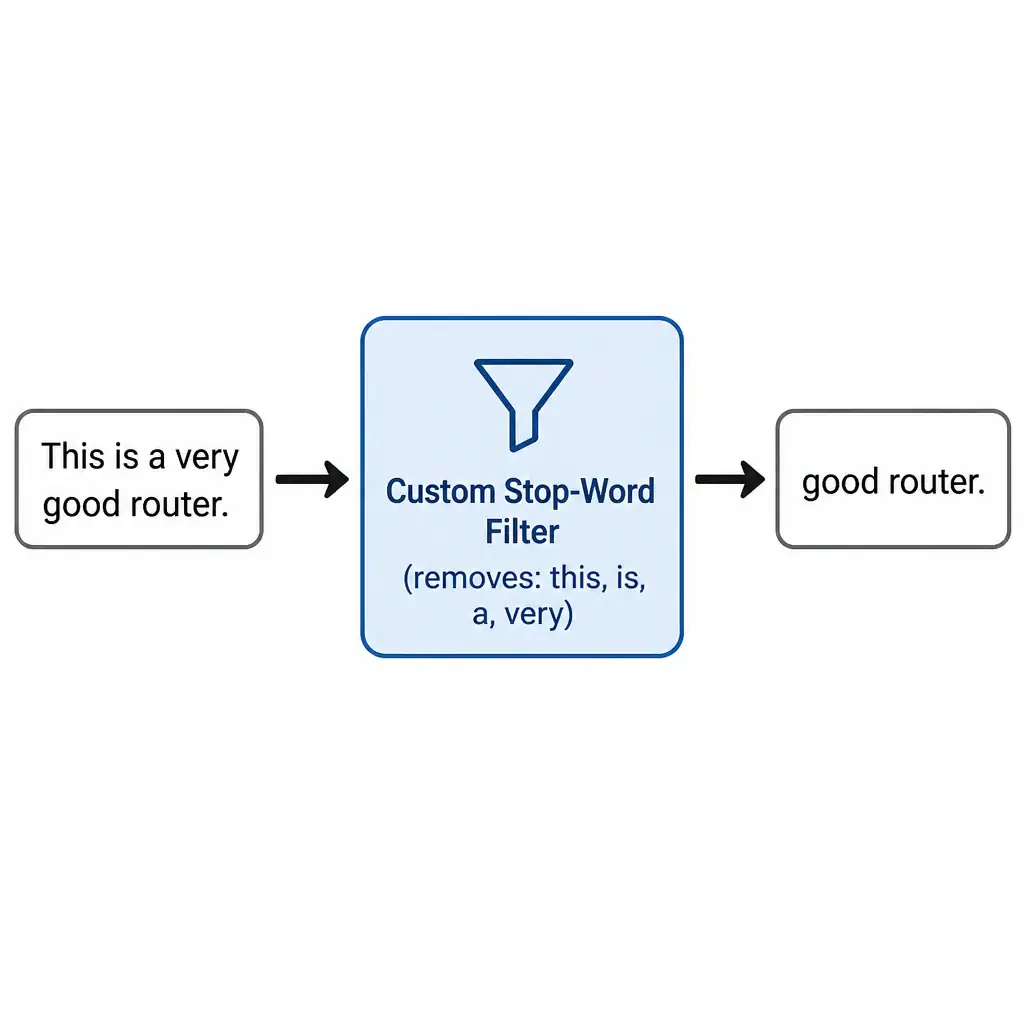
Short Explanation
You're seeing words like 'really' and 'very' dominate your sentiment classifier because they're common, low-value stop words. Remove them with a custom stop-word list so your model focuses on words that actually signal sentiment. The other steps just reshape or split words; they don't filter out the noise.
Full Explanation
Stop words are words that occur frequently in a language but carry minimal semantic information (such as 'the', 'a', 'is', 'and', 'with'). In many text mining and classification tasks, these words can dominate frequency counts and feature representations without contributing useful signal, which can skew the performance of algorithms like Naive Bayes or TF-IDF.
To solve this, developers perform stop-word removal during the text preprocessing phase. While standard NLP libraries (such as NLTK or spaCy) provide default stop-word lists, these lists may not cover all domain-specific or task-specific uninformative words. In this scenario, words like 'very' and 'really' are causing noise. The engineer should modify the default stop-word list to include these custom terms so they are filtered out before vectorization and model training.
Let's review the incorrect approaches: - Lemmatization reduces words to their dictionary root form (e.g., 'running' -> 'run'), but it does not filter out or remove words from the text. - Stemming trims prefixes or suffixes using heuristic rules (e.g., 'really' -> 'real'), but again, it does not discard the words. - Tokenization is the basic step of splitting a text string into individual words or tokens, which is necessary before any filtering or normalization can occur, but it does not remove noise words.
For the exam, remember that filtering out frequent, uninformative words to improve model performance is called stop-word removal, and it can be customized with a user-defined list.