
When preprocessing text for a machine learning model, a developer decides to represent words using one-hot encoding. Which of the following best describes this representation and its primary drawback?
Select an answer to reveal the explanation.
Short Explanation
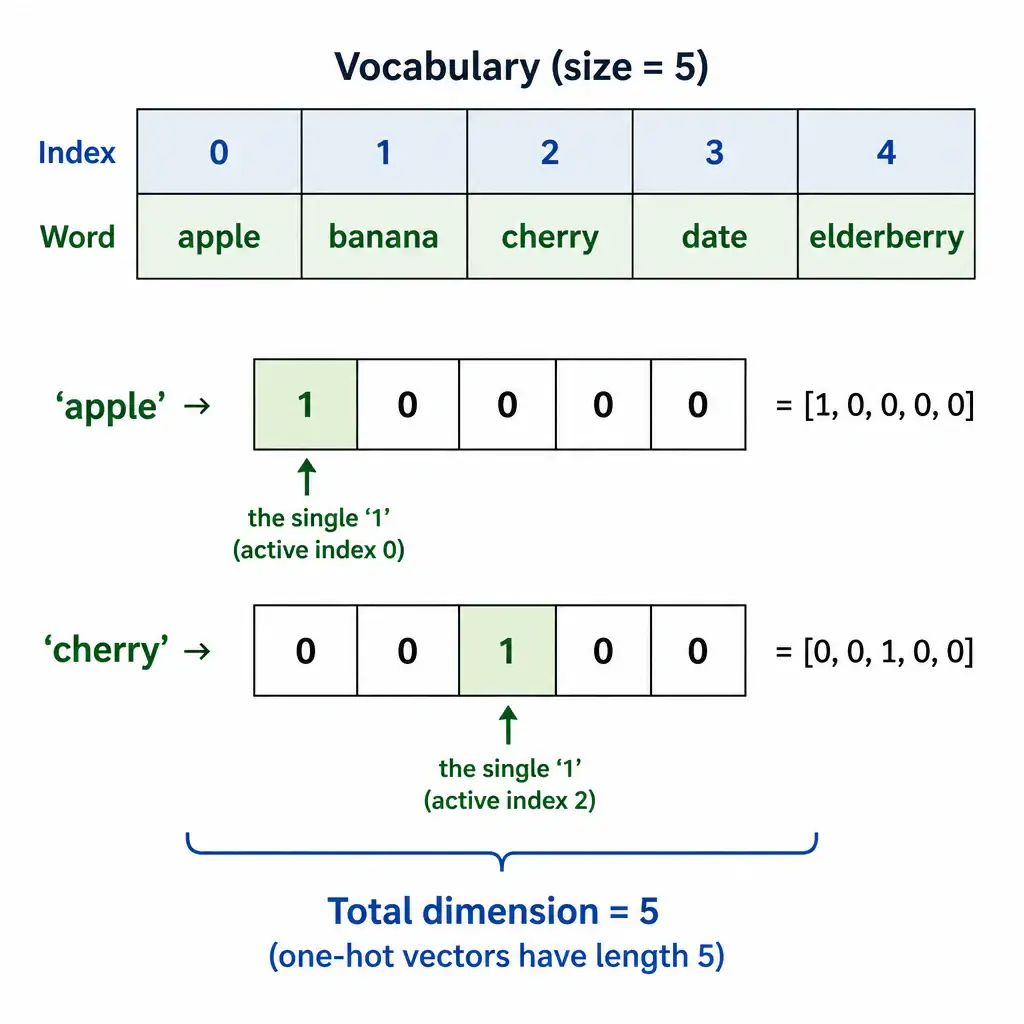
Think of one-hot encoding as a huge light switchboard where only one switch can be on at a time. If your vocabulary has 10,000 words, every word becomes a 10,000-item vector with one 1 and thousands of 0s. That's a lot of wasted space, and it creates high dimensionality.
Full Explanation
One-hot encoding is a classic technique used to convert categorical variables, such as words in a vocabulary, into a numerical format that machine learning algorithms can process. In this scheme, a vocabulary of size $V$ is established. Each unique word is assigned a vector of length $V$. In this vector, the index corresponding to the word's position in the vocabulary is set to 1, while all other $V-1$ elements are set to 0.
While simple to implement, one-hot encoding has two major limitations. First, it leads to high-dimensional, sparse representations. If a corpus contains 50,000 unique words, each word is represented by a 50,000-dimensional vector consisting almost entirely of zeros. This is computationally expensive and memory-inefficient. Second, one-hot encoding treats all words as equidistant and independent, completely failing to capture semantic relationships (for example, the vector for 'cat' has no more similarity to 'dog' than it does to 'refrigerator').
The description of low-dimensional dense vectors of real numbers matches word embeddings, such as Word2Vec, GloVe, or FastText, which represent words as low-dimensional dense vectors of continuous values, not sparse one-hot vectors.
The description of filtering out common filler words describes stop word removal, which is a preprocessing step to remove frequent, low-information words, not a vector encoding scheme.
The description of representing words as single unique integers describes label encoding or integer encoding, where each word is mapped directly to a single integer (for example, 'cat' = 1, 'dog' = 2), which is not a vector representation.
Remember for the exam: one-hot encoding creates a sparse vector of size $V$ where a single element is 1, leading to sparse representation and high dimensionality.