
A developer is writing a Python script to preprocess text for an NLP model. Instead of using Python's built-in string.split() method, they decide to use a dedicated tokenizer from a library like spaCy. Why is using spaCy a better choice for this task?
Select an answer to reveal the explanation.
Short Explanation
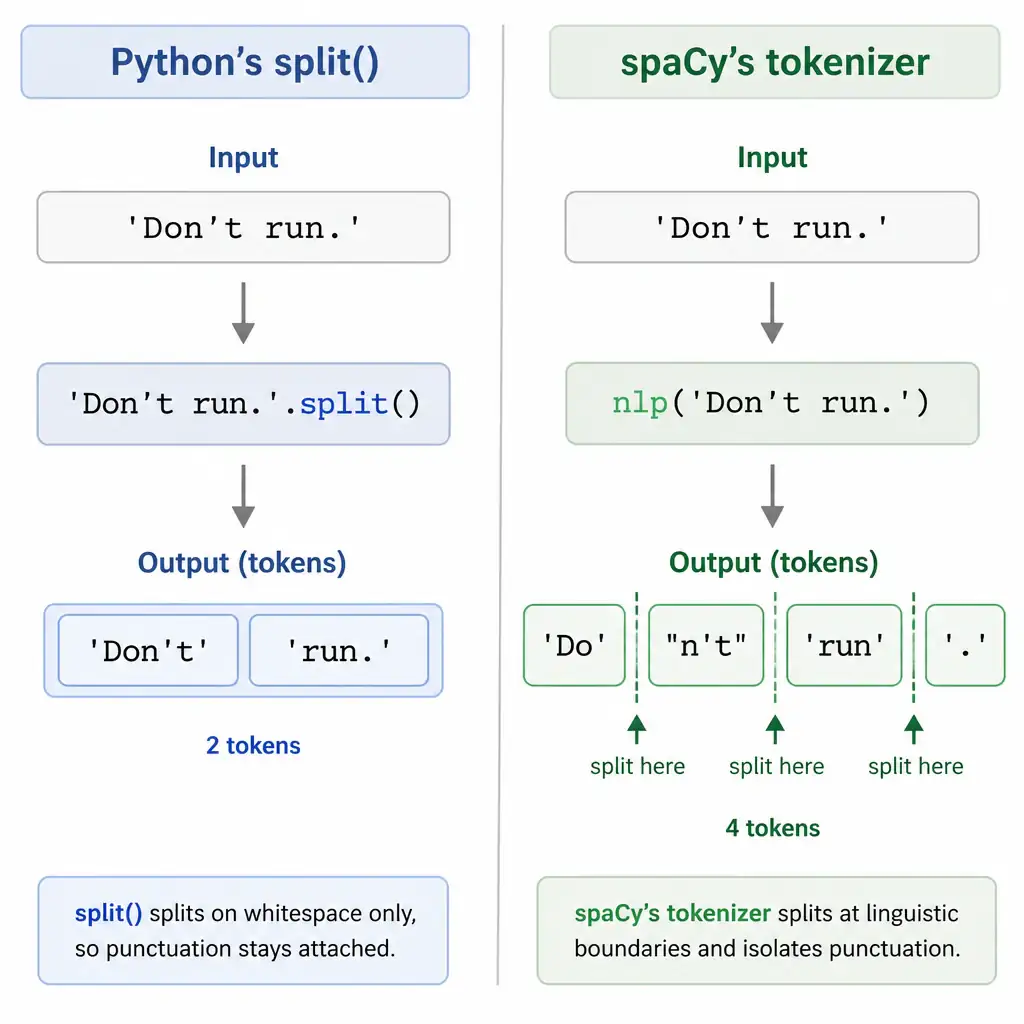
You should use a dedicated NLP tokenizer because it understands language, not just spaces. It splits contractions, punctuation, and messy whitespace into clean tokens your model can use. Python's split() just chops on spaces, so you get dirty tokens like 'don't' or 'network.'
Full Explanation
Tokenization is the process of breaking down a continuous string of text into smaller, meaningful units called tokens (such as words, subwords, or punctuation marks). While Python's built-in split() method divides a string based on a specified delimiter (defaulting to whitespace), it does so without any understanding of language. As a result, a simple split() will fail to isolate punctuation from adjacent words (e.g., 'system.' becomes the token 'system.'), which negatively affects downstream NLP tasks because the model treats 'system' and 'system.' as two entirely different vocabulary items. Furthermore, split() cannot handle contractions correctly (e.g., splitting 'we'll' into 'we' and ''ll' or 'cannot' into 'can' and 'not') or handle multi-word expressions and irregular spacing. Dedicated NLP tokenizers, like those in spaCy, use complex language-specific rule sets and models to segment text. They recognize that punctuation should usually be treated as separate tokens, that contractions carry distinct semantic parts, and that multiple spaces should not result in empty string tokens. The correct choice is the statement that dedicated NLP tokenizers use linguistic rules to handle complex structures like contractions, punctuation, and varying whitespace. The claim that Python's native split() method is deprecated and will throw runtime syntax errors is incorrect because split() is a perfectly valid and active Python string method, not deprecated. The claim that built-in string methods cannot split strings that contain numerical digits or special characters is incorrect because split() can easily process strings containing numbers or special characters; it simply splits them blindly at whitespaces. The claim that string splitting is significantly slower and uses more RAM than loading a complete spaCy language model is incorrect because split() is actually much faster and uses far less memory than spaCy because it does no linguistic processing and doesn't require loading a model into memory. However, the speed benefit of split() is offset by its lack of accuracy for NLP tasks. For the exam, remember: linguistic tokenizers are preferred over simple character/space splits because they handle punctuation, contractions, and linguistic rules correctly.