
When planning a new Natural Language Processing project, a development team gathers millions of emails, articles, and chat transcripts to train a specialized model. What term describes this broad collection of text data?
Select an answer to reveal the explanation.
Short Explanation
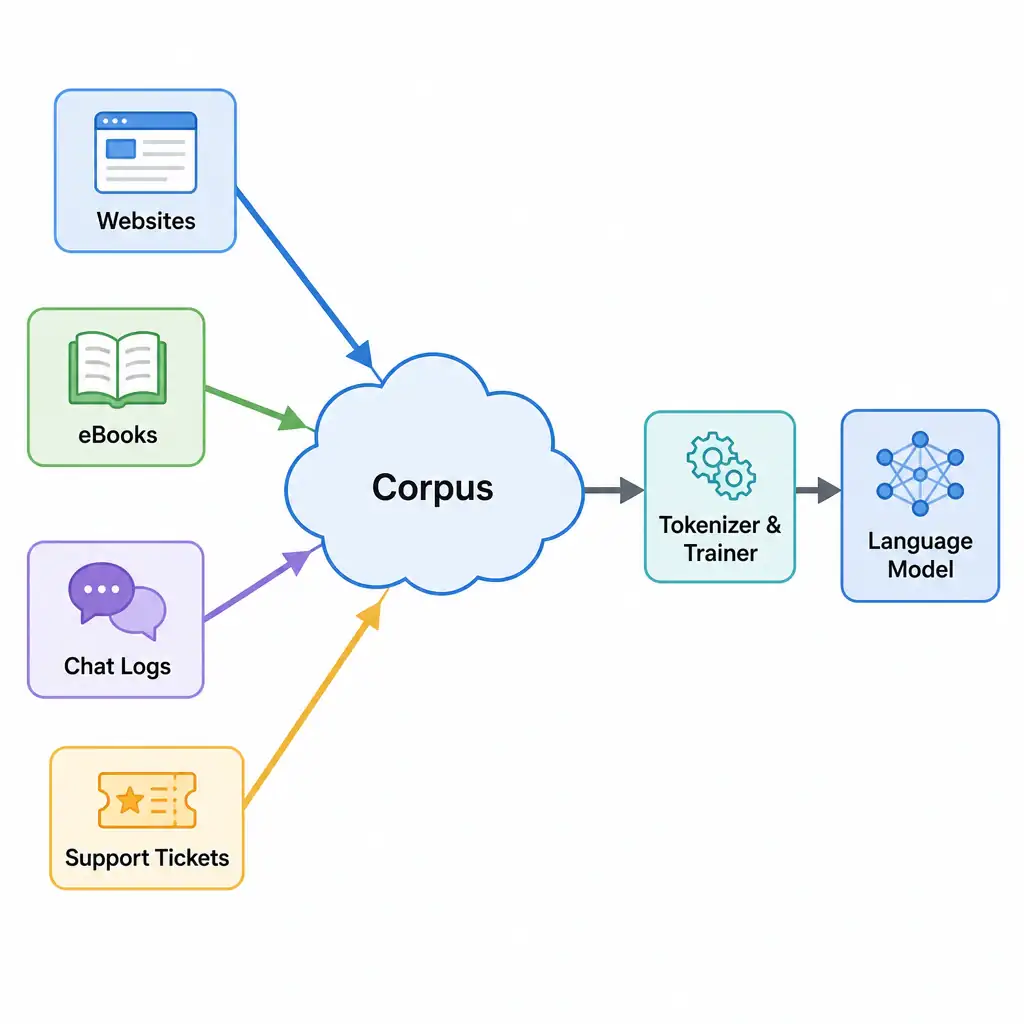
Okay, let's dive in. Think of a corpus like your training ground or library, because a model needs a massive pile of real-world text to learn patterns. That giant bucket of emails, articles, and transcripts is a text corpus.
Full Explanation
In Natural Language Processing, the term 'corpus' (plural: 'corpora') refers to a large and structured set of texts. These texts are gathered and prepared specifically for statistical analysis, training language models, or testing linguistic hypotheses. The corpus can consist of a single language, multiple languages (a parallel corpus), or domain-specific texts (such as legal briefs, medical journals, or customer emails).
The quality and size of the corpus directly determine how well an NLP model can learn linguistic features, syntactical structures, and semantic relationships. Modern large language models are trained on massive web-scale corpora comprising billions or trillions of tokens to build a general understanding of language before being fine-tuned on smaller, task-specific corpora.
The other choices are incorrect: - The NLP software library choice, such as spaCy, NLTK, or Hugging Face Transformers, is a software package containing tools, algorithms, and code, not the raw text data itself. - The tokenized vocabulary choice is not the broad collection of text data; it is the set of unique tokens produced when text is tokenized. The single document or sentence is too small to be considered a corpus, although it may be a member element of a corpus. - The single word token choice is referred to as a word, character, or token, which is the basic unit of text analysis, not a full text collection.
For your exam, remember that a corpus is the underlying dataset of text documents used to train or evaluate NLP algorithms.