
A developer is building an application to automatically extract dates, times, and specific currency values from incoming email text. Which Natural Language Processing (NLP) task is most appropriate for this requirement?
Select an answer to reveal the explanation.
Short Explanation
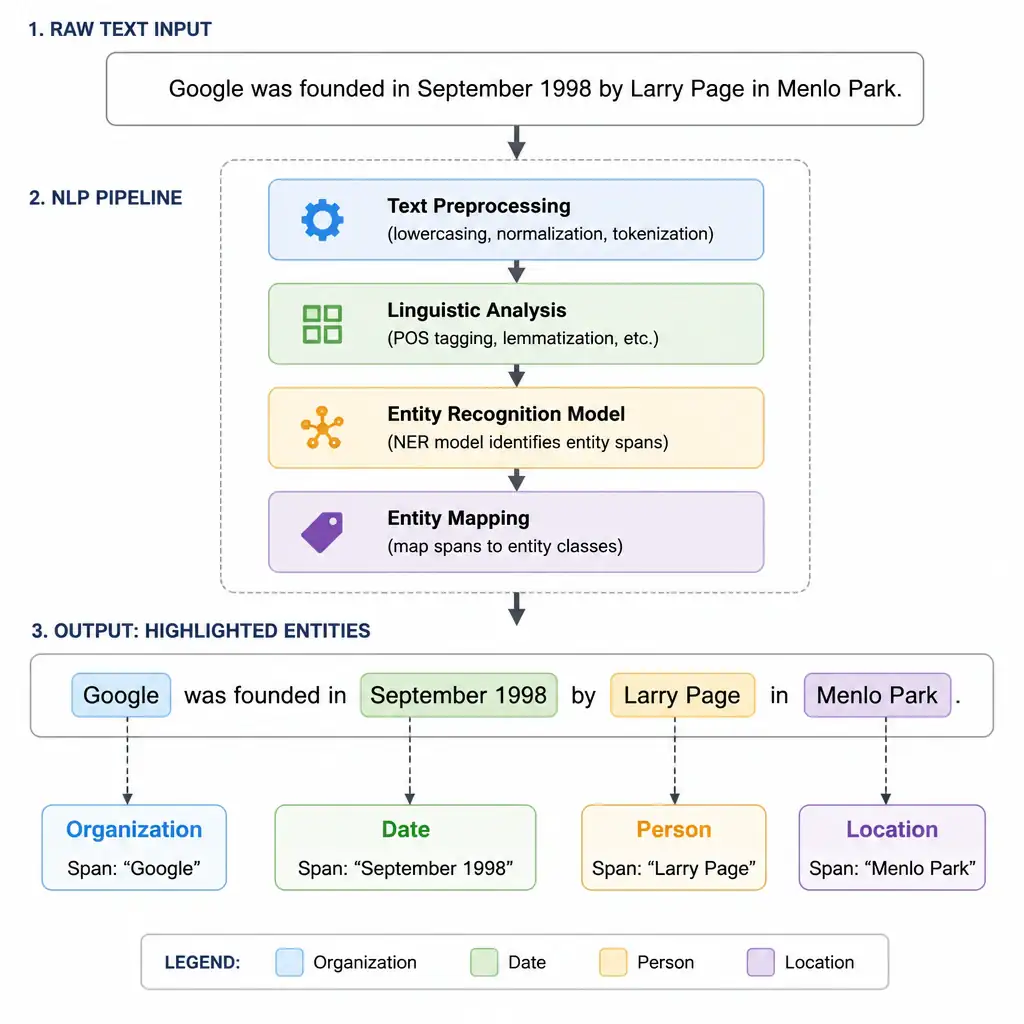
Here's the deal: when you need to pull dates, times, and currency values out of email text, you use Named Entity Recognition. It's like a high-tech highlighter that marks names, dates, places, and money without making you write brittle regexes. The other tasks do completely different jobs.
Full Explanation
Named Entity Recognition (NER) is a fundamental subtask of Natural Language Processing (NLP) designed to identify and categorize specific entities within unstructured text. In a typical implementation, NER algorithms classify words or phrases into predefined categories such as names of persons, organizations, locations, monetary values, percentages, dates, and times.
NER works by utilizing sequence labeling algorithms. For example, a modern transformer-based model will assign labels to each token, such as using the Beginning, Inside, Outside tagging scheme, to mark the boundaries of entities. This is highly useful for downstream tasks such as information extraction, search query optimization, and structured database population from raw documents.
Let's review the incorrect choices to understand why they are distractors: - The sentiment analysis option is the process of identifying and categorizing opinions or emotions expressed in text (for example, classifying a review as positive, negative, or neutral), rather than extracting specific datatypes. - The document summarization option, or summary of the text, is the process of shortening a document to create a concise representation of its main points, which is a generative or extractive task focusing on global meaning rather than tagging local entity spans. - The language modeling option is the foundational task of predicting the probability of a sequence of words or generating the next word in a sequence based on context (as seen in models like GPT).
For the exam, remember that extracting discrete real-world concepts (like people, dates, times, and places) from raw text is the hallmark of Named Entity Recognition.